
Many of today’s most capable AI systems need to balance two competing goals: they must know a great deal, yet respond quickly enough to be useful. Mixture-of-Experts, usually shortened to MoE, is one important architectural idea for meeting that challenge.
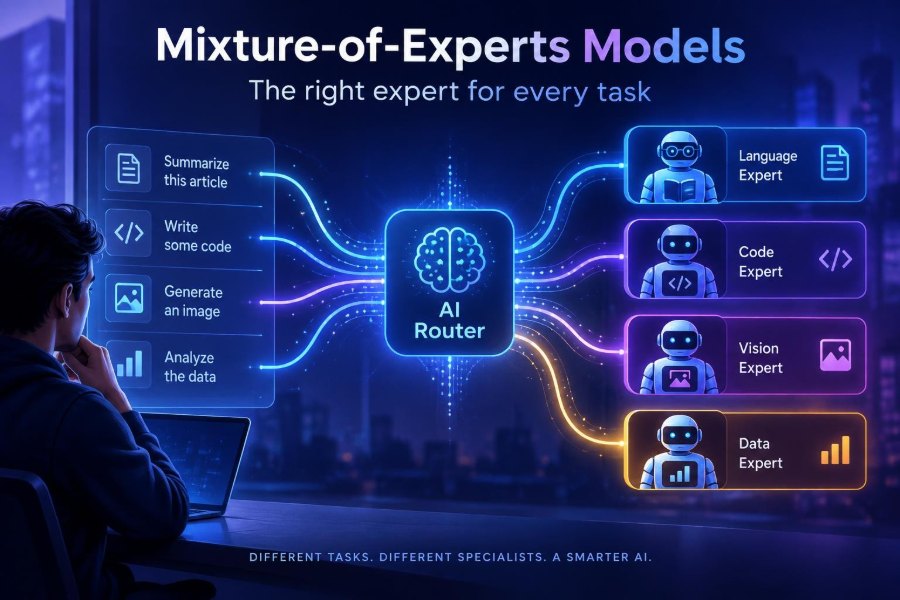
Instead of sending every request through one enormous, uniform neural network, an MoE model can choose a small set of specialized components for each token or task. Think less like asking an entire company to answer every email, and more like routing work to the few teams best equipped to handle it.
This matters now because MoE ideas increasingly shape the models developers access through APIs, open-weight checkpoints, and local inference stacks. You do not need to train one to benefit from understanding its trade-offs.
After reading, you will be able to explain MoE models clearly, recognize when sparsity affects cost and performance, experiment with simple routing concepts, and make better practical choices when building AI products.
🧠 1. Start with the simple idea: specialists plus a router
A conventional dense neural network activates essentially the same model structure for every input. Its learned parameters may respond differently, but every layer’s relevant computation is generally performed for every token.
An MoE layer introduces two roles:
- Experts: multiple learned subnetworks, often feed-forward networks, that can develop different capabilities.
- A router: a small learned function that decides which experts should process each token.
For the phrase “write a database query,” the router might favor experts that have become useful for structured code. For a multilingual sentence, it may favor a different pattern of experts. These are tendencies learned from training data, not manually assigned job titles.
🚦 2. Understand routing one token at a time
Language models generate and process text as tokens: pieces of words, punctuation, or whole short words. In a typical sparse MoE layer, routing happens for each individual token, not just once for an entire prompt.
The router produces a score for each expert. It selects the top one, top two, or another small number of candidates, then combines their outputs using routing weights.
token representation x
       |
       v
router scores: [expert A: 0.08, B: 0.61, C: 0.24, D: 0.07]
       |
       v
top-2 selection: B and C
       |
       v
weighted output = 0.61 × B(x) + 0.24 × C(x)
The exact scoring, normalization, and selection method varies by architecture. The essential feature is conditional computation: only a fraction of the available experts run for a given token.
⚖️ 3. Separate total parameters from active parameters
MoE discussions often sound confusing because two parameter counts can both be true. A model may contain a very large total number of stored parameters while activating a much smaller number for any one token.
| Term | What it means | Why it matters |
|---|---|---|
| Total parameters | All parameters across shared layers and every expert | Influences model storage and training capacity |
| Active parameters | The subset used for one token’s forward pass | More closely relates to per-token compute |
| Dense model | Most parameters are used for each token | Simple, predictable compute pattern |
| Sparse MoE model | Only selected experts run per token | Can increase capacity without proportional compute |
Active parameters are not a universal measure of speed. Memory bandwidth, expert placement, batching, routing overhead, sequence length, and hardware topology can substantially affect real latency.
🏭 4. Use the factory analogy, but do not take it too literally
Imagine a factory with many stations: translation, arithmetic, code formatting, scientific notation, and conversational writing. A dispatcher sends each item to a few appropriate stations instead of every station.
This is a helpful mental model, but experts are not guaranteed to map neatly to human concepts. One expert may help with several unrelated patterns, while a task can rely on many layers and experts. Researchers often inspect routing behavior, yet “this expert is the legal expert” is usually an oversimplification.
📈 5. See why MoE became attractive
Training a stronger dense model often means increasing computation for every token. MoE offers a different scaling path: add more expert capacity, then keep the number of selected experts relatively small.
Potential benefits include:
- Higher representational capacity at similar per-token activation budgets.
- More opportunities for different data patterns to use different computational paths.
- Efficient scaling for training workloads that can distribute experts across devices.
The word “potential” matters. An MoE model is not automatically better than a comparable dense model. Results depend on data, training design, routing stability, hardware, and the evaluation task.
🧮 6. Follow a compact mathematical view
Let x be a token representation, E_i(x) be expert i, and g_i(x) be the router’s score. If S(x) is the selected set of experts, an MoE layer can be written conceptually as:
y = Σ over i in S(x) of g_i(x) × E_i(x)Usually, S(x) contains only a few experts out of many. The model learns both the expert functions and the routing function through training.
In transformer-based language models, MoE commonly replaces some dense feed-forward blocks while attention layers and other components remain shared. That combination preserves shared context processing while making selected transformations sparse.
🧰 7. Identify the MoE details that matter in model documentation
When evaluating an MoE model, look beyond a single headline parameter count. Official model cards, technical reports, and repository documentation are the best sources because implementation details vary quickly.
- Number of experts: how many candidate subnetworks exist in an MoE layer.
- Top-k routing: how many experts each token activates.
- Shared experts: whether any experts run for every token alongside routed experts.
- Layer placement: which transformer layers are MoE versus dense.
- Context and serving requirements: practical constraints that affect deployment.
Do not infer quality, RAM needs, or throughput from expert count alone. Test the actual checkpoint and runtime on representative workloads.
🔀 8. Learn what makes routing difficult
A router can fail in a surprisingly simple way: it may send too many tokens to a few popular experts. Those experts become overloaded while others receive little training signal and remain underused.
Training systems address this with load-balancing objectives, capacity controls, routing noise, or related techniques. The goal is not perfectly equal traffic at all times; it is productive utilization without chronic collapse onto a tiny subset.
Each expert may also have a token capacity for a batch. If too many tokens select it, implementations must reroute, drop, or otherwise handle overflow. This is one reason batch composition can affect behavior and efficiency.
💻 9. Build intuition with a tiny routing prototype
The following illustrative Python-like code is not a trainable production MoE layer. It shows the basic top-k selection and weighted combination pattern.
import numpy as np

# One token representation, four expert scores
x = np.array([0.2, -0.4, 0.8])
router_scores = np.array([0.10, 0.55, 0.25, 0.10])
top_k = 2

chosen = np.argsort(router_scores)[-top_k:]
weights = router_scores[chosen]
weights = weights / weights.sum()

def expert_1(v): return v * 1.1
def expert_2(v): return np.tanh(v)
def expert_3(v): return v + 0.2
def expert_4(v): return -v
experts = [expert_1, expert_2, expert_3, expert_4]

output = sum(w * experts[i](x) for i, w in zip(chosen, weights))
print(chosen, output)
In a real system, routing scores are learned, tensors are batched, experts are neural modules, and efficient dispatch is crucial. Still, this prototype makes the central operation concrete.
🪜 10. Turn the prototype into a real experiment
If you are learning PyTorch, JAX, or another machine-learning framework, build a small classifier before attempting a language model. Keep the experiment narrow and measurable.
- Create synthetic data with several distinguishable input patterns.
- Build a baseline network with one dense feed-forward block.
- Replace that block with several small expert blocks and a router.
- Select one or two experts per example.
- Log routing frequency, loss, accuracy, and expert overflow.
- Compare results with the dense baseline using the same training budget.
Inspect whether different input clusters get different routes. Useful specialization is an empirical question, not an assumption.
🧪 11. Test model behavior, not just a leaderboard claim
If you use an available MoE model through a hosted service or local runtime, evaluate it as you would any model. Build a compact task suite based on your actual work.
You are evaluating an assistant for data-analysis work.
Given the dataset description below:
1. State assumptions.
2. Propose a validation plan.
3. Write SQL only if the schema supports it.
4. Flag any ambiguous fields.
5. Return a concise answer with a confidence note.

Dataset description: [paste your representative case]
Run the same prompt set against alternatives with consistent settings. Review correctness, groundedness, formatting, latency, cost, and failure patterns. A model’s architecture may be interesting, but your workflow’s measured outcome is what matters.
🗣️ 12. Prompt MoE models normally, with a few operational habits
You generally do not tell a deployed MoE model which expert to use. The router is internal. The best prompting practices remain clarity, context, constraints, examples, and verification.
Use prompts that reduce ambiguity:
Act as a senior code reviewer.

Review the code below for correctness, security, and maintainability.
Return exactly:
- Critical issues
- Suggested patch
- Tests to add
- Assumptions

Do not claim to have executed the code.

Code:
[paste code]- Keep output formats explicit when integrating with software.
- Provide representative examples for specialized domains.
- Split unrelated tasks into separate calls when quality matters.
- Validate generated code and structured output independently.
A common mistake is expecting visible expert-level explanations from the model. Internal routes are not reliable user-facing rationales.
🖥️ 13. Plan deployment around communication, not only FLOPs
In distributed MoE serving, different experts may reside on different accelerators or machines. Tokens must be dispatched to the chosen locations, processed, and returned. This communication pattern can become a bottleneck.
For developers, practical deployment questions include:
- Does the inference engine support the model’s routing architecture efficiently?
- Can the full model weights fit in available memory, including runtime overhead?
- What batch sizes and request patterns produce acceptable latency?
- How are experts partitioned across hardware?
- What happens under peak concurrency and long contexts?
Benchmark your own target hardware. Check current documentation for your model runtime and accelerator stack rather than relying on broad claims from another environment.
📦 14. Avoid three common implementation mistakes
Mistake one: confusing sparse activation with small storage. Even if only a few experts run per token, all expert weights may still need to be loaded or accessible. Quantization and offloading can help in some setups, but they add trade-offs.
Mistake two: ignoring load imbalance. A router that repeatedly picks the same experts can undermine the point of the architecture. Log expert usage distributions during training and serving.
Mistake three: comparing only theoretical compute. Sparse kernels, all-to-all communication, small batches, and poor hardware utilization may erase expected savings. Measure tokens per second and tail latency.
🔍 15. Add observability to AI applications
Most application builders cannot inspect internal expert routes in a hosted model. They can still instrument outcomes that matter: request category, prompt length, output length, latency, tool-call success, validation failures, and user corrections.
For self-hosted models with routing telemetry, aggregate statistics are more useful than one-off screenshots. Watch for sustained expert concentration, capacity overflow, or performance shifts after model and runtime changes.
request_id, task_type, input_tokens, output_tokens, latency_ms, valid_output
r-104, extraction, 820, 124, 1450, true
r-105, code_review, 2100, 390, 3680, true
r-106, extraction, 750, 110, 2310, false
Never log sensitive prompts or model outputs indiscriminately. Design telemetry with data minimization and access controls from the beginning.
🛡️ 16. Treat privacy, safety, and bias as architecture-independent
MoE does not make an AI system inherently private, truthful, safe, or unbiased. It is a way of organizing computation. Models can still hallucinate, reproduce harmful patterns, mishandle confidential data, or generate insecure code.
- Remove or redact personal and confidential information before sending prompts to external services.
- Review the provider’s current data handling, retention, and training policies.
- Use permission boundaries and human approval for consequential actions.
- Test for errors and unfair outcomes across relevant languages, user groups, and edge cases.
- Keep deterministic validation around generated SQL, code, financial guidance, and operational commands.
For regulated or high-impact settings, involve security, privacy, legal, and domain experts early. Routing sophistication does not replace governance.
🌐 17. Watch the trend: sparse systems are becoming a systems problem
The future of MoE is not only about adding more experts. It also involves better routers, more stable training, expert parallelism, efficient communication, adaptive capacity, and runtimes that make sparse execution practical.
Another active area is combining shared computation with routed computation. This can preserve broadly useful knowledge while allowing conditional capacity where it helps most. The exact design choices differ across research and production systems.
For practitioners, the trend means model selection increasingly requires systems thinking. Capability, memory footprint, throughput, reliability, evaluation quality, and privacy posture belong in the same decision.
✅ 18. Use this quick-start checklist
- Explain: describe MoE as experts selected by a learned router.
- Distinguish: record both total and active parameters when documentation provides them.
- Evaluate: test models on a representative prompt suite, not architecture claims.
- Measure: capture latency, throughput, output quality, and validation failures.
- Prototype: implement a tiny top-k router to understand conditional computation.
- Deploy carefully: verify runtime support, memory needs, batching, and communication overhead.
- Protect data: apply redaction, policy review, access controls, and human oversight.
Mixture-of-Experts models make AI capacity more selective, but the winning approach is still to test the model, runtime, and safeguards against the real work you need done. 🤖⚡🔬