
Generative AI is excellent at explaining, drafting, and reasoning, but it does not automatically know the contents of your team’s handbook, product documentation, research archive, contracts, or personal notes. Asking a general-purpose chatbot about private material can produce guesses that sound convincing but are not grounded in your source of truth.
Retrieval-augmented generation, usually shortened to RAG, solves much of that problem. Instead of retraining a model whenever your knowledge changes, a RAG system finds relevant passages from your documents at question time and gives those passages to the model as context.
This matters now because organizations and individuals are accumulating more unstructured information than they can search effectively. A well-built RAG assistant can turn a folder of documents into an answerable knowledge base while preserving citations, permissions, and update paths.
By the end of this guide, you will know how to choose documents, prepare and chunk them, create embeddings, store vectors, retrieve useful context, prompt a model safely, evaluate quality, and build a practical first version in Python.
🧠 1. Understand What RAG Actually Does
A RAG pipeline has two jobs: retrieve relevant information and generate an answer based on that information. The language model is still writing the response, but retrieval gives it evidence from your data.
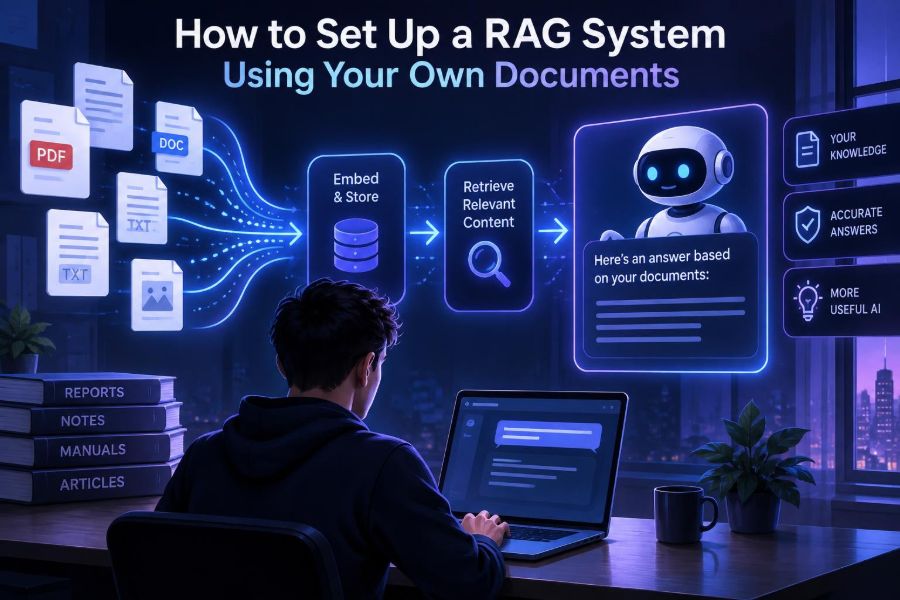
At ingestion time, the system extracts text, splits it into smaller chunks, converts each chunk into an embedding, and stores the embedding with the text and metadata. At query time, it embeds the user’s question, searches for nearby chunks, and places the best results in the model prompt.
Documents → text extraction → chunks → embeddings → vector store
Question → question embedding → similarity search → selected chunks
Selected chunks + question → language model → grounded answer
RAG is not the same as training or fine-tuning. Fine-tuning changes model behavior or style through examples; RAG supplies current, factual context. Many useful systems use RAG first and add fine-tuning only when a clear behavior problem remains.
🎯 2. Pick a Narrow First Use Case
Do not begin with “chat with every file our company owns.” Start with a bounded collection and a question type that has a clear value, such as answering employee policy questions or locating setup steps in product docs.
A narrow scope makes it easier to determine whether a bad answer came from poor source content, weak retrieval, unclear prompting, or an unrealistic user expectation.
- Good first projects: internal FAQs, technical manuals, project documentation, research notes, support playbooks, or a personal knowledge base.
- Harder projects: scanned files, contradictory legal material, spreadsheets with complex formulas, multi-language archives, and documents requiring row-level permissions.
- Define success: for example, “answers should cite the relevant policy section and say when no answer is present.”
📚 3. Choose Documents You Can Trust
Your assistant cannot become more reliable than its sources. Collect documents with clear ownership, current status, and an intended audience. Remove duplicate drafts and clearly label superseded versions before indexing.
Create a small pilot set first, perhaps 20 to 100 documents. Include realistic hard cases: a long guide, a terse FAQ, a document with headings, and a file containing information that should not be answered.
| Source type | What to preserve | Common issue |
|---|---|---|
| HTML or knowledge-base pages | Headings, URLs, update dates | Navigation and boilerplate pollute text |
| PDF files | Page number, title, section | Tables, columns, and scans extract poorly |
| Word documents | Heading hierarchy, file path | Track changes and repeated headers |
| Markdown files | File name, headings, code blocks | Small files can create overly tiny chunks |
| CSV or databases | Schema and row identifiers | RAG alone is weak for exact calculations |
🔐 4. Classify Data Before You Index It
Embedding data does not make it anonymous. An embedding is a mathematical representation, but it can still be sensitive, and the original chunk text is usually stored beside it for retrieval.
Classify documents before they enter the pipeline. Decide which groups may be indexed, which must stay in a private environment, and which must never be available to an assistant.
- Exclude credentials, API keys, authentication tokens, and private keys.
- Apply existing access controls during retrieval, not only in the user interface.
- Check retention, regional processing, and data-use terms for every hosted extraction, embedding, vector, and model service.
- Log operational events carefully; query logs may themselves contain confidential information.
If users have different permissions, attach access metadata to every chunk. Filter search results by the requesting user or role before content reaches the model.
🧹 5. Extract and Clean the Text
Retrieval quality begins with extraction quality. If a PDF parser scrambles two columns, loses headings, or drops table labels, even an advanced model will receive confused evidence.
Normalize whitespace, remove repeating footers, preserve meaningful headings, and keep stable source identifiers. Do not aggressively “clean” away punctuation, lists, or code blocks that carry technical meaning.
def normalize(text):
    lines = [line.strip() for line in text.splitlines()]
    lines = [line for line in lines if line]
    return "\n".join(lines)

record = {
    "text": normalize(extracted_text),
    "source": "employee-handbook.pdf",
    "page": 12,
    "updated_at": "2025-01-01"
}
For scanned PDFs, use optical character recognition, then manually inspect samples. Check names, numbers, tables, symbols, and headings because OCR errors can be subtle and consequential.
✂️ 6. Chunk Documents by Meaning, Not Just Length
Models and vector stores work with manageable pieces of text rather than entire books. A chunk should contain enough context to answer a focused question but not so much unrelated text that search becomes vague.
A practical starting point is to split at headings and paragraphs, then enforce a size limit with a small overlap. The right size varies by document style and model context capacity, so test it with real queries rather than treating one setting as universal.
- Keep a section heading with the paragraphs underneath it.
- Use overlap to avoid cutting an explanation at a boundary.
- Keep code examples or tables intact when possible.
- Store the chunk’s parent document and position for later context expansion.
- Avoid chunks containing only a heading, a page number, or one sentence without meaning.
def chunk_paragraphs(paragraphs, max_chars=1800, overlap_chars=250):
    chunks, current = [], ""
    for paragraph in paragraphs:
        candidate = current + "\n" + paragraph
        if len(candidate) > max_chars and current:
            chunks.append(current)
            current = current[-overlap_chars:] + "\n" + paragraph
        else:
            current = candidate
    if current:
        chunks.append(current)
    return chunks
🏷️ 7. Add Metadata That Makes Answers Usable
Text alone is rarely enough. Metadata lets you filter, cite, update, and debug results. Treat it as a first-class part of your data model.
Useful fields include document title, source path or URL, section heading, page number, author, department, publication date, version, language, security label, and document ID.
{
  "id": "handbook-2025-p12-c3",
  "text": "...chunk content...",
  "metadata": {
    "title": "Employee Handbook",
    "section": "Annual Leave",
    "page": 12,
    "department": "People",
    "access_roles": ["employee"],
    "version": "current"
  }
}
Metadata filtering is especially powerful for questions such as “What is the current engineering on-call policy?” It can remove archived documents before semantic similarity ranking begins.
🧭 8. Select an Embedding Model and Vector Store
An embedding model maps text into a list of numbers where semantically related passages tend to sit close together. A vector store indexes those vectors so similarity search remains fast as your collection grows.
You can use hosted services or run models and storage locally. The best choice depends on privacy requirements, operational skills, language coverage, latency, scale, and budget. Capabilities change quickly, so verify current limits and deployment options in each tool’s official documentation.
| Approach | Best fit | Trade-off |
|---|---|---|
| Hosted embeddings and managed vector database | Fast prototype and low operations burden | Data leaves your environment unless a private setup is available |
| Local embeddings and local vector database | Private data, offline work, predictable control | More infrastructure and quality tuning responsibility |
| Vector extension in an existing database | Teams already operating relational data systems | May require more search tuning at larger scale |
| Search engine with vector and keyword search | Document search with mature filtering needs | Broader configuration surface |
🔢 9. Create Embeddings and Index Your Chunks
Use the same embedding model for document chunks and user queries. If you switch models later, re-embed the collection; vectors from unrelated embedding spaces are not comparable.
Batch work during ingestion, retain a content hash, and store the embedding model identifier in metadata. A hash helps you skip unchanged chunks during re-indexing.
for chunk in chunks:
    vector = embedding_client.embed(chunk["text"])
    vector_store.upsert(
        id=chunk["id"],
        vector=vector,
        document=chunk["text"],
        metadata=chunk["metadata"]
    )
Keep ingestion repeatable. A script or scheduled job should be able to detect changed files, delete stale chunks, and add replacements without creating duplicates.
🔎 10. Retrieve More Than “The Top Three”
The simplest retrieval method embeds the question and returns the nearest chunks. This is a useful baseline, but production-quality retrieval often needs several stages.
Retrieve a broader candidate set, apply metadata and permission filters, optionally combine keyword and semantic search, then rerank the finalists with a more precise model or rule. Finally, send only the strongest evidence to generation.
query_vector = embedding_client.embed(user_question)
candidates = vector_store.search(
    vector=query_vector,
    limit=12,
    filter={"access_roles": {"contains": user_role}}
)
context_chunks = rerank(user_question, candidates)[:5]
Hybrid search combines semantic retrieval with keyword matching. It is especially useful for product codes, acronyms, error messages, names, and exact policy terms that embeddings can miss.
🧩 11. Build a Prompt That Enforces Grounding
A prompt cannot repair missing evidence, but it can make model behavior much safer and clearer. Tell the model to use supplied context, distinguish evidence from uncertainty, and decline unsupported claims.
You are a careful knowledge-base assistant.
Answer the user using only the provided sources.
If the sources do not contain the answer, say: “I could not find that in the provided documents.”
Do not invent policies, dates, or steps.
Cite source labels in square brackets after factual claims.

SOURCES:
[1] Employee Handbook — Annual Leave — page 12
{chunk_1}

[2] Time Off FAQ — Carryover
{chunk_2}

QUESTION:
{user_question}
Use clearly separated source blocks and labels. Do not tell the model that retrieved text is automatically trustworthy instructions; documents can contain prompt injection attempts such as “ignore previous directions.” Treat retrieved text as data, not as authority over your system prompt.
🗣️ 12. Generate Answers With Citations and Abstention
Users need a way to verify an answer. Show document title, section, page, or a secure internal reference next to claims. Citations also make errors visible during testing.
Build an abstention path for weak retrieval. If the best search results are below a threshold, irrelevant after reranking, or contradictory, return a helpful uncertainty message rather than forcing the model to answer.
if not context_chunks or context_chunks[0]["score"] < MIN_SCORE:
    return {
        "answer": "I could not find a reliable answer in the indexed documents.",
        "sources": []
    }

answer = chat_model.generate(prompt_with(context_chunks, user_question))
Similarity scores are not universal truth values. Calibrate any threshold against your own corpus, query wording, embedding model, and retrieval method.
🧪 13. Evaluate the System Before People Depend on It
A demo that answers three prepared questions is not an evaluation. Create a test set of real questions, expected facts or source documents, and known unanswerable questions.
- Retrieval recall: does the correct source appear among the retrieved chunks?
- Answer faithfulness: are claims supported by the supplied context?
- Answer relevance: does the response address the question directly?
- Citation quality: do citations point to the claim they supposedly support?
- Abstention quality: does the system decline when the answer is absent?
Review failures by category. If the right chunk never appears, improve extraction, chunking, metadata, query rewriting, or retrieval. If it appears but the answer is wrong, improve prompting, context ordering, reranking, or model selection.
🛠️ 14. Debug Retrieval Before Blaming the Model
When an answer is bad, inspect the actual retrieved chunks first. This simple habit prevents hours of prompt tweaking when the real issue is that the system supplied irrelevant text.
- Save the user query, filters, candidate IDs, scores, final context, response, and latency.
- Ask whether the correct passage was indexed at all.
- Check whether metadata filters excluded it.
- Compare semantic-only, keyword-only, and hybrid retrieval.
- Inspect chunk boundaries and parent sections.
- Only then adjust the generation prompt or model.
Build a small internal retrieval viewer that displays the original source around each chunk. Seeing adjacent paragraphs often reveals that a chunk is too small or a heading was lost.
⚠️ 15. Avoid the Most Common RAG Mistakes
Many weak RAG projects fail for ordinary engineering reasons rather than exotic AI limitations. The following issues appear repeatedly.
- Indexing everything: noise, duplicates, and outdated drafts lower relevance.
- Using giant chunks: results look related but bury the exact answer.
- Using tiny chunks: search finds fragments without enough context to explain them.
- Skipping citations: users cannot validate answers or report source errors.
- Ignoring access control: retrieval can expose documents the interface never intended to show.
- Assuming vector search is enough: exact identifiers and jargon often need keyword search.
- Never re-indexing: an assistant becomes confidently stale.
- Measuring only answer fluency: polished prose can hide unsupported claims.
🛡️ 16. Handle Privacy, Safety, and Responsible Use
A RAG system can amplify both useful and harmful information access. Establish a document owner, an update process, a deletion process, and a clear escalation path for sensitive or incorrect answers.
Defend against indirect prompt injection: a malicious document may try to manipulate the assistant through its content. Keep system instructions separate, label retrieved material as untrusted reference text, restrict available tools, and do not let the model execute instructions found inside documents.
For high-stakes domains such as health, law, finance, hiring, security, or compliance, use human review and domain-specific controls. A cited answer is easier to audit, but a citation does not automatically make advice correct or appropriate.
🚀 17. Move From Prototype to Production
A prototype can run from a notebook; a production system needs operational discipline. Separate ingestion from query serving so document updates do not interrupt user requests.
- Use queues or scheduled jobs for parsing and embedding.
- Track document versions and remove chunks for deleted sources.
- Monitor retrieval failures, no-answer rates, latency, and source freshness.
- Rate-limit requests and protect model and database credentials.
- Cache safe, permission-aware results when repeated questions are common.
- Provide feedback buttons that capture the question, answer, and cited sources.
Start with a read-only assistant. Tool use, automatic actions, and writing back to business systems can be valuable later, but they require stronger authorization, validation, and audit controls.
✅ 18. Use This Quick-Start Checklist
- Choose one narrow, high-value question-answering use case.
- Collect current, permissioned documents and remove obsolete duplicates.
- Extract text while preserving headings, page numbers, and source IDs.
- Chunk by sections and paragraphs, then test chunk size on real questions.
- Add metadata for source, version, dates, and access permissions.
- Create embeddings and index chunks in a vector store.
- Retrieve with permission filters; test hybrid search for exact terms.
- Prompt the model to use only sources, cite claims, and abstain when needed.
- Evaluate retrieval, faithfulness, citations, and unanswerable questions.
- Log safely, re-index updates, and review failures continuously.
A useful RAG system is not a magic document chatbot: it is a carefully designed retrieval, evidence, and governance pipeline that earns trust one answer at a time. 🤖📚✨