
AI applications can feel inexpensive in a prototype and surprisingly costly at scale. A single chat, document summary, agent workflow, or image-aware request may involve far more model input and output than its interface suggests.
That makes token accounting a product skill, not just an infrastructure task. Teams that can measure usage early can set sensible budgets, choose appropriate models, price their own products, and avoid unpleasant bills after a feature goes viral.
You do not need to be a machine-learning researcher to do this well. You need a clear model of what tokens are, an inventory of every request your application makes, and a few practical assumptions about user behavior.
By the end of this guide, you will be able to estimate token use per workflow, convert it into a monthly cost range, instrument an application for real measurements, and reduce spending without making the experience worse.
🧩 1. Start With the Core Idea: Tokens Are Billable Units
A token is a small piece of text processed by an AI model. It is not reliably the same thing as a word or a character: common words can be one token, while code, uncommon names, punctuation, and non-English text can split into several.
Models generally charge separately for input tokens sent to the model and output tokens generated by it. Some providers also distinguish cached input, stored state, tool use, audio, images, or other modalities.
Think of the basic calculation this way:
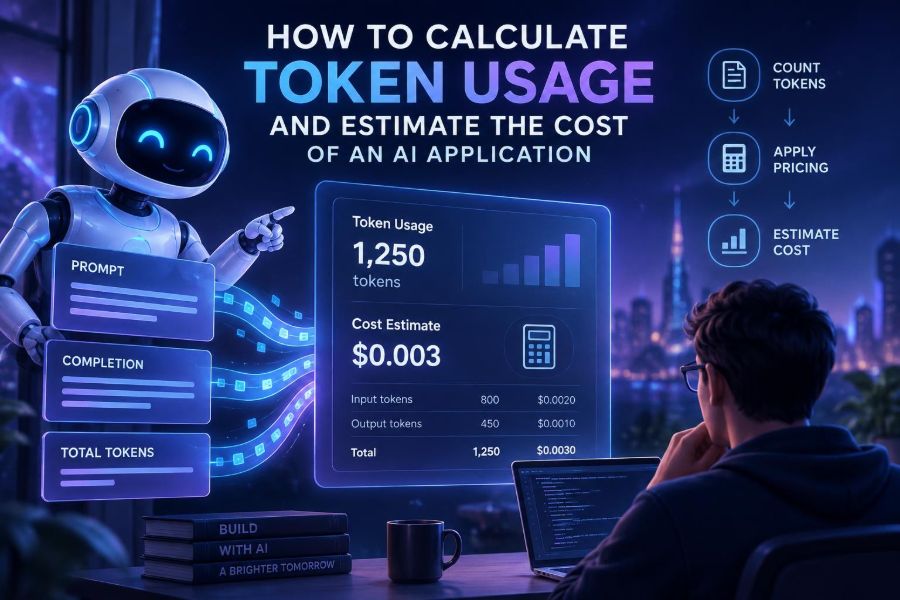
request cost = (input tokens × input rate) + (output tokens × output rate)Rates are commonly quoted per million tokens, but pricing structures change. Always take current rates, model limits, and any special billing rules from the provider’s official pricing documentation.
🔤 2. Understand Why Word Counts Are Only Rough Estimates
A useful English-language rule of thumb is that one token often represents roughly three to four characters of ordinary prose. Another rough shortcut is that 100 English words may be around 120 to 160 tokens, but neither is reliable enough for production budgeting.
Formatting and content type matter. A compact paragraph, a JSON object, a source-code file, and a multilingual support ticket can produce very different token counts even when they look similar in length.
| Content type | Why token use can vary | Budgeting advice |
|---|---|---|
| Plain English prose | Frequent words tokenize efficiently | Use a rough ratio for early planning |
| Source code | Symbols, identifiers, indentation, and strings add fragments | Measure representative files |
| JSON and tool schemas | Keys, punctuation, descriptions, and nested structure repeat | Count the entire serialized payload |
| Multilingual text | Languages and scripts tokenize differently | Sample each major user language |
| Retrieved documents | Chunk size and number of results drive context size | Measure tokens after retrieval and formatting |
Practical rule: use heuristics for a business-case spreadsheet, then replace them with token counts from the exact model family and payload format you intend to ship.
🧮 3. Separate Input, Output, and Hidden Overhead
The visible user prompt is rarely the entire input. Most applications also send instructions, chat history, retrieved context, tool definitions, examples, metadata, and structured output requirements.
Create a request inventory before estimating anything. For each model call, identify the components that add tokens.
- System instructions: behavior, style, safety, and workflow rules.
- User content: the current message, document, image description, or form data.
- Conversation history: prior messages retained for context.
- Retrieved context: passages pulled from a knowledge base.
- Tool definitions: schemas and descriptions the model can call.
- Output format: JSON schema, examples, or constraints.
- Generated response: the model’s answer and any tool-call arguments.
A common mistake is estimating from the user’s 30-word question while overlooking 2,000 tokens of instructions, history, and documentation sent with every turn.
🗺️ 4. Draw the Full AI Workflow Before Doing the Math
One user action can trigger multiple model calls. A support assistant might classify an issue, retrieve help articles, draft an answer, check policy compliance, and summarize the interaction for a CRM.
Map each step as a separate row. Do not assume “one chat message equals one request.” Agent-like systems may loop through tools and generate several intermediate responses.
User asks a question
  → intent classification
  → retrieval query generation
  → answer generation with retrieved passages
  → optional quality or safety review
  → conversation summary saved for later
For every row, record the expected calls per user action. If a tool loop happens only sometimes, assign it a probability rather than pretending it never occurs.
📏 5. Measure Representative Prompts With the Right Tokenizer
The most accurate estimate comes from tokenizing the exact text that will be sent, using the tokenizer compatible with the deployed model. Tokenizers can differ across model families, so an unrelated calculator can produce misleading results.
Build a small representative dataset instead of testing one tidy demo prompt. Include short, typical, and long conversations; varied documents; realistic tool schemas; and each important language your users write in.
- Capture sanitized examples of real or realistic requests.
- Construct the final message payload exactly as your application sends it.
- Count input tokens with the appropriate tokenizer or provider usage data.
- Record output tokens from completed responses.
- Calculate median, upper-percentile, and maximum observed values.
The median describes ordinary usage. A high percentile helps prepare for expensive but legitimate requests. The maximum is useful for enforcing limits, but should not be treated as the average.
🧰 6. Build a Simple Token Budget Worksheet
Your first worksheet can be a spreadsheet. Its purpose is transparency: anyone on the product, finance, or engineering team should be able to see which assumption causes the cost.
| Workflow step | Calls per action | Input tokens per call | Output tokens per call | Input rate | Output rate | Cost per action |
|---|---|---|---|---|---|---|
| Classify request | 1 | 300 | 30 | Current provider rate | Current provider rate | Calculate |
| Generate answer | 1 | 2,200 | 450 | Current provider rate | Current provider rate | Calculate |
| Optional review | 0.15 | 900 | 120 | Current provider rate | Current provider rate | Calculate |
For each row, multiply calls by tokens and by the applicable rate. Then sum the rows. Keep input and output separate because output is often priced differently and is usually more controllable with output limits.
monthly cost = monthly actions × cost per action

monthly actions = active users × actions per user per month
💵 7. Convert Token Volumes Into Cost Without Guesswork
Use rates in the same unit as your formula. If a provider lists a rate per one million tokens, divide your token total by 1,000,000 before multiplying.
input cost = (monthly input tokens / 1,000,000) × input price per million
output cost = (monthly output tokens / 1,000,000) × output price per million
total model cost = input cost + output cost + other applicable charges
Suppose an answer workflow uses 2,500 input tokens and 500 output tokens per action. At 10,000 actions a month, that is 25 million input tokens and 5 million output tokens before any other calls. Insert the current prices for the chosen model into your worksheet rather than relying on a stale example from an article.
This separation reveals where optimization matters. Cutting 20% of a large retrieved context may have more impact than reducing a short answer by one sentence.
📈 8. Estimate Low, Typical, and High Scenarios
A single average creates false confidence. Product usage is uneven: some people ask one question, while power users upload long documents and iterate repeatedly.
Create at least three scenarios with explicit assumptions.
- Low: conservative adoption, short context, few optional steps.
- Typical: expected active users and median token consumption.
- High: strong adoption, long inputs, high-percentile output, and more tool loops.
typical monthly tokens =
  active users × actions per user × tokens per action

high monthly tokens =
  high active users × high actions per user × high-percentile tokens per action
Include a contingency for retries, failed structured-output parsing, regeneration buttons, and internal testing. These are real calls, and they can be significant before a launch.
💬 9. Calculate the Cost of a Multi-Turn Conversation
Chat applications can grow expensive because the application may resend old messages on every new turn. If each turn includes all history, input tokens can rise roughly with the accumulated conversation length.
Model a five-turn conversation rather than multiplying one turn by five. The fifth request may include the first four exchanges plus new retrieved content and instructions.
Turn 1 input = instructions + user message
Turn 2 input = instructions + turn 1 + user message
Turn 3 input = instructions + turns 1-2 + user message
...
Conversation cost = sum of every turn's input and output cost
Use a context policy: retain the most useful recent messages, summarize older material, and selectively preserve facts that must remain accurate. Do not blindly truncate information that changes safety, permissions, or task requirements.
📚 10. Account for Retrieval-Augmented Generation
Retrieval-augmented generation, often called RAG, lets an application retrieve relevant passages from a knowledge base and include them in the model prompt. It can improve grounding, but each passage consumes input tokens.
Estimate RAG as a pipeline, not merely an answer call. There may be embedding generation for documents and queries, vector storage or search costs, reranking, and answer-generation tokens.
- How many chunks are retrieved per query?
- How many tokens does each formatted chunk contain?
- Do you include titles, metadata, citations, or neighboring chunks?
- Is a reranker or second model called?
- How often are source documents indexed or updated?
More context is not automatically better. Retrieve fewer, more relevant passages; trim boilerplate; and set a context budget. This improves both cost and the chance that the model focuses on useful evidence.
🔁 11. Price Agents and Tool-Using Systems by Expected Loops
An agent can decide to call tools, inspect results, and continue reasoning. The resulting cost is variable because each iteration adds a model request, tool payload, and often a longer history.
Estimate with probabilities and caps. For example, define the percentage of tasks that finish without a tool, use one tool, use several tools, or reach a handoff path.
expected calls per task =
  (0.50 × 1) + (0.35 × 2) + (0.12 × 4) + (0.03 × 6)
Add explicit limits in production: maximum steps, maximum tool calls, maximum cumulative tokens, timeouts, and a clear fallback. An uncapped loop is both a reliability risk and a cost risk.
🧑💻 12. Add Instrumentation to Capture Actual Usage
Estimates are planning tools. Production telemetry is the source of truth. Most model APIs return usage metadata or make it available through dashboards, but implementation details vary by provider and feature.
Log enough information to explain cost without logging sensitive content unnecessarily. Associate usage with a request ID, feature, model, tenant or account category, and outcome.
function recordModelUsage(event) {
  metrics.increment('ai.requests', 1, { feature: event.feature });
  metrics.observe('ai.input_tokens', event.inputTokens, { model: event.model });
  metrics.observe('ai.output_tokens', event.outputTokens, { model: event.model });
  metrics.observe('ai.estimated_cost', event.estimatedCost, { feature: event.feature });
}
Track latency and errors alongside tokens. A cheap workflow that frequently fails and retries may cost more than its per-request calculation suggests.
🏷️ 13. Attribute Cost to Features, Customers, and Experiments
Total spend is less useful than unit economics. You need to know which feature, workflow, customer tier, and experiment generated the usage.
Tag every call at the application layer. Provider dashboards may show aggregate usage, while your own tags connect it to a product decision.
- Feature: writing assistant, search answer, document extraction.
- Workflow: draft, regenerate, review, export.
- Customer segment: free, paid, enterprise, internal.
- Experiment: prompt variant, retrieval setting, model route.
- Outcome: accepted answer, retry, escalation, error.
This lets you calculate cost per successful task, not merely cost per API call. A more capable model can be economically sensible if it eliminates retries, manual review, or abandoned tasks.
⚖️ 14. Choose the Right Model for Each Step
Using one premium model for every operation is simple, but rarely optimal. Many workflows contain easy classification, extraction, routing, or formatting steps that may work well with a smaller or lower-cost model.
| Task pattern | Often suitable approach | What to validate |
|---|---|---|
| Intent routing | Small model or deterministic rules | Misrouting rate and edge cases |
| Structured extraction | Model with schema support and validation | Field accuracy and repair retries |
| High-stakes analysis | Capable model plus review controls | Accuracy, citations, escalation rate |
| Long-document synthesis | Long-context model or staged summarization | Completeness and total context cost |
| Routine rewriting | Lower-cost model with output cap | Style quality and user acceptance |
Route by task difficulty, document length, customer tier, or confidence score. Evaluate quality with representative tests before switching; a lower token price does not guarantee a lower cost per useful result.
✂️ 15. Reduce Input Tokens Without Removing Essential Context
Input reduction is usually the safest first optimization because applications often carry redundant instructions and irrelevant history. Start by inspecting actual serialized requests, not the prompt text in an editor.
- Remove duplicated rules across system messages and examples.
- Replace lengthy prose instructions with clear, compact directives.
- Send only fields the model needs from large records.
- Retrieve fewer passages and trim repeated headers or navigation text.
- Summarize older chat turns into verified task-relevant facts.
- Use caching features where supported and appropriate.
Do not remove context blindly. In a support workflow, account permissions, product version, and prior troubleshooting can be essential even if they look repetitive.
Before:
You are a helpful assistant. Please be helpful, accurate, concise...

After:
Answer using only the supplied support notes. If evidence is missing, say so.
Return: diagnosis, steps, escalation_needed.
🛑 16. Control Output Tokens and Regeneration
Output is easy to overlook because it arrives after the request, but verbose generations can be costly and slow. Give the model a clear output shape and a reasonable maximum output limit.
Summarize the issue for a support agent.
Use exactly these sections:
1. Problem
2. Evidence
3. Next action
Keep the total under 120 words.
Output caps are guardrails, not quality guarantees. A cap that is too low can cut off JSON, explanations, or safe completion behavior, causing retries that erase the savings.
Also measure regenerate behavior. If users frequently ask for another answer, improve the first response with better grounding, a useful format, or a clearer choice of model rather than only making responses shorter.
🔒 17. Build Privacy, Security, and Responsible-Use Controls In
Token logging can accidentally become content logging. Prompts may contain personal data, proprietary code, health information, financial details, or customer records. Minimize what you store and protect what remains.
- Prefer aggregate token metrics over raw prompt retention.
- Redact or hash identifiers when possible.
- Set short retention periods appropriate to your obligations.
- Restrict access to usage logs and audit that access.
- Review provider data-handling terms and regional requirements.
- Put stricter approval and human-review paths around high-impact decisions.
Cost controls should not create harmful shortcuts. For example, reducing context may remove critical safety information, and routing sensitive cases to a weaker system may increase error risk. Evaluate cost, quality, privacy, and user impact together.
🚨 18. Set Budgets, Alerts, and Hard Guardrails
A budget is useful only when it triggers a response. Set alerts for daily and monthly spend, unusually large requests, rapid growth by tenant, high retry rates, and unexpected model routing.
Use multiple levels of control:
- Soft alert: notify an owner when spend or token volume deviates from plan.
- Feature limit: cap uploads, regenerations, document size, or requests per user.
- Workflow limit: stop tool loops and enforce maximum cumulative tokens.
- Account limit: pause or throttle unusually high consumption.
- Emergency switch: disable a costly optional feature or route to a safer fallback.
Review anomalies promptly. A sudden increase can come from a prompt deployment, a retrieval bug, malicious usage, a changed user pattern, or an integration that began retrying.
🧪 19. Test Cost Changes Like Product Changes
Every prompt edit, model change, retrieval adjustment, or schema expansion can change usage. Treat token impact as a release metric, not a finance report reviewed at the end of the month.
Create a test set that includes ordinary and difficult cases, then compare both quality and cost before deployment.
Release checklist metrics:
- task success rate
- input tokens per successful task
- output tokens per successful task
- retries and parse failures
- latency
- safety or policy failures
- estimated cost per successful task
Watch for “optimizations” that move cost elsewhere. A smaller initial context may increase follow-up questions; a cheaper extraction model may generate malformed data that requires a second pass.
✅ 20. Use This Quick-Start Checklist
- List every model call in one user workflow.
- Separate input, output, tool, retrieval, and non-model costs.
- Measure representative payloads with a compatible tokenizer or API usage data.
- Calculate low, typical, and high monthly scenarios.
- Include retries, regenerations, tests, and agent loops.
- Instrument production calls with feature and outcome tags.
- Set limits for context, output, tool steps, and customer usage.
- Compare models by cost per successful task, not token price alone.
- Review privacy practices before retaining prompts or logs.
- Revisit assumptions after launches, prompt changes, and usage growth.
The durable way to manage AI costs is to measure real workflows, make assumptions visible, and optimize for useful outcomes rather than the lowest possible token count. With a small worksheet, good telemetry, and sensible guardrails, token economics becomes a design constraint you can actively control. 🤖📊✨