
AI systems can draft emails, explain code, summarize reports, and answer questions in seconds. But they can also state a false claim with perfect confidence, invent a source, or combine two real facts into a misleading answer. That behavior is commonly called a hallucination.
This matters more now because AI is moving from casual experimentation into customer support, research, software development, operations, healthcare-adjacent workflows, and creative production. A wrong answer is not always harmless; it can waste time, damage trust, expose sensitive information, or lead to an expensive decision.
The useful news is that hallucinations are not a single unsolved bug. They are a predictable failure mode that teams can reduce with better task design, trusted data, retrieval systems, tool use, verification, and human review.
After reading, you will be able to identify the kinds of hallucinations your AI workflow risks, build a practical grounded-answer process, write prompts that demand evidence, and add lightweight verification to an AI application.
🧠 1. Understand What a Hallucination Really Is
A hallucination is an output that sounds plausible but is unsupported, incorrect, or fabricated. The model may invent a detail, misread supplied information, cite a source that does not exist, or answer a question when the evidence is insufficient.
Language models predict useful next words from patterns in data. They do not naturally maintain a guaranteed, up-to-date database of truth. Fluency is therefore not evidence.
- Factual hallucination: “This regulation took effect in 2022” when it did not.
- Source hallucination: a made-up paper title, URL, policy clause, or quotation.
- Reasoning hallucination: a conclusion that does not follow from the provided facts.
- Instruction hallucination: claiming a task was completed when a required tool or step was skipped.
The practical goal is not “make the model never be wrong.” It is to make it answer from evidence, disclose uncertainty, and safely abstain when evidence is missing.
🎯 2. Match the Risk Controls to the Task
Not every AI task needs the same safeguards. Brainstorming product names can tolerate imaginative output. Explaining a benefits policy, approving a payment, or answering a medical question needs a much stricter process.
| Task type | Typical risk | Useful control |
|---|---|---|
| Creative ideation | Low factual risk | Clearly label ideas as suggestions |
| Document Q&A | Missing or distorted facts | Retrieval plus citations to passages |
| Customer support | Incorrect policy or promise | Approved knowledge base and escalation |
| Code generation | Invalid APIs or insecure logic | Tests, linters, docs retrieval, review |
| High-impact decisions | Harm to people or compliance failures | Human approval and deterministic rules |
Start by asking: What happens if this answer is wrong? The higher the consequence, the more your system should prefer verified evidence, constrained actions, and a human decision maker.
🧱 3. Ground the Model in Reliable Context
Grounding means supplying the facts, rules, records, or tool results that an AI should use for its answer. Rather than asking a general model to recall your company’s return policy, give it the current approved policy.
Grounding can come from a pasted document, a structured database query, an API response, a spreadsheet, a live search result, or a retrieval pipeline. The key is that the context is relevant, authoritative, and visible to the model at answer time.
A grounded system should treat supplied evidence as its primary source, not as optional background. It should also distinguish between “the documents say” and “I infer.”
📚 4. Build a Strong Source of Truth
Retrieval cannot rescue poor source material. Before selecting an AI tool, decide which documents and systems deserve to be treated as authoritative.
- List the questions users will ask.
- Map each question to an owner, such as legal, support, engineering, or finance.
- Collect approved source documents and remove obsolete duplicates.
- Add metadata: owner, date, product, region, permissions, and review status.
- Define a refresh process for changing information.
Use concise documents with clear headings and explicit statements. A vague policy such as “returns are usually accepted” is difficult for both people and models. “Returns are accepted within 30 days for unopened items, subject to the exceptions below” is much safer.
Do not quietly mix drafts, old policies, user comments, and official rules in one knowledge collection. If content has different authority levels, label them and filter accordingly.
🔎 5. Learn the Retrieval-Augmented Generation Pattern
Retrieval-augmented generation, often shortened to RAG, gives a model relevant external context before it generates an answer. It is a common architecture for knowledge assistants.
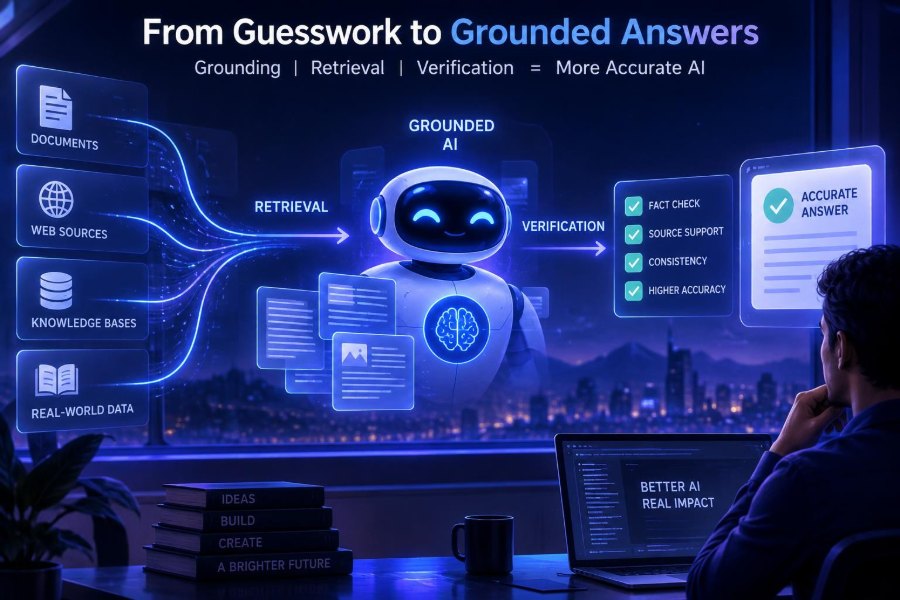
The basic flow is simple: a user asks a question, the system finds relevant passages, the model receives those passages with instructions, and the answer includes evidence or says that the evidence is insufficient.
User question → retrieve relevant passages → rank/filter passages → model writes grounded answer → verify/display evidenceRetrieval helps with freshness because you can update documents without retraining a model. It also improves auditability: you can inspect what evidence was provided for a particular response.
However, RAG is not magic. If retrieval returns the wrong passage, misses the best passage, or includes conflicting documents, the generated answer can still fail.
✂️ 6. Chunk Documents for Retrieval, Not for Reading
Long documents usually need to be split into smaller pieces, often called chunks, before semantic retrieval. The best chunk is large enough to preserve meaning and small enough to be specific.
Start with natural structure: sections, headings, list items, and tables. Keep a heading with its content so retrieved text has context. A paragraph saying “this does not apply” is useless if its preceding rule is absent.
- Keep policy exceptions with the policy they modify.
- Store document title, section heading, and last-reviewed date as metadata.
- Use a small overlap only when splitting continuous prose.
- Test retrieval with real questions, including ambiguous phrasing.
A common mistake is slicing every document into fixed-size fragments without respecting headings. That can separate definitions from rules, conditions from exceptions, and a claim from its scope.
🧭 7. Retrieve Broadly, Then Rank Carefully
Similarity search finds passages that are semantically close to a question, but similarity alone is not enough. A question about “cancellation” may retrieve account cancellation, order cancellation, and subscription cancellation.
Use metadata filters first when possible. Filter by product, customer region, document status, access permissions, or date. Then retrieve candidates and rank the most relevant passages more carefully.
question = user_question
filters = {"status": "approved", "product": selected_product}
candidates = search_knowledge_base(question, filters=filters)
passages = rerank(question, candidates)[:5]
answer = generate_grounded_answer(question, passages)
The code is illustrative: actual library and API choices vary. Check the official documentation for your chosen model, vector database, search service, and security configuration.
Measure retrieval separately from answer quality. If the correct passage is not in the retrieved set, prompting cannot reliably fix the result.
🗣️ 8. Give the Model a Clear Evidence Contract
Prompts should tell the model exactly how to use context and what to do when context does not answer the question. Vague instructions such as “be accurate” are weaker than an explicit evidence contract.
You are a support assistant. Answer using only the supplied sources.

Rules:
1. Do not use facts not supported by the sources.
2. If the sources do not answer the question, say: "I don't have enough approved information to answer that."
3. State any important condition or exception from the sources.
4. After each factual claim, identify the source title and section.
5. Do not invent links, policies, dates, or contact details.

Question: {question}
Sources: {retrieved_passages}
For a customer-facing assistant, use language that feels natural but remains specific. For an internal analyst tool, request a structured output with claim, evidence, confidence, and unresolved questions.
🧾 9. Make Citations Useful, Not Decorative
Citations improve trust only when they point to the evidence actually supporting a claim. A footnote at the end of a long paragraph can hide the fact that only one sentence was supported.
Attach source labels close to key claims, especially dates, eligibility rules, prices, legal language, and technical specifications. Your interface can show a source title, section, excerpt, and a way to open the original document where permissions allow.
- Use citations to support claims, not merely to decorate a response.
- Show multiple sources when the answer combines information.
- Flag conflicting sources rather than silently choosing one.
- Never allow the model to generate a citation identifier it was not given.
During evaluation, sample answers and check every cited claim. A response with citations can still be misleading if the citation is irrelevant or only partially supports the statement.
🛠️ 10. Use Tools for Facts That Change
Some information should come from a live system instead of a document collection: inventory, account status, order tracking, current exchange rates, calendar availability, or a project’s issue tracker.
In these cases, let the model request a tightly defined tool, then generate a response from the tool result. The model should not simulate the tool call or guess the result.
Available tool: get_order_status(order_id)

When a user asks about an order:
- Ask for the order ID if it is missing.
- Call get_order_status.
- Report only fields returned by the tool.
- If the tool fails, explain that status could not be retrieved.
- Never estimate delivery dates.
Validate tool inputs, enforce user authorization outside the model, and restrict which actions can be taken. For consequential actions, such as refunds or account changes, require confirmation and apply deterministic business rules.
✅ 11. Add Verification After Generation
Grounding reduces errors before an answer is written. Verification checks the answer afterward. The strongest workflows often use both.
Verification can be deterministic, model-assisted, or human-led. Deterministic checks are preferable when possible: validate a date, recompute a total, confirm a product ID exists, or test generated code.
draft = generate_grounded_answer(question, passages)
claims = extract_claims(draft)
unsupported = [claim for claim in claims if not supported_by(claim, passages)]

if unsupported:
    return "I can't verify that from the available sources."
return draft
A second model can compare claims against evidence, but it is not an infallible judge. Treat model-based checking as an additional signal, not proof. For sensitive decisions, route failed or uncertain checks to a qualified person.
🧮 12. Prefer Structured Outputs for Important Workflows
Free-form prose is pleasant to read but difficult to validate automatically. When an AI feeds another system, ask for a defined structure.
{
  "answer": "...",
  "claims": [
    {"text": "...", "source_ids": ["policy-returns-3"], "confidence": "high"}
  ],
  "missing_information": [],
  "needs_human_review": false
}
Your application can validate required fields, ensure source IDs belong to retrieved passages, reject unexpected values, and display uncertainty consistently. Use schema validation rather than hoping a prompt will always produce valid data.
Keep confidence modest. A model’s stated confidence is not a calibrated probability. It is most useful as a routing signal combined with retrieval quality, validation results, and task risk.
🧪 13. Test with an Evaluation Set, Not Just Demos
A system that performs well on three hand-picked questions may fail on normal user language. Build a small, representative evaluation set before scaling up.
Include straightforward questions, paraphrases, multi-step questions, outdated-information traps, ambiguous requests, conflicting-source cases, and questions that cannot be answered from your data.
- Groundedness: are claims supported by provided evidence?
- Answer correctness: does the answer match the approved answer?
- Retrieval recall: was the needed passage retrieved?
- Abstention quality: does the system decline unsupported requests?
- Safety: does it avoid disallowed disclosure or harmful guidance?
Keep a record of failures and add them to the test set. This creates a feedback loop where real mistakes become future regression tests.
🚫 14. Teach the System to Say “I Don’t Know”
Abstention is a feature, not an embarrassment. A reliable assistant should decline to answer when it lacks evidence, retrieval quality is low, sources conflict, or the request requires a professional judgment outside its role.
Give users a helpful next step instead of a blunt refusal. It might request a document, suggest a narrower question, name the responsible team, or offer to create a support ticket through an approved process.
I could not find an approved source that confirms this exception.
Please check the current contract or contact the account team.
I can summarize the relevant policy sections I did find.
A common mistake is forcing every interaction to end in a confident answer. That pressure encourages exactly the behavior grounding is meant to prevent.
⚖️ 15. Resolve Conflicts and Ambiguity Explicitly
Real knowledge bases contain contradictions. One document may be newer, another may apply only in a specific country, and a third may be a draft. The model cannot reliably infer governance rules you never defined.
Create a source hierarchy. For example, a current signed policy may outrank an internal FAQ, which outranks an old presentation. Use metadata and filtering to enforce the hierarchy before generation.
When ambiguity remains, state it plainly: “The available documents differ on this condition. The newer policy says X, while the regional guide says Y. Please confirm with the policy owner.” This is more trustworthy than silently selecting the answer that sounds best.
🔐 16. Protect Privacy and Permission Boundaries
Grounding often means connecting private documents and operational tools to an AI system. That can improve accuracy while creating new security responsibilities.
- Apply access controls before retrieval, not after the answer is generated.
- Retrieve only documents the current user is allowed to view.
- Minimize sensitive information sent to models and logs.
- Define retention, deletion, and audit requirements with your organization.
- Redact secrets, personal data, and credentials from test datasets.
Do not assume a model will keep a secret because a prompt says “confidential.” Security must be enforced by the surrounding application, identity system, data store, and tool permissions.
For legal, medical, financial, employment, and similarly sensitive domains, involve domain experts and establish clear review and escalation paths. AI can assist research and drafting, but it should not impersonate a licensed professional or make unreviewed high-impact decisions.
🧑💻 17. Ground Code Assistants Too
Code models can hallucinate functions, package options, command flags, and framework behavior. The same pattern applies: ground the assistant in the actual repository, relevant documentation, project conventions, and test results.
Give the model narrow tasks and acceptance criteria. Then run real checks. A syntactically convincing patch is not necessarily correct, secure, or compatible with your stack.
Task: Add input validation to the existing createUser handler.

Use only the repository files and approved API documentation provided.
Do not introduce new dependencies.
Return: changed files, explanation, and tests.
Acceptance criteria:
- Invalid email returns the existing validation error format.
- Password is never logged.
- Existing tests remain unchanged unless behavior requires a new test.
Run unit tests, type checks, linters, security scanners, and code review. Treat the model as a fast collaborator, not as the final authority on your runtime environment.
📈 18. Monitor the System After Launch
Accuracy is not a one-time project. Documents change, user language evolves, integrations fail, and retrieval behavior can shift as the knowledge base grows.
Log enough information to investigate failures without collecting unnecessary sensitive content. Useful fields include question category, retrieved source IDs, answer outcome, verification result, escalation rate, user feedback, and latency.
Watch for patterns: repeated “I don’t know” responses can indicate missing content; rising complaint rates can indicate a stale policy; frequent irrelevant citations can reveal retrieval problems. Review sampled conversations regularly with the source owners.
🚀 19. Follow a Practical Quick-Start Checklist
- Choose one narrow, high-value question category.
- Define the consequence of a wrong answer and the required human review level.
- Collect current, approved source material and assign owners.
- Chunk content by meaningful sections and add metadata.
- Retrieve with permission and scope filters.
- Prompt the model to use only supplied evidence and abstain when needed.
- Display claim-level sources where practical.
- Validate structured outputs and use deterministic checks for rules and calculations.
- Test with answerable, unanswerable, ambiguous, and adversarial questions.
- Log failures, improve sources and retrieval, then repeat.
The solution to AI hallucinations is not one prompt or one model: it is a system that connects answers to evidence, checks important claims, and knows when to stop. Build for trustworthy uncertainty, not artificial certainty. 🤖🔍✅