
AI systems increasingly make decisions that affect what people see, buy, flag, approve, or investigate. A spam filter, fraud detector, medical-image classifier, moderation model, and retrieval system can all look impressive in a demo while failing in the cases that matter most.
That is why evaluation metrics deserve more attention than a single “correctness” percentage. Accuracy, precision, recall, and F1 score each tell a different story about a model’s predictions—and choosing the wrong one can produce a costly false sense of confidence.
The good news is that the core calculations are approachable. They start with a small table called a confusion matrix, then build into practical decisions about thresholds, imbalanced data, multiple classes, and monitoring models in production.
After reading, you will be able to turn prediction results into the right metrics, calculate them by hand or in Python, explain the trade-offs to stakeholders, and select evaluation measures that fit your real-world AI use case.
🧭 1. Start With the Question Your Model Must Answer
These metrics are most intuitive for a binary classification problem: the model chooses between two outcomes, often called positive and negative. Examples include “fraud” versus “not fraud,” “spam” versus “not spam,” or “disease detected” versus “not detected.”
Before calculating anything, define what the positive class means. This is not merely a technical label; it determines which mistakes receive special attention.
- For fraud detection, positive might mean a transaction is fraudulent.
- For safety moderation, positive might mean content violates policy.
- For a hiring-screening tool, positive might mean a candidate meets a stated criterion.
- For manufacturing, positive might mean an item is defective.
Write the decision in a plain-language sentence: “This model identifies whether an incoming support message needs urgent escalation.” That sentence makes later metric choices much clearer.
🧩 2. Build a Confusion Matrix From Predictions
A confusion matrix counts how predictions compare with known, correct labels. “Known” usually means human-reviewed ground truth, a trusted historical outcome, or a carefully designed test dataset.
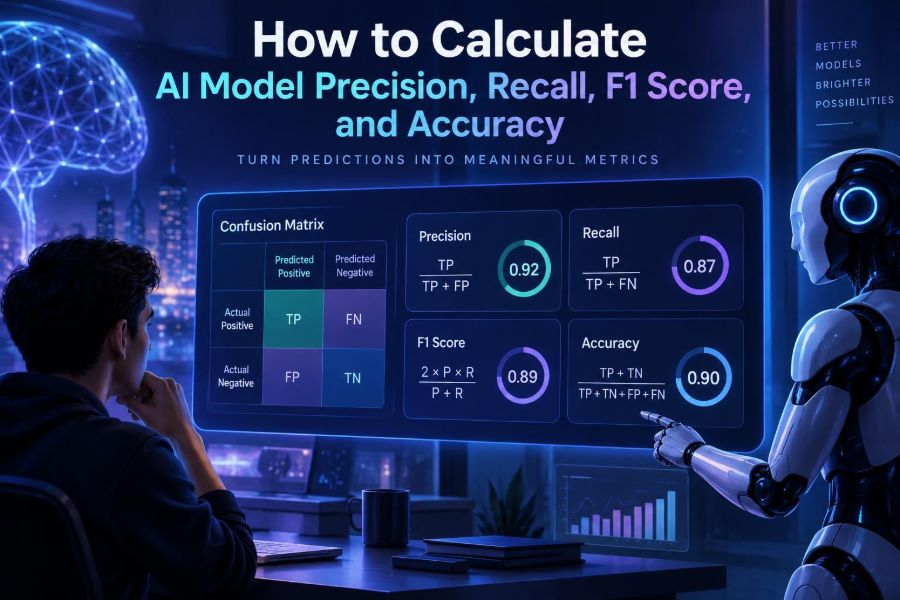
| Actual result | Predicted positive | Predicted negative |
|---|---|---|
| Actually positive | True positive (TP) | False negative (FN) |
| Actually negative | False positive (FP) | True negative (TN) |
The names are literal. A true positive is a positive prediction that is correct. A false positive is a positive prediction that turns out to be wrong.
Imagine 100 tested transactions. After comparing model output with confirmed outcomes, you count 18 true positives, 7 false positives, 5 false negatives, and 70 true negatives. Those four numbers are enough to calculate the main classification metrics.
🔢 3. Learn the Four Counts Before Memorizing Formulas
It helps to translate each count into a real event. In the fraud example, the positive class is “fraud.”
- TP = 18: 18 fraudulent transactions were correctly flagged.
- FP = 7: 7 legitimate transactions were incorrectly flagged.
- FN = 5: 5 fraudulent transactions were missed.
- TN = 70: 70 legitimate transactions were correctly allowed.
The total number of evaluated examples is TP + FP + FN + TN. Here it is 18 + 7 + 5 + 70 = 100.
A common mistake is calling a false positive “the model was false.” Instead, read it as “the model predicted positive falsely.” That wording prevents confusion when you later explain results to a team.
🎯 4. Calculate Precision: Can You Trust Positive Flags?
Precision answers: when the model says positive, how often is it right? It focuses on the quality of positive predictions.
precision = TP / (TP + FP)Using the fraud counts:
precision = 18 / (18 + 7)
precision = 18 / 25
precision = 0.72, or 72%
The model flagged 25 transactions as fraudulent, and 18 truly were. A 72% precision score means that roughly 28% of its fraud alerts were false alarms in this evaluation set.
Prioritize precision when a false positive is expensive or disruptive. For example, an account lockout system should avoid blocking legitimate customers, and a legal-document search tool should avoid flooding reviewers with irrelevant results.
🔍 5. Calculate Recall: How Many Positives Did It Find?
Recall, also called sensitivity or true positive rate, answers: of all the real positive cases, how many did the model find? It focuses on missed positives.
recall = TP / (TP + FN)With the same fraud counts:
recall = 18 / (18 + 5)
recall = 18 / 23
recall = 0.783, or 78.3%
There were 23 truly fraudulent transactions. The model caught 18 and missed 5, so its recall is about 78.3%.
Prioritize recall when missing a positive case causes serious harm. Examples include early disease screening, security threat detection, urgent customer escalation, and finding dangerous defects. High recall is often paired with human review because catching more cases can also create more false positives.
⚖️ 6. Calculate F1 Score: Balance Precision and Recall
F1 score combines precision and recall into one number. It uses the harmonic mean, which penalizes a system that performs very well on one metric but poorly on the other.
F1 = 2 × (precision × recall) / (precision + recall)You can also calculate it directly from confusion-matrix counts:
F1 = 2 × TP / (2 × TP + FP + FN)For the running example:
F1 = 2 × 18 / (2 × 18 + 7 + 5)
F1 = 36 / 48
F1 = 0.75, or 75%
F1 is useful when both false alarms and missed positives matter, and you need a concise comparison across models. It does not include true negatives, which is often a feature rather than a flaw when the negative class is extremely common.
✅ 7. Calculate Accuracy: Useful, but Easy to Misread
Accuracy is the proportion of all predictions the model got right, regardless of class.
accuracy = (TP + TN) / (TP + FP + FN + TN)For the 100 transactions:
accuracy = (18 + 70) / 100
accuracy = 0.88, or 88%
An 88% accuracy score sounds strong. But it conceals that the model missed 5 of 23 fraud cases and generated 7 false alerts. Whether that is acceptable depends on the business, safety, and customer consequences.
Use accuracy when classes are reasonably balanced and the cost of each error is similar. Do not use it alone when positive cases are rare or when one error type matters far more than another.
🚨 8. See Why Imbalanced Data Can Fool Accuracy
Many real datasets are imbalanced. A bank may see far more legitimate transactions than fraudulent ones, while a hospital may see far more normal scans than scans containing a rare condition.
Suppose only 1 of every 100 transactions is fraudulent. A useless model that predicts “not fraud” for every transaction gets 99% accuracy. Yet it catches zero fraud cases.
TP = 0   FP = 0
FN = 1   TN = 99

accuracy = 99 / 100 = 99%
recall = 0 / (0 + 1) = 0%
This is why an accuracy headline without a class breakdown should raise questions. Always inspect the confusion matrix and report precision and recall for the class that matters.
🧮 9. Calculate Metrics by Hand in a Repeatable Workflow
For a small test set, a spreadsheet or a notebook is enough. Follow this sequence rather than jumping straight to a library output.
- Collect predictions on data the model did not train on.
- Compare each prediction with its trusted actual label.
- Choose and document the positive class.
- Count TP, FP, FN, and TN.
- Calculate precision, recall, F1, and accuracy.
- Review examples behind each error category.
A compact worksheet formula set looks like this:
TP = 18
FP = 7
FN = 5
TN = 70

precision = TP / (TP + FP)
recall = TP / (TP + FN)
f1 = 2 * TP / (2 * TP + FP + FN)
accuracy = (TP + TN) / (TP + FP + FN + TN)
If a denominator is zero, the metric is undefined. For example, precision has no ordinary value if the model never predicts positive. Treat that as a diagnostic event, not a number to hide.
🐍 10. Calculate the Metrics in Python
For production analysis, use a well-maintained metrics library and preserve the underlying counts. The following example uses common Python tooling for binary labels where 1 means positive and 0 means negative.
from sklearn.metrics import confusion_matrix
from sklearn.metrics import precision_score, recall_score, f1_score, accuracy_score

y_true = [1, 1, 1, 0, 0, 0, 1, 0]
y_pred = [1, 0, 1, 0, 1, 0, 1, 0]

tn, fp, fn, tp = confusion_matrix(y_true, y_pred).ravel()

print({"TP": tp, "FP": fp, "FN": fn, "TN": tn})
print("Precision:", precision_score(y_true, y_pred, zero_division=0))
print("Recall:", recall_score(y_true, y_pred, zero_division=0))
print("F1:", f1_score(y_true, y_pred, zero_division=0))
print("Accuracy:", accuracy_score(y_true, y_pred))
Check your library’s official documentation for current parameter behavior. In particular, verify which label is treated as positive, how missing classes are handled, and whether you need sample weights.
The zero_division setting prevents a runtime warning from becoming a surprise. Still, log the condition: a model that predicts no positives may be unsuitable even if a dashboard displays a neat zero.
🎚️ 11. Tune the Classification Threshold Instead of Accepting 0.5
Many models output a probability or score, not an immediate yes-or-no decision. A threshold converts that score into a predicted class. The common threshold of 0.5 is a convention, not a universal best choice.
probability = 0.37
threshold = 0.30
prediction = 1 if probability >= threshold else 0
Lowering the threshold usually labels more cases as positive. Recall tends to rise because the model catches more true positives, while precision often falls because it also creates more false positives.
| Threshold choice | Typical effect | Useful when |
|---|---|---|
| Lower threshold | More positive flags; higher recall; often lower precision | Missing positives is costly |
| Higher threshold | Fewer positive flags; often higher precision; lower recall | False alerts are costly |
| Default threshold | Convenient baseline, not a policy decision | Starting evaluation only |
Test several thresholds on a validation set. Select one using a documented objective, such as minimum recall required by a safety process, maximum review queue size, or expected cost of errors.
📈 12. Use Precision-Recall Curves for Rare Events
A precision-recall curve shows precision and recall across many thresholds. It is especially informative for rare positive classes because it keeps attention on positive-case performance.
Use the curve to ask practical questions: “Can we achieve at least 90% recall while keeping precision above 60%?” or “What review volume results from a threshold that catches 95% of suspected defects?”
from sklearn.metrics import precision_recall_curve

probabilities = [0.92, 0.18, 0.76, 0.41, 0.08]
y_true = [1, 0, 1, 0, 0]

precision, recall, thresholds = precision_recall_curve(y_true, probabilities)
Do not select a threshold by staring only at the prettiest curve. Translate candidate thresholds into TP, FP, FN, operational workload, and impact on affected users.
🗂️ 13. Handle More Than Two Classes With Care
Multiclass classifiers choose among three or more categories, such as support tickets labeled billing, technical, cancellation, or other. You can calculate precision, recall, and F1 for each class by treating that class as positive and all others as negative.
Then choose an averaging method that matches your question.
| Average | What it does | Best use |
|---|---|---|
| Macro | Calculates each class metric, then gives every class equal weight | Every category matters, including rare ones |
| Weighted | Averages class metrics weighted by class frequency | Summary of overall observed workload |
| Micro | Combines all class decisions before calculating | Overall instance-level performance |
from sklearn.metrics import f1_score

macro_f1 = f1_score(y_true, y_pred, average="macro")
weighted_f1 = f1_score(y_true, y_pred, average="weighted")
Report per-class results alongside an average. A high weighted F1 can mask poor performance on a rare but critical category.
📝 14. Evaluate LLM Classifiers and AI Judges Differently
Large language models can classify text, route requests, extract fields, and score generated answers. The same confusion-matrix metrics apply once you convert outputs into a stable label set and compare them with reviewed ground truth.
Use a constrained prompt so outputs are easier to parse and evaluate:
You are a support ticket classifier.
Classify the ticket as exactly one label:
BILLING, TECHNICAL, CANCELLATION, or OTHER.
Return only the label.

Ticket: "I was charged twice for my subscription."
For subjective tasks, such as whether an answer is helpful, define a rubric and use more than one qualified reviewer when possible. An LLM acting as a judge can help scale preliminary evaluation, but it can share biases with the model being evaluated and should not replace human review in high-impact contexts.
Version your prompt, label definitions, test set, model configuration, and parsing rules. A small wording change can alter metric results.
🧪 15. Create a Test Set That Measures Reality
Metric math cannot rescue weak ground truth. Your evaluation set should resemble the inputs the model will handle after deployment, including messy, ambiguous, rare, and adversarial cases.
- Separate training, validation, and final test data to prevent leakage.
- Include recent examples if data patterns change over time.
- Define label instructions before annotation begins.
- Audit disagreements between reviewers and unclear categories.
- Slice results by language, region, device, customer segment, or input length when relevant and lawful.
A classic mistake is testing on near-duplicates of training examples. The resulting precision, recall, F1, and accuracy may be mathematically correct but operationally misleading.
🔎 16. Inspect Errors, Not Just Scorecards
A metric tells you how much error exists. Error analysis helps reveal why it exists and what to change.
Sample examples from each confusion-matrix quadrant. False negatives may expose missing vocabulary, weak retrieval, low-quality inputs, or a threshold that is too strict. False positives may reveal overly broad rules, confusing neighboring classes, or label ambiguity.
error_type = []
for actual, predicted in zip(y_true, y_pred):
    if actual == 1 and predicted == 1:
        error_type.append("TP")
    elif actual == 0 and predicted == 1:
        error_type.append("FP")
    elif actual == 1 and predicted == 0:
        error_type.append("FN")
    else:
        error_type.append("TN")
Group errors by meaningful features: source, language, product line, document length, confidence range, or time period. Fixing a repeated failure pattern is more valuable than chasing a tiny aggregate score increase.
🛡️ 17. Consider Cost, Privacy, Fairness, and Human Oversight
No metric decides what is acceptable on its own. A false negative in a clinical triage tool, a false positive in content moderation, and an incorrect fraud block can affect people in very different ways.
Make the trade-off explicit with stakeholders. Specify who reviews flagged cases, how users can appeal or correct decisions, and what happens when the model is uncertain.
- Minimize collection of personal data used for evaluation.
- Remove or protect sensitive identifiers in test records.
- Measure error rates across relevant groups where appropriate and legally permitted.
- Do not infer protected traits solely to create a metric dashboard.
- Keep humans in the loop for consequential or uncertain decisions.
Also watch for data drift: the input distribution or meaning of labels can change after launch. Recalculate metrics on fresh, responsibly collected labeled data instead of assuming the initial test score lasts forever.
📊 18. Build a Monitoring Report People Can Act On
A useful evaluation report combines numbers, context, and decisions. Avoid a dashboard that reports only one green accuracy tile.
For every model release or monitoring interval, include:
- The task, positive-class definition, model or prompt identifier, and evaluation period.
- TP, FP, FN, and TN counts, not only percentages.
- Precision, recall, F1, and accuracy with the chosen threshold.
- Per-class and relevant subgroup results.
- Examples of representative failures and likely causes.
- Comparison with the previous approved baseline.
- A clear next action: ship, tune threshold, collect labels, retrain, or pause.
Small test sets create volatile metrics. Report the number of examples behind a result, and avoid declaring meaningful improvement from a handful of cases. For high-stakes applications, involve qualified statisticians or domain experts in evaluation design.
🚀 19. Use This Quick-Start Checklist
- Define the positive class in plain language.
- Gather a representative, held-out set with trustworthy labels.
- Count TP, FP, FN, and TN before interpreting any percentage.
- Calculate precision for false-alert quality, recall for missed-positive coverage, F1 for balance, and accuracy for overall correctness.
- Check class imbalance before celebrating accuracy.
- Test multiple thresholds against real error costs and review capacity.
- Report per-class metrics and inspect concrete mistakes.
- Monitor fresh data, drift, privacy risks, and subgroup outcomes after release.
The best model metric is not the highest-looking number—it is the measure that exposes the mistakes your AI system cannot afford to make. 🤖📏✅