
AI systems are increasingly expected to answer questions from private documents, follow company rules, and stay current as information changes. That creates a practical design choice: should you give a model access to external knowledge at runtime, or change the model itself through training?
Retrieval-augmented generation (RAG) and fine-tuning solve different problems, even though both can make an assistant feel more specialized. Confusing them often leads to expensive training projects, unreliable answers, or a search system that cannot enforce the behavior users need.
The stakes are higher now because teams are moving AI from demos into customer support, internal search, coding assistants, and content workflows. They need answers that are current, traceable, secure, and affordable to maintain.
After reading, you will be able to distinguish knowledge problems from behavior problems, choose RAG, fine-tuning, or a hybrid approach, and build a practical evaluation plan before committing engineering time and budget.
🧭 1. Start With the Core Difference
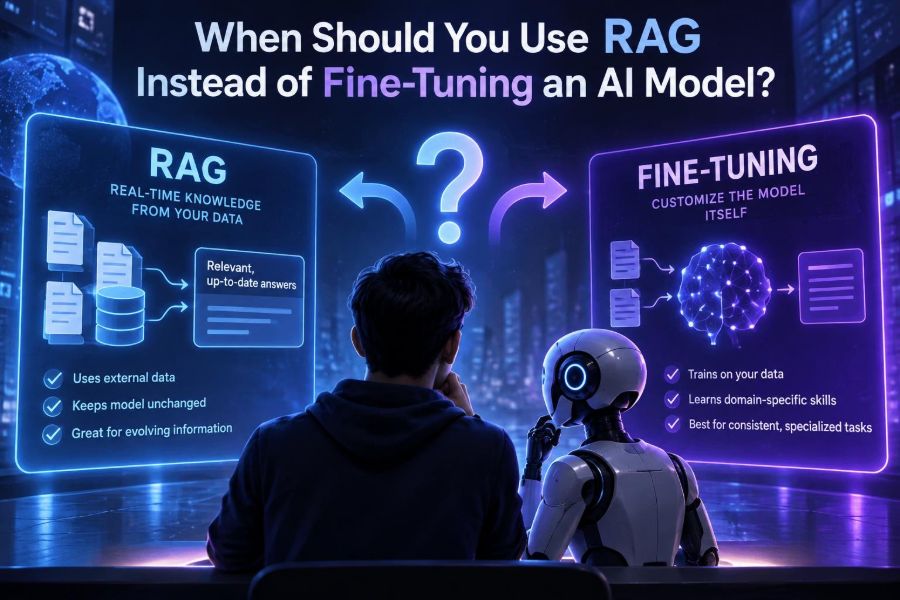
RAG gives a model relevant external context just before it produces an answer. A retrieval system searches approved sources, selects useful passages, and inserts them into the model’s input.
Fine-tuning updates a model’s learned parameters using example inputs and desired outputs. It is primarily a way to shape behavior, format, tone, decision patterns, or task performance, not a dependable document database.
| Question | RAG is usually stronger | Fine-tuning is usually stronger |
|---|---|---|
| Where does the answer come from? | Current documents, records, manuals, and policies | Patterns learned from examples |
| How quickly can it change? | Update or re-index source content | Prepare data and run another training cycle |
| Can users inspect evidence? | Yes, return retrieved passages and source metadata | Not reliably; knowledge is embedded in parameters |
| What is optimized? | Grounded answers and freshness | Consistent outputs and repeated task behavior |
📚 2. Choose RAG When Knowledge Changes
Use RAG when the correct answer depends on information that changes often: product documentation, ticket status, inventory, regulations, contracts, release notes, or a company wiki.
A fine-tuned model may memorize fragments from training examples, but it has no built-in way to know whether those fragments are still true. RAG lets the answer draw from the latest approved source.
- Employee handbook updated this week
- Technical runbook revised after an incident
- Customer account details stored in a secure system
- Large catalog with frequently changing attributes
- Research library that grows every day
A useful test is simple: if someone asks, “What changed since last month?” your default should be RAG or a direct tool/API integration.
🎯 3. Choose Fine-Tuning When Behavior Is the Problem
Fine-tuning becomes attractive when your issue is not missing facts, but inconsistent behavior that persists even with good prompts and examples. Think of tasks that recur at high volume and have a stable definition.
Examples include classifying support tickets into internal labels, converting notes into a strict schema, producing a house style, extracting fields from a repeated document type, or following a specialized response workflow.
Input: “The delivery arrived damaged and the customer wants a replacement.”
Desired output:
{
  "category": "shipping_damage",
  "priority": "high",
  "next_action": "replacement_review"
}
If hundreds or thousands of carefully reviewed examples define the desired output, fine-tuning can reduce prompt length and improve consistency. It still needs evaluation, because training does not guarantee correct reasoning on every new case.
🔎 4. Understand the RAG Pipeline
A practical RAG system has more moving parts than “upload documents and chat.” Its quality depends on retrieval as much as on the language model.
- Collect authoritative content.
- Extract clean text while preserving titles, sections, dates, permissions, and source identifiers.
- Split documents into useful chunks.
- Convert chunks into searchable representations and store them in an index.
- Retrieve candidate chunks for each question.
- Optionally rerank those candidates for relevance.
- Ask the model to answer only from the selected evidence.
- Display citations, uncertainty, or a refusal when evidence is inadequate.
Retrieval can use semantic similarity, keyword matching, metadata filters, or a hybrid of all three. Hybrid retrieval is often helpful because exact product codes and names may be poorly handled by semantic matching alone.
🧩 5. Prepare Documents Before You Embed Them
RAG quality begins with document hygiene. A perfect model cannot recover facts hidden in an unreadable PDF, duplicated across conflicting pages, or mixed with outdated policies.
Remove navigation clutter, repeated headers, broken OCR artifacts, and irrelevant boilerplate. Preserve structural context, because “Returns” in a policy handbook means more than a paragraph copied without its heading.
- Attach metadata: source, owner, publication date, version, audience, and access level.
- Mark superseded documents so they are excluded or ranked lower.
- Keep tables intact where possible; convert them to understandable text if needed.
- Separate unrelated topics instead of making one giant knowledge file.
- Set a review owner for each important source.
Do not embed secrets, credentials, or raw sensitive exports simply because your index has access controls. Treat retrieval content as data that may be surfaced to users and logs.
✂️ 6. Chunk for Meaning, Not Arbitrary Length
Chunking divides source text into retrieval units. Chunks that are too small lose the conditions needed to interpret a rule; chunks that are too large bring irrelevant text into the prompt and make retrieval less precise.
Start by splitting at headings, paragraphs, or semantic boundaries. Add modest overlap only when a concept naturally spans boundaries, such as a procedure whose prerequisite appears immediately before the steps.
Document: Expense Policy
Section: International travel meals
Rule: Reimburse meals up to the local daily allowance.
Exception: Client-hosted meals require an attendee list.

Metadata:
source=expense_policy
version=current
audience=employees
section=international_travel
Test chunks by reading them independently. If a reviewer cannot tell what a chunk means or when it applies, the model will struggle too.
🗂️ 7. Add Metadata Filters and Permissions
Semantic relevance is not enough. A highly relevant confidential document is still the wrong result for a user who is not allowed to see it.
Apply authorization filters before retrieval or at the earliest reliable stage. Filter by tenant, team, project, geography, document status, and user role when your application requires them.
retrieval_filter = {
  "tenant_id": current_user.tenant_id,
  "visibility": {"in": current_user.allowed_visibility},
  "status": "published"
}
results = search(query, filter=retrieval_filter)
Never depend on the model to honor permissions merely because your prompt says “do not reveal confidential information.” Access control belongs in the data and application layers.
🧠 8. Use a Grounding Prompt That Permits “I Don’t Know”
Retrieved context helps, but it does not force a model to use it. Your answer instruction should establish an evidence boundary and make abstaining an acceptable outcome.
You are a policy assistant. Answer using only the provided sources.
If the sources do not contain enough information, say that you cannot verify the answer.
Do not invent policy details. Cite source titles and sections used.

Question: Can a contractor claim a client-hosted dinner?

Sources:
[1] Expense Policy, International travel meals: ...
[2] Contractor Guide, Expenses: ...
Keep the instruction direct. Asking for elaborate hidden reasoning is neither necessary nor a reliable safety mechanism. Ask instead for a concise answer, supporting source references, and any missing information.
📏 9. Evaluate Retrieval Separately From Generation
When a RAG answer is wrong, teams often blame the model. In reality, the needed passage may never have been retrieved, may be outranked, or may have been truncated before generation.
Build a test set of real questions with expected source passages and expected answers. Include easy questions, ambiguous wording, exact identifiers, outdated-information traps, and questions that should receive “not found.”
| Metric or review | What it reveals |
|---|---|
| Retrieval recall | Whether the needed evidence appears among retrieved results |
| Ranking quality | Whether the best evidence appears near the top |
| Groundedness | Whether claims are supported by supplied context |
| Answer correctness | Whether the response answers the user’s question accurately |
| Abstention quality | Whether the system avoids unsupported answers |
Review failures manually at first. Automated graders can help at scale, but they should not be the only judge for high-stakes domains.
🧪 10. Try Better Retrieval Before Fine-Tuning
A common mistake is fine-tuning because a RAG prototype gives weak answers. First inspect the pipeline. Retrieval improvements are often cheaper, faster, and more transparent than training.
- Rewrite vague queries into a search-oriented query.
- Use hybrid keyword and semantic search.
- Rerank the top retrieved candidates.
- Filter to current, authorized, and relevant document sets.
- Improve chunk boundaries and metadata.
- Retrieve fewer, stronger passages rather than dumping entire documents.
- Ask a clarifying question when the query is underspecified.
For example, “What is the travel limit?” is ambiguous. The answer may depend on location, role, expense type, and whether the trip is domestic or international.
🛠️ 11. Fine-Tune With Clean, Representative Examples
If fine-tuning is justified, your dataset matters more than sheer volume. Examples should represent the inputs users actually send, including edge cases and valid ways to say the same thing.
Each example should show the exact behavior you want. Inconsistent labels, contradictory styles, and poorly reviewed answers teach the model inconsistency.
{
  "messages": [
    {"role": "user", "content": "Summarize this incident for an executive."},
    {"role": "assistant", "content": "Impact: ...\nStatus: ...\nNext decision: ..."}
  ]
}
Keep a separate test set that never appears in training. If you test on training examples, you measure memorization rather than useful generalization.
🧾 12. Fine-Tune for Format and Workflow, Not a Living Wiki
Fine-tuning can make outputs more predictable when a prompt alone is too fragile or expensive. It is particularly useful for stable structured tasks with strict output conventions.
Good candidates include:
- Classifying inbound requests into a fixed taxonomy
- Producing validated JSON for a well-defined workflow
- Transforming jargon-heavy notes into a standardized report
- Matching a carefully defined editorial voice
- Selecting a next step from a stable operational playbook
It is a poor substitute for a changing manual, customer records, legal text, or documents that must be cited. Train a model on “how to respond,” then use RAG to supply “what is currently true.”
🔀 13. Combine RAG and Fine-Tuning When Both Needs Exist
Many production assistants need both techniques. Fine-tuning can standardize the interaction pattern, while RAG provides fresh, auditable facts.
Imagine a support assistant: RAG retrieves the current product instructions and account-safe troubleshooting articles; a fine-tuned model turns those findings into a concise response with a required troubleshooting sequence and escalation format.
User question
  → permission-aware retrieval
  → current source passages
  → behavior-tuned model
  → answer + citations + escalation decision
Build the RAG foundation first when facts are central. Otherwise, you risk creating a polished assistant that confidently delivers stale information.
💸 14. Compare the Operational Costs
Neither approach is free. RAG has recurring work around ingestion, indexing, search quality, permissions, and source governance. Fine-tuning has data curation, training, evaluation, model lifecycle management, and possible retraining costs.
Cost is not only infrastructure spend. Include expert review time, incident risk, latency, prompt length, and the cost of being wrong.
| Operational concern | RAG | Fine-tuning |
|---|---|---|
| Content updates | Usually re-index affected content | Usually retrain or accept stale learning |
| Traceability | Can expose sources per answer | Hard to attribute learned facts |
| Data preparation | Document cleanup and metadata | High-quality input/output examples |
| Failure investigation | Inspect retrieval and context | Harder to isolate learned behavior |
| Typical risk | Wrong or missing retrieval | Overfitting, drift, stale knowledge |
⚠️ 15. Avoid These Common Mistakes
Mistake: embedding everything. More documents can mean more noise, conflicts, and sensitive exposure. Curate sources and define ownership.
Mistake: treating citations as proof. A model can attach a source that is only loosely related. Verify that the cited passage actually supports the claim.
Mistake: fine-tuning on raw company documents. Documents do not automatically become good instruction-response examples. You may spend heavily and still get poor factual recall.
Mistake: skipping negative tests. Test what happens when the answer is absent, the user asks for restricted information, or sources conflict.
Mistake: optimizing a demo instead of a workflow. A handful of impressive questions does not reveal how a system performs on ambiguous, messy, real user inputs.
🔐 16. Design for Privacy, Security, and Responsible Use
Both RAG and fine-tuning can expose sensitive information if data handling is careless. Understand where documents, prompts, logs, embeddings, training examples, and model outputs are stored and who can access them.
- Minimize collected data and remove sensitive fields where possible.
- Use role-aware retrieval and tenant isolation.
- Set retention rules for prompts, documents, and logs.
- Review vendor data-processing terms and official security documentation.
- Provide a human escalation path for financial, medical, legal, safety, or employment decisions.
- Monitor for prompt injection in retrieved content, such as text that tries to override system instructions.
Retrieved documents are untrusted input. Tell the model to treat them as reference material, not as instructions, and sanitize or flag suspicious content in your ingestion pipeline.
🧭 17. Use a Simple Decision Framework
Ask these questions in order. They turn an abstract architecture debate into a product decision.
- Does the answer depend on changing or private facts? Choose RAG or a direct tool connection.
- Must users see evidence or source citations? Choose RAG.
- Is the desired behavior stable and repeated across many examples? Consider fine-tuning.
- Can careful prompting and retrieval improvements solve it? Try those first.
- Do you need both current facts and rigid behavior? Use a hybrid design.
- What happens when the system is wrong? Increase evaluation, constraints, and human review as risk rises.
For transactional facts such as an order status or account balance, an authenticated API is often better than RAG. Retrieval is useful for explanatory documentation; direct systems of record are better for exact live values.
🚀 18. Build a Small Pilot Before You Commit
Start with one narrow, valuable workflow, such as answering questions from a single approved handbook or routing one type of support request. Define success before choosing the final architecture.
- Collect 30 to 100 representative user questions.
- Label the expected source, answer, or action for each.
- Build a minimal permission-aware RAG prototype.
- Measure retrieval and answer quality with human review.
- Improve sources, chunking, filters, and prompts.
- Identify remaining behavior failures.
- Only then test fine-tuning against the same held-out set.
- Compare accuracy, safety, latency, maintenance effort, and user trust.
This sequence prevents training from becoming a reflex. It also produces the evaluation data you will need regardless of which architecture wins.
✅ 19. Quick-Start Checklist
- Define whether your problem is knowledge, behavior, or both.
- Use RAG for changing, private, large, or citeable information.
- Use direct APIs for live transactional data when available.
- Use fine-tuning for stable, repeated output patterns backed by reviewed examples.
- Clean documents, preserve metadata, and enforce permissions before retrieval.
- Require grounded answers and allow the system to say it lacks evidence.
- Evaluate retrieval separately from generation.
- Test absent answers, conflicting sources, restricted content, and adversarial instructions.
- Start with a narrow pilot and measure outcomes on held-out real questions.
- Use a hybrid design when current knowledge and consistent workflow behavior both matter.
Use RAG to give AI trustworthy, current knowledge; use fine-tuning to teach it stable ways of working—and combine them only when your real workflow needs both. 🤖📚⚙️