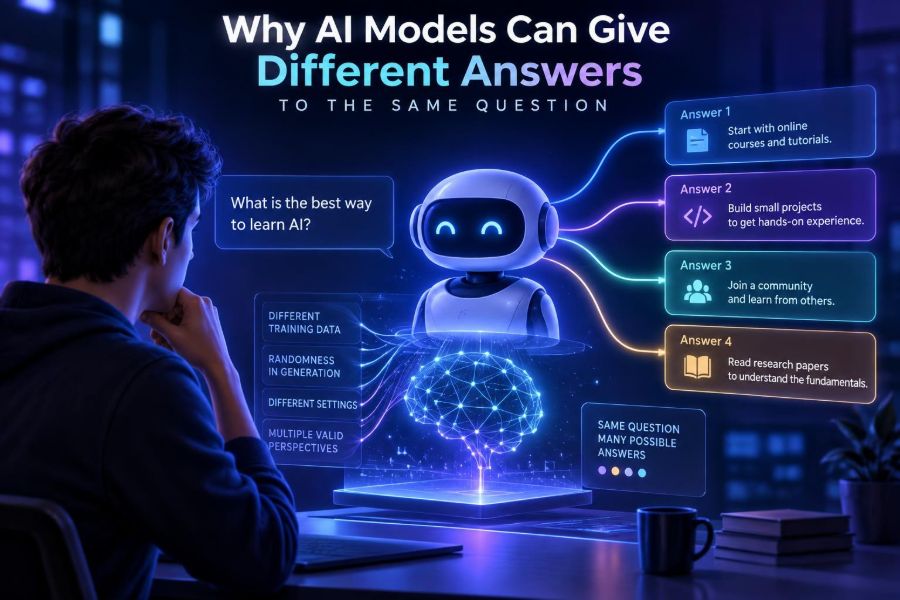

Ask an AI assistant a question twice, and it may give you two answers: one concise, one detailed; one cautious, one unexpectedly creative. That can feel unreliable, especially when you are using AI for work, code, research, or customer-facing content.
But different answers are not automatically a bug. Modern generative AI is designed to predict plausible next pieces of text, and several layers of the system can influence which plausible path it takes. Some variation is useful; some is a signal to slow down and verify.
This matters more now because people increasingly use models as collaborators, search aides, coding assistants, and automated workflow components. A small wording change or model-setting change can affect an output far more than many users expect.
By the end, you will be able to identify why answers vary, test whether a difference is meaningful, write prompts that produce more stable results, and build AI workflows that are safer to repeat.
🧭 1. The short answer: AI generates, it does not retrieve one fixed response
A generative language model does not usually keep a single hidden answer for every question. It processes your input and estimates which token, or small text unit, should come next.
At each step, many next tokens can be reasonable. The model may choose a different one on another run, and that small early difference can send the response in a completely different direction.
Key idea: identical input can produce multiple valid continuations. The effect compounds because each generated token becomes context for the token after it.
🎲 2. Sampling introduces intentional variation
Models assign probabilities to possible next tokens. Instead of always choosing the single most likely token, a system may sample from several likely options. This produces language that is less repetitive and often more natural or inventive.
Imagine a model deciding how to begin a response. “The,” “First,” “It,” and “In” may all be plausible. Picking one changes the sentence, then the paragraph, and sometimes the entire answer.
- Low variation: more repeatable, direct, and conservative output.
- High variation: more diverse, expressive, and occasionally surprising output.
- No variation is not the same as correctness: a repeatable mistake is still a mistake.
🌡️ 3. Temperature changes the model’s willingness to take a chance
Temperature is a common setting that reshapes the probability distribution before tokens are selected. Lower values concentrate choices around the most likely words; higher values make less-likely options more available.
Temperature is useful when matched to the task. A product-name brainstorm and a financial-policy summary should not generally use the same setting.
| Task | Useful variation level | Why |
|---|---|---|
| Extract fields from a document | Low | You want stable formatting and minimal invention. |
| Write a factual explanation | Low to moderate | Clarity matters, but wording can vary. |
| Brainstorm campaign concepts | Moderate to high | Novel combinations are valuable. |
| Generate test cases | Moderate | Coverage benefits from diversity and constraints. |
Exact controls and supported ranges differ by provider and model. Check the official documentation for the system you use, then test settings on examples from your real task.
🔎 4. Top-p and top-k limit the candidate pool
Other sampling controls can change output even when temperature stays the same. Top-p, sometimes called nucleus sampling, selects from the smallest group of tokens whose combined probability crosses a threshold. Top-k limits selection to a fixed number of the most likely candidates.
These settings act like different filters on the model’s vocabulary. Their interactions can be non-obvious, so changing every control at once makes troubleshooting difficult.
- Choose one representative prompt.
- Keep the model, instructions, and inputs fixed.
- Change only one sampling parameter.
- Run several trials and record what changes.
- Select settings based on output quality, not merely similarity.
A common mistake is setting temperature, top-p, and top-k aggressively at the same time without knowing which control caused the behavior.
🧩 5. Your prompt is part of the program
Two questions that look nearly identical to a person can steer a model differently. Specific words establish a task, audience, level of caution, format, and definition of success.
Compare these prompts:
Explain vector databases.Explain vector databases to a product manager in 120 words or fewer. Define embeddings first, use one concrete example, and do not claim that semantic search is always accurate.The second prompt narrows the set of acceptable answers. It will not guarantee perfection, but it gives the model a much clearer target.
🗣️ 6. Hidden instructions and conversation context matter
What you see in the chat box may not be the full input. Many AI products include system-level instructions that define tone, safety behavior, tool use, formatting, or task priorities.
Previous messages also matter. An assistant that has just discussed a Python project, a preferred writing style, or a company policy may reasonably interpret your next short question through that context.
- Start a new conversation when you need a clean comparison.
- Paste the complete relevant context when asking someone else to reproduce a result.
- State assumptions instead of relying on chat history to preserve them.
- Remember that product interfaces may add instructions you cannot inspect.
🧠 7. Models can interpret an ambiguous question in several ways
Natural language leaves gaps. “What is the best database for AI?” could mean a vector database, a relational database with AI features, a database for model telemetry, or a data platform for training.
When the question supports several interpretations, different answers may each be sensible. The model might choose one interpretation, ask a clarification question, or cover several possibilities.
Reduce ambiguity by including the decision you are making, constraints, and evaluation criteria.
I am building semantic search for 500,000 product documents. Compare storage approaches for embeddings. Prioritize filtering, update frequency, operational simplicity, and cost predictability. Ask one clarification question if a missing requirement would change the recommendation.🧬 8. Different model families have different learned patterns
Not all AI models are trained on the same data, objectives, architecture, or post-training process. Even models that appear equally capable can differ in writing style, coding habits, multilingual performance, refusal behavior, and ability to follow a narrow format.
A model may favor a familiar explanation while another synthesizes a different framing. Neither response should be treated as authoritative merely because it sounds confident.
When comparing models, use a small evaluation set drawn from your actual work. One impressive demo prompt is not a reliable model-selection process.
🔄 9. Model updates can change answers over time
Providers may update model weights, safety systems, routing logic, tools, or infrastructure. A product may also direct the same request to different underlying models depending on availability or selected mode.
This means a prompt that worked last month can behave differently today, even if you have not changed a word. For important workflows, record the model identifier when available and keep version-sensitive tests.
- Save successful prompts and example outputs.
- Track model name or deployment identifier in logs.
- Rerun an evaluation suite after a model change.
- Use acceptance checks rather than assuming old behavior persists.
📚 10. Retrieval and live tools can create a changing evidence base
Some AI systems search documents, browse approved sources, call databases, or use other tools before responding. This can improve relevance, but it adds moving parts.
A retrieval system may find different documents because an index changed, a ranking threshold shifted, permissions changed, or a query was rewritten. A live data tool can also return different results as the underlying world changes.
For a reproducible result, capture the retrieved document identifiers, snippets, timestamps, and tool parameters alongside the final answer. Treat retrieval quality as a separate problem from generation quality.
⚙️ 11. Small engineering details can break reproducibility
Developers sometimes send what they believe is the same request while changing whitespace, message order, locale, attached data, tool availability, output limits, or structured-output instructions. Any of these can influence the result.
Output length is especially important. A low token limit can cut off reasoning or force the model to compress an answer, changing its conclusion or structure.
request = {
  "model": "your-selected-model",
  "messages": [
    {"role": "system", "content": "Be concise. Return valid JSON only."},
    {"role": "user", "content": "Classify this support ticket: ..."}
  ],
  "temperature": 0,
  "max_output_tokens": 300
}

# Log the complete request, response, model identifier,
# timestamp, retrieved context, and validation result.
Parameter names vary across APIs. The pattern matters: make the request explicit, then log enough information to replay the conditions.
🎯 12. A seed can help, but it is not a universal guarantee
Some platforms offer a seed: a number used to initialize random sampling. Reusing it can make outputs more consistent under the same conditions.
However, a seed is not a promise of permanent byte-for-byte reproducibility. Model updates, distributed infrastructure, numerical differences, tool calls, and undocumented product changes can still alter results.
Use seeds as a debugging aid, not as your only quality-control strategy. If an output has legal, medical, financial, or security consequences, validate it independently.
🧪 13. Test variation instead of judging one answer
A single response tells you very little about reliability. Run the same task multiple times and evaluate the properties that actually matter: factual support, schema validity, completeness, helpfulness, safety, and latency.
Here is a lightweight testing process:
- Collect 20 to 100 representative inputs, including difficult edge cases.
- Write explicit pass criteria for each task.
- Run multiple generations per input if variation is expected.
- Score outputs with human review, automated checks, or both.
- Investigate patterns, not isolated failures.
For extraction, compare against expected fields. For writing, use a review rubric. For code, run tests, linters, security scans, and a human review appropriate to the risk.
🧱 14. Constrain the output when consistency matters
Models are easier to integrate when you request a clear structure. Asking for a specific schema, bounded fields, and allowed values reduces freedom in ways that are useful for automation.
Extract the ticket information below.

Return only this structure:
{
  "category": "billing | bug | access | other",
  "priority": "low | medium | high",
  "summary": "string under 20 words",
  "needs_human_review": true
}

If the category is unclear, choose "other".
Ticket: "I was charged twice after changing plans."
Then validate the result in code. Do not rely on a prompt alone to enforce a business rule.
allowed = {"billing", "bug", "access", "other"}
if result["category"] not in allowed:
    raise ValueError("Invalid category")
if len(result["summary"].split()) > 20:
    raise ValueError("Summary is too long")
📝 15. Use a prompt template that removes guesswork
A reusable template makes both human and automated use more predictable. Include the task, source material, constraints, desired format, and uncertainty behavior.
Task: [what to produce]
Audience: [who will use it]
Source of truth: [paste text or name supplied documents]
Constraints: [length, tone, exclusions]
Output format: [headings, JSON fields, table columns]
Uncertainty rule: If information is missing, say "Unknown" and list what is needed.
Quality check: Before answering, verify that every claim is supported by the supplied source.
The phrase “source of truth” is valuable. It tells the model whether to rely on supplied material, general knowledge, or a tool-backed source.
🚧 16. Common mistakes that make answers drift
Many consistency problems are created by workflow design rather than model intelligence. These mistakes are easy to make because chat interfaces hide complexity.
- Vague requests: “Make this better” has no stable definition of better.
- Changing several variables: prompt edits, model switches, and parameter changes make diagnosis impossible.
- Overloading one prompt: research, analysis, writing, and formatting may work better as separate steps.
- Trusting polished language: fluency can hide unsupported claims.
- Skipping validation: valid-looking JSON may still contain wrong values.
- Using creative settings for deterministic tasks: diversity can become noise.
🛠️ 17. Build a reliable AI workflow in layers
For consequential tasks, do not ask one prompt to do everything. Break the workflow into stages that can be observed and checked.
- Prepare: normalize input and remove irrelevant noise.
- Retrieve: select approved, relevant context if needed.
- Generate: use a narrow prompt and appropriate sampling settings.
- Validate: check schema, citations, arithmetic, policy rules, or tests.
- Escalate: route uncertain or high-risk cases to a person.
- Monitor: log outcomes and regularly review failure patterns.
This layered design gives you something better than an illusion of certainty: evidence about where variability enters and where controls work.
🔐 18. Protect privacy and use variation responsibly
Do not paste sensitive personal data, private source code, credentials, customer records, or confidential strategy into an AI service unless your organization has approved that use and you understand the data-handling terms.
Different answers can also expose unequal treatment, inconsistent policy application, or unsafe advice. Test sensitive workflows across demographic-neutral variations, require human review where harm is possible, and give users a path to challenge automated outcomes.
For high-stakes decisions, AI output should support qualified judgment, not replace it. Use trusted primary sources and domain experts for verification.
✅ 19. Quick-start checklist for more consistent answers
- Define what “good” means before you write the prompt.
- Provide the audience, scope, source material, and output format.
- Use lower variation settings for extraction, classification, and policy-sensitive tasks.
- Change one parameter at a time while testing.
- Start a clean chat when comparing responses.
- Log model identifiers, prompts, settings, context, and outputs in production.
- Validate structured output with code and factual claims with reliable sources.
- Run repeated trials and evaluate patterns rather than trusting one response.
- Add human review for sensitive, costly, or irreversible decisions.
AI models give different answers because generation is a probability-driven process shaped by prompts, context, settings, tools, and changing systems—and you can manage that variation by designing clearer, testable workflows. 🤖🧪⚙️