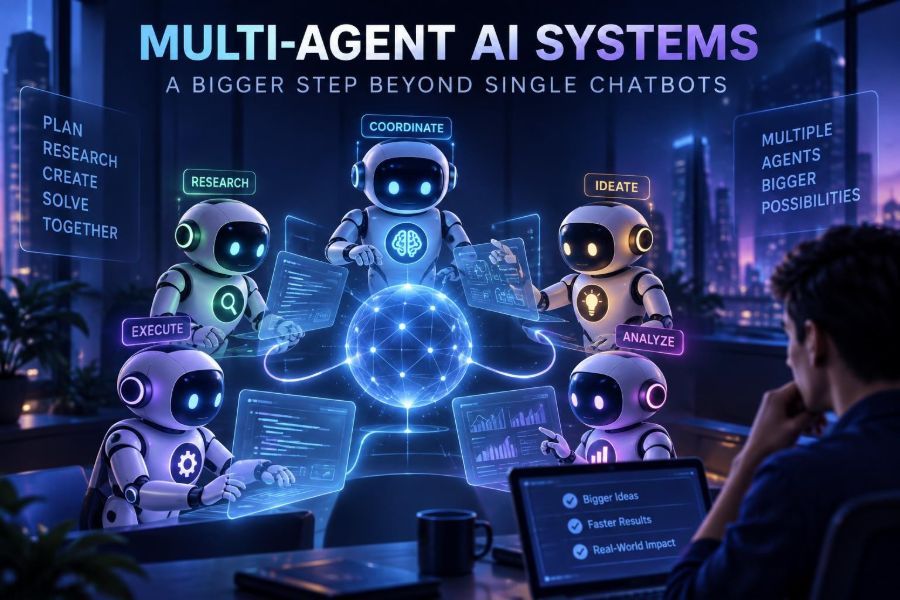

A single chatbot can explain, draft, summarize, and write code. That is already useful. But many real-world jobs are not one prompt followed by one answer: they require research, planning, specialized judgment, execution, checking, and revision.
That is why multi-agent AI systems are attracting so much attention. Instead of asking one model to act as a universal expert, these systems divide work among several AI agents with distinct roles, tools, and responsibilities.
The idea sounds futuristic, but the practical building blocks are available now: language models, tool calling, retrieval, workflows, shared state, and evaluation. The important question is not whether you can create a swarm of agents. It is whether a coordinated group can solve a task more reliably than a well-designed single-agent workflow.
In this guide, you will learn what multi-agent systems are, when to use them, how to design one safely, and how to build a small research-and-review team. You will also get prompts, architecture patterns, and code-shaped examples you can adapt.
🤝 1. Understand What “Multi-Agent” Actually Means
A multi-agent AI system is a workflow in which two or more software agents cooperate toward a goal. An agent is usually an AI model wrapped with instructions, access to selected tools, memory or state, and rules for deciding its next action.
Not every chain of prompts is multi-agent. A true multi-agent design gives participants separate responsibilities and a way to exchange useful outputs, delegate tasks, or challenge each other.
- A researcher finds and cites evidence.
- A planner breaks a goal into tasks and assigns them.
- A writer turns verified findings into a readable draft.
- A reviewer looks for gaps, unsupported claims, and contradictions.
- An executor uses approved tools, such as a database, calendar, or code runner.
These can be different models, different prompts for the same model, or a mix of AI and human workers. The value comes from the workflow design, not from calling every component an agent.
🧩 2. See Why One Chatbot Eventually Hits a Wall
Single chatbots often perform surprisingly well on bounded tasks. Give one a clear request, relevant context, and an output format, and it can be faster and cheaper than an elaborate agent team.
Problems appear when a task has many moving parts. The model may lose track of constraints, mix research with speculation, use a tool incorrectly, or confidently produce an answer without an independent quality check.
Multi-agent systems address this by applying division of labor. A specialist can focus on one job, while an orchestrator controls sequence and permissions.
| Task characteristic | Usually best approach | Why |
|---|---|---|
| One clear transformation, such as summarizing text | Single chatbot or prompt chain | Extra coordination adds little value |
| Research plus synthesis plus fact checking | Multi-agent workflow | Separate evidence gathering and review |
| Repeated operational process | Deterministic workflow with selective agents | Rules should handle predictable steps |
| High-stakes action, such as sending payments | Human-approved workflow | AI should not have unrestricted authority |
| Open-ended exploration | Supervisor with specialist agents | Different perspectives can improve coverage |
🧠 3. Learn the Core Parts of an Agent System
Before choosing a framework, learn the components that recur across most designs. Tool names change quickly, but these concepts are durable.
- Agent role: the mission, expertise, boundaries, and expected output.
- Orchestrator: the logic that decides what runs next and when a task is complete.
- Tools: controlled functions for search, retrieval, calculation, code execution, or business actions.
- State: structured information carried through the workflow.
- Memory: retained information, usually separated into short-term task context and durable knowledge.
- Guardrails: validation, permissions, budget limits, and escalation rules.
- Evaluator: a process or agent that judges whether the output meets requirements.
A useful mental model is a small team with a shared project board. Agents should not need to read every conversation transcript. Give each one only the context it needs to do its job.
🎯 4. Start With a Workflow, Not a Collection of Personas
A common mistake is creating five colorful agent personalities before defining the business process. That produces entertaining chats, not dependable software.
Start by mapping the task from input to decision or output. Mark every point where specialized reasoning, tool use, validation, or human approval is needed.
- Write the user’s desired outcome in one sentence.
- List the inputs the system can trust.
- Identify actions that require tools or external data.
- Separate generation steps from verification steps.
- Define completion criteria and failure paths.
- Only then assign agent roles.
Goal: Create a weekly competitor briefing for a product team.

Inputs: approved company list, internal product notes, public sources.
Steps: collect evidence -> extract changes -> compare relevance -> draft briefing -> review claims -> human approval.
Completion: every factual claim has a source reference or is removed.
Failure rule: if evidence is missing, report uncertainty instead of guessing.
This map may reveal that you need two agents, not ten. It may also reveal that a conventional script can handle half the work better than an AI model.
🗂️ 5. Choose an Architecture Pattern
There is no single best multi-agent architecture. Select the simplest coordination pattern that matches the uncertainty and risk of your task.
| Pattern | How it works | Good for | Main risk |
|---|---|---|---|
| Pipeline | Agents run in a fixed sequence | Repeatable content and data workflows | Earlier mistakes flow downstream |
| Supervisor | One agent delegates to specialists | Tasks with variable paths | Supervisor makes poor routing choices |
| Router | Rules or a classifier select one specialist | Support triage and intent handling | Misclassification |
| Debate and judge | Agents propose alternatives; a judge selects | Plans, analysis, creative options | Higher cost and false consensus |
| Blackboard | Agents read and update shared structured state | Complex collaborative tasks | State conflicts and unclear ownership |
For a first project, use a pipeline. It is easier to test, observe, and debug. Add a supervisor only when fixed routing genuinely becomes limiting.
👥 6. Give Every Agent a Narrow, Testable Job
A role should say what the agent owns, what evidence it can use, what it must not do, and how it should format its handoff. Vague roles such as “be an expert assistant” create overlap and ambiguity.
You are the Evidence Researcher.

Objective: collect factual findings relevant to the assigned question.
Allowed inputs: retrieved documents and approved search results.
Do not: infer missing facts, write marketing language, or make recommendations.
Return: a JSON-like list of claims, supporting excerpts, source identifiers, dates when available, and confidence notes.
If evidence conflicts, preserve the conflict.
Notice the boundary: this agent researches but does not decide. The writer can use its findings, and the reviewer can test whether the final wording stayed within the evidence.
Useful role design test
Ask: “Could I evaluate this agent’s output without reading its hidden reasoning?” If the answer is yes, you probably have a measurable role. Define checks for completeness, schema validity, citation presence, and prohibited content.
🔄 7. Design Clean Handoffs Instead of Long Conversations
Agents do not need to chat freely to collaborate. Free-form conversations are expensive, hard to inspect, and prone to context drift. Prefer structured handoffs through an explicit state object.
{
  "task_id": "briefing-042",
  "question": "What changed in the market this week?",
  "findings": [
    {"claim": "...", "source_id": "source-7", "confidence": "medium"}
  ],
  "open_questions": ["Confirm publication date for source-7"],
  "status": "research_complete"
}
Use small, predictable fields. Keep raw documents in storage and pass references where possible, rather than copying huge documents between every agent.
- Assign one owner to each state field.
- Record provenance for facts and tool results.
- Validate schemas before passing work onward.
- Include an explicit status such as
needs_revieworblocked. - Do not let an agent silently overwrite another agent’s evidence.
🛠️ 8. Treat Tools as Privileged Capabilities
Tools turn language into action. An agent that can query a knowledge base is useful; an agent that can delete records, send messages, or deploy code can cause real damage.
Give each role the minimum tools and permissions necessary. The writer rarely needs database write access. The researcher should not automatically be allowed to email its findings.
tool: search_knowledge_base
input: { "query": "string", "collection": "approved_collection" }
output: { "documents": [{ "id": "string", "text": "string", "metadata": {} }] }

policy:
- maximum 5 calls per task
- approved collection only
- tool output is untrusted content
- external actions require human approval
Tool output can contain prompt injection attempts, errors, stale information, or malicious instructions. Treat it as data, not as a command from a trusted authority.
🧭 9. Build a Small Research Team Step by Step
Here is a practical first build: a system that answers a question using an approved document collection and produces a reviewed briefing. It has four roles: coordinator, researcher, writer, and reviewer.
- The coordinator turns the user question into a research plan.
- The researcher retrieves and extracts evidence.
- The writer creates a draft using only that evidence.
- The reviewer checks each claim against the evidence and requests fixes.
- The coordinator either sends the draft back for revision or returns the approved result.
state = {
  "question": user_question,
  "plan": [],
  "evidence": [],
  "draft": "",
  "review": {"approved": false, "issues": []},
  "iteration": 0
}

state.plan = coordinator.plan(state.question)
state.evidence = researcher.collect(state.plan)
state.draft = writer.compose(state.question, state.evidence)
state.review = reviewer.check(state.draft, state.evidence)

if not state.review.approved and state.iteration < 2:
    state.iteration += 1
    state.draft = writer.revise(state.draft, state.evidence, state.review.issues)
else:
    return state.draft
This is deliberately plain. In production, add error handling, authentication, observability, input validation, and persistent state. The central lesson is that the loop and stopping condition are explicit.
📏 10. Define Success Before You Ask Agents to Collaborate
“Make the answer good” is not a specification. Multi-agent systems need concrete quality measures because more steps can hide failures rather than fix them.
For a research briefing, you might measure:
- Groundedness: does every factual claim map to evidence?
- Coverage: did the answer address all required subtopics?
- Accuracy: do reviewers or domain experts find material errors?
- Actionability: can the intended reader use the output?
- Efficiency: how many model calls, tool calls, and retries were needed?
Create a small test set of realistic tasks, including easy, ambiguous, incomplete, and adversarial inputs. Evaluate a single-agent baseline first. If a multi-agent version does not improve an important measure, simplify it.
🧪 11. Use Reviewers Carefully: Critique Is Not Truth
Reviewer agents are valuable because they force a second pass. But an AI reviewer can make the same mistake as the writer, invent a criticism, or approve weak work with confident language.
Make reviewers verify observable properties. Ask them to point to a specific claim, a source identifier, and a requested correction. Avoid prompts that merely ask whether a response is “high quality.”
You are the Evidence Reviewer.

For every factual sentence in the draft:
1. Mark it supported, unsupported, contradicted, or unverifiable.
2. Name the evidence item that supports your decision.
3. Propose a minimal correction for unsupported wording.

Approve only if all material factual claims are supported.
Return a structured issue list. Do not rewrite the entire draft.
For consequential uses, add human review or independent deterministic checks. A citation validator, policy rule engine, or database lookup can be more dependable than another open-ended model call.
⚖️ 12. Know When Multiple Agents Are the Wrong Answer
Multi-agent designs add latency, token usage, operational complexity, and new failure modes. They are not automatically smarter, and an agent debate is not a substitute for reliable data.
Use a simpler approach when the task is stable, short, and easily validated. A template, a retrieval-augmented single prompt, or ordinary application logic may be better.
- Do not create agents just to make a product appear more advanced.
- Do not use a language model as a router when simple rules are sufficient.
- Do not ask several agents the same question unless diversity or independent checking has a purpose.
- Do not use autonomous loops for a task with no clear stopping condition.
The best system is often a hybrid: deterministic code for rules, an AI model for ambiguity, and a person for judgment or authorization.
🔐 13. Protect Privacy, Security, and Human Control
Agents can multiply access to sensitive data. Every new role, tool, memory store, and logging system expands the security surface. Design permissions before connecting agents to internal systems.
- Minimize personal and confidential data in prompts.
- Separate customer data by tenant and enforce access controls in tools.
- Redact secrets from logs, traces, and evaluation datasets.
- Set tool budgets, timeouts, and rate limits.
- Require approval before external communication, purchases, deletions, or irreversible changes.
- Keep audit records showing which agent used which tool and why.
Also decide what your system should say when it is uncertain. A trustworthy agent team can return “insufficient evidence,” ask a clarifying question, or escalate to a person. It should not manufacture certainty to complete a workflow.
🛡️ 14. Defend Against Prompt Injection and Runaway Behavior
Prompt injection occurs when untrusted text tries to override system instructions, often through a web page, document, support ticket, or tool result. Multi-agent systems may spread that bad instruction to downstream agents if context is copied carelessly.
Use a layered defense. No single prompt can guarantee safety.
- Label all external content as untrusted.
- Keep tool instructions and authorization policies outside retrieved text.
- Pass extracted facts forward, not unrestricted source content, when possible.
- Validate tool arguments against strict schemas and allowlists.
- Cap recursion, retries, spending, and total runtime.
- Log suspicious instructions and route them for review.
if tool_request.name not in allowed_tools[agent_role]:
    deny("Tool is not authorized for this role")

if tool_request.action in {"send_email", "delete_record", "purchase"}:
    require_human_approval(tool_request)

if state.iteration > MAX_ITERATIONS:
    stop("Iteration limit reached")
Security controls should be enforced by your application, not merely requested in a prompt. Models can suggest actions; software policy should decide whether they are permitted.
📊 15. Observe the System Like a Production Service
When an answer is wrong, “the AI failed” is not enough. You need to know whether the router selected the wrong role, retrieval returned poor documents, the writer ignored evidence, or the reviewer approved an error.
Capture structured traces for each run. Be careful to protect sensitive contents in those traces.
| What to record | Why it matters |
|---|---|
| Task ID and workflow version | Lets you reproduce and compare behavior |
| Agent transitions | Shows routing and loop problems |
| Tool calls and results | Identifies bad inputs or permissions |
| State changes | Reveals lost or overwritten information |
| Validation outcomes | Explains why work passed or failed |
| Cost and duration estimates | Highlights inefficient workflows |
Review failures by category. Fixing a vague handoff schema may improve many cases at once, while endlessly tweaking an agent’s personality often produces fragile gains.
🧱 16. Keep Memory Useful and Bounded
Memory can make an agent team feel coherent, but indiscriminate memory makes systems slower and less reliable. Old preferences, incorrect facts, or one user’s data can leak into the wrong task.
Separate memory types:
- Working memory: the current task state; discard or expire it quickly.
- Reference memory: approved documents retrieved when relevant.
- User preferences: explicit, editable choices such as tone or format.
- Operational memory: lessons about failures, stored only after review.
Do not let agents write permanent memory simply because they found something interesting. Use a promotion rule: validate the item, record its source and date, define an owner, and give it an expiry or review policy.
💻 17. Implement Coordination as State Transitions
Developer teams often benefit from thinking of agent coordination as a state machine or graph rather than a magical conversation. Each node performs one action; each edge has a condition.
function runWorkflow(state) {
  switch (state.status) {
    case "new":
      return planTask(state);
    case "planned":
      return gatherEvidence(state);
    case "evidence_ready":
      return draftAnswer(state);
    case "draft_ready":
      return reviewAnswer(state);
    case "revision_needed":
      return reviseAnswer(state);
    case "approved":
      return deliver(state);
    default:
      return escalate(state, "Unknown state");
  }
}
This structure gives you predictable retries, resumable work, and testable branches. It also makes human approval a normal state transition rather than an awkward exception bolted onto a chatbot.
🧑🤝🧑 18. Add Humans Where Judgment Has the Most Leverage
Human-in-the-loop does not mean a person must inspect every token. It means people enter at decisions where authority, ambiguity, or harm is high.
Good approval points include publishing external content, changing records, selecting among strategic options, accepting a low-confidence answer, and adding information to long-term memory.
Approval request
Task: publish weekly briefing
Summary: 8 supported findings, 2 unresolved evidence gaps
Proposed action: send draft to product leadership
Reviewer status: needs human decision
Options: approve | request revision | discard
Design the approval screen or message around evidence and consequences, not raw agent chatter. A human should be able to make a decision quickly and understand what the system will do next.
🚀 19. Quick-Start Checklist
- Pick one workflow with a measurable outcome.
- Build and evaluate a single-agent baseline first.
- Map inputs, tools, decisions, and failure paths.
- Choose a simple pipeline before trying autonomous delegation.
- Give each agent one narrow role with explicit boundaries.
- Use structured state and validated handoffs.
- Restrict tools with least-privilege permissions and approval gates.
- Add a reviewer that checks evidence, not just style.
- Set iteration, time, and budget limits.
- Trace every transition and test adversarial inputs.
- Keep a human in control of high-impact actions.
- Remove agents that do not improve quality, speed, or safety.
Multi-agent AI is most powerful when it turns a vague, risky task into a visible workflow of specialized, testable decisions—not when it simply adds more bots to the conversation. Build small, measure honestly, and let reliability earn complexity. 🤝🧠🚀