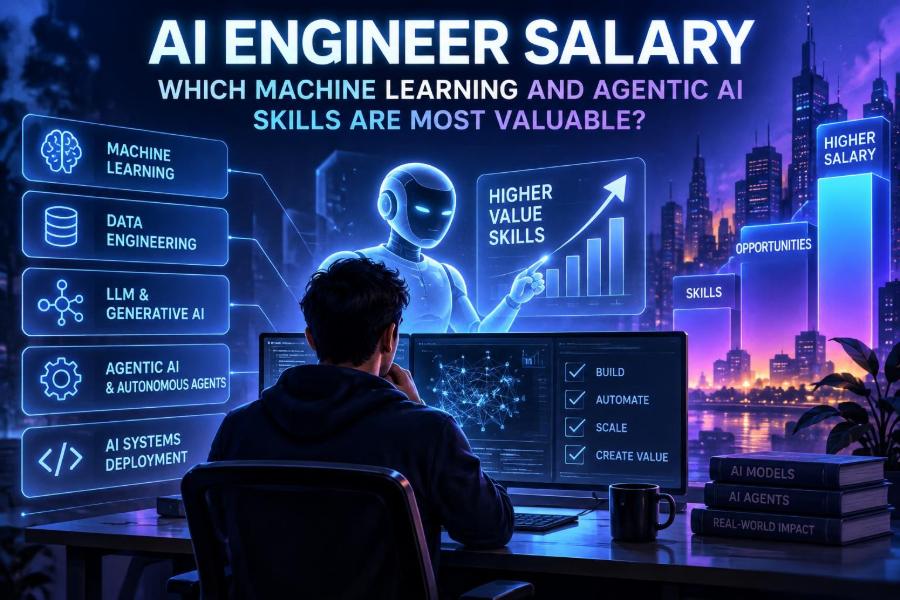

AI engineering has moved from a specialist discipline to a major capability inside product teams, startups, enterprises, and creative businesses. That shift is changing what employers pay for: not just people who can train a model, but people who can turn models into reliable systems that solve a real workflow.
The market also contains a confusing mix of titles. An AI engineer may build retrieval systems, an ML engineer may operate prediction pipelines, and an agentic AI developer may connect language models to tools and business processes. Their skills overlap, but the highest-value work is usually where technical depth meets measurable delivery.
Salary is never determined by a skills checklist alone. Location, company stage, industry, interview performance, scope, and evidence of impact all matter. Still, choosing the right skills can substantially improve the kinds of roles you qualify for and the leverage you bring to a negotiation.
By the end of this guide, you will be able to map valuable AI skills to job outcomes, choose a focused learning path, build portfolio projects that signal production readiness, and communicate your value without relying on hype.
🧭 1. Start With the Right Definition of “AI Engineer”
An AI engineer designs, builds, evaluates, and operates software that uses AI models. That can include classical machine learning, generative AI, computer vision, forecasting, recommendation, or intelligent agents.
The valuable distinction is between a demo and a system. A demo produces an impressive answer once; an engineering system handles real inputs, protects data, measures quality, fails safely, and remains maintainable after launch.
- Applied AI engineer: integrates models into products and workflows.
- ML engineer: builds data, training, serving, and monitoring systems for predictive models.
- Research engineer: implements, experiments with, and adapts advanced model techniques.
- Agentic AI engineer: designs tool-using, multi-step systems with controls and evaluation.
💰 2. Understand What Actually Drives Compensation
Employers generally pay more for scarce skills that reduce risk, accelerate revenue, or unlock a strategically important product. The most durable salary signal is not familiarity with a fashionable framework; it is the ability to own a difficult outcome.
For example, a developer who can connect a chatbot to an internal knowledge base is useful. A developer who can make that system accurate, permission-aware, observable, economical, and trusted by support teams creates much more business value.
| Compensation driver | What it looks like in practice | Strong proof |
|---|---|---|
| Business impact | Automation, conversion, retention, risk reduction | Before-and-after metrics and a clear baseline |
| Technical breadth | Data, backend, models, cloud, product integration | End-to-end deployed project |
| Technical depth | Evaluation, optimization, model adaptation, reliability | Trade-off analysis and reproducible experiments |
| Ownership | Defines requirements and manages production failures | Architecture document, runbook, stakeholder feedback |
| Domain expertise | Understands regulated or complex workflows | Relevant portfolio case study |
Use salary surveys, job listings, and official career pages as current market inputs, because pay ranges and titles change quickly. Compare roles with similar seniority, location, employment type, and scope rather than treating one published number as a universal benchmark.
🧱 3. Build the Software Engineering Foundation First
AI applications are software products. Strong coding and systems fundamentals often separate someone who can prototype from someone who can ship.
Prioritize Python for model and data work, then become comfortable with APIs, databases, testing, version control, containers, asynchronous jobs, and cloud deployment. If your target companies use another backend language, learn enough to collaborate effectively.
def validate_request(query: str, user_id: str) -> dict:
    if not user_id:
        raise ValueError("Authenticated user required")
    query = query.strip()
    if len(query) < 3:
        raise ValueError("Query is too short")
    return {"query": query, "user_id": user_id}
This tiny example is deliberately ordinary. Production AI work is full of ordinary engineering: input validation, authentication, error handling, retries, logging, tests, and interfaces that make later changes safe.
- Write a small API around an AI feature.
- Add structured logs for requests, latency, cost, and failures.
- Create tests for empty, malicious, ambiguous, and unusually long inputs.
- Containerize the service so another developer can run it.
📊 4. Become Fluent in Data, Not Just Models
Data quality is often the limiting factor in AI projects. Valuable engineers can inspect a dataset, identify leakage or bias, define labels, transform features, and explain whether the data supports the intended decision.
Learn SQL, dataframe workflows, data schemas, basic statistics, and data validation. You do not need to become a data scientist before building AI products, but you should be able to ask whether the training or retrieval data is complete, current, authorized, and representative.
SELECT category, COUNT(*) AS tickets,
       AVG(resolution_hours) AS avg_resolution_hours
FROM support_tickets
WHERE created_at >= CURRENT_DATE - INTERVAL '90 days'
GROUP BY category
ORDER BY tickets DESC;
A query like this can reveal where an AI assistant might help. It can also expose a common mistake: building an automation for the most visible workflow rather than the most costly or repetitive one.
🧠 5. Learn Classical Machine Learning for Durable Value
Generative AI has increased demand for AI builders, but classical ML remains highly valuable. Fraud detection, demand forecasting, ranking, churn prediction, anomaly detection, and pricing often call for structured-data models rather than a chatbot.
Learn the practical lifecycle: define a target, split data correctly, establish a baseline, train, validate, deploy, and monitor. Understand classification, regression, ranking, calibration, precision, recall, and feature leakage.
# Pseudocode for a safe evaluation split
train = data[data.date < "2024-01-01"]
test = data[data.date >= "2024-01-01"]
model.fit(train.features, train.label)
predictions = model.predict(test.features)
print(evaluate(predictions, test.label))
A time-aware split is important when predicting future events. Randomly mixing past and future records can make results look excellent while hiding information that would not exist in production.
🗣️ 6. Treat LLM Application Design as a Core Skill
Large language model applications require more than writing clever prompts. The valuable skill is LLM application design: choosing a model capability, setting constraints, structuring context, validating outputs, handling uncertainty, and designing an experience around imperfect generation.
Start each feature with a narrow task definition. Specify the input, desired output, unavailable information, escalation path, and measurable success criterion.
Role: You are a customer-support triage assistant.
Goal: Classify the ticket and suggest the next action.
Rules:
- Use only the ticket text provided.
- If account access or payment data is involved, set escalation=true.
- Do not invent policies or promise outcomes.
Return valid JSON with: category, urgency, escalation, rationale.
Ticket: {{ticket_text}}
Structured output makes downstream software safer. Still validate it in your application, because models can return malformed or incomplete data.
🔎 7. Master Retrieval-Augmented Generation, With Evidence
Retrieval-augmented generation, often called RAG, provides a model with relevant documents at answer time. It is useful when answers depend on changing internal knowledge, manuals, policies, or technical documentation.
A high-value RAG implementation is not simply “upload files and chat.” It needs content ingestion, chunking, metadata, search, ranking, permissions, citations, evaluation, and a policy for saying “I do not know.”
- Collect approved, current source material.
- Extract text and preserve document metadata.
- Chunk content by meaningful sections, not arbitrary fragments alone.
- Index chunks for semantic and keyword retrieval.
- Filter results by the user’s access permissions.
- Ask the model to answer only from retrieved evidence.
- Evaluate answers against a test set of real questions.
Answer the question using only the sources below.
If the sources do not support an answer, say: "I don't have enough approved information."
For each factual claim, cite its source ID.

Question: {{question}}
Sources: {{retrieved_chunks}}
Common mistake: measuring whether the answer sounds good instead of whether retrieval found the right evidence. Diagnose retrieval and generation separately, or you will optimize the wrong layer.
🛠️ 8. Build Agentic AI as Controlled Workflow Automation
Agentic AI systems can select tools, plan steps, retain task state, and act on external systems. Their promise is useful automation, but their risk is also greater: an incorrect answer is one thing; an incorrect action can change data, send a message, or trigger a transaction.
Start with a constrained workflow rather than an autonomous “general agent.” Define allowed tools, inputs, outputs, spending limits, approvals, and stop conditions.
TOOLS:
- search_knowledge_base(query)
- create_draft_reply(ticket_id, text)
- request_human_approval(ticket_id, reason)

POLICY:
- Never send a reply directly.
- Never access payment details.
- For low confidence, request human approval.
- Record the tool result and reason for every step.
The most valuable agentic AI engineers know when not to use an agent. A fixed workflow, a form, a SQL query, or a deterministic rules engine is often cheaper, faster, and easier to audit.
🧰 9. Learn Tool Integration and API Reliability
Useful agents need tools: search, databases, calendars, CRMs, code repositories, ticketing systems, and internal APIs. This makes integration engineering a premium skill.
Design tool contracts carefully. Keep tool names clear, require typed arguments, return concise machine-readable responses, and separate read-only tools from tools that modify state.
{
  "name": "create_support_draft",
  "description": "Create an unsent response draft for a support ticket.",
  "parameters": {
    "ticket_id": "string",
    "body": "string",
    "requires_review": "boolean"
  }
}- Use idempotency keys for actions that could be retried.
- Set timeouts and handle unavailable services.
- Require confirmation for consequential actions.
- Log tool calls without logging secrets or unnecessary personal data.
- Apply least-privilege access for every integration.
🧪 10. Make Evaluation Your Competitive Advantage
Evaluation is one of the clearest differentiators in AI engineering. Teams need someone who can answer, “Is this system improving?” instead of relying on a few hand-picked examples.
Build an evaluation set from representative, permissioned tasks. Include ordinary requests, edge cases, adversarial inputs, outdated-information cases, and examples where the correct behavior is refusal or escalation.
| System type | Useful evaluation signals | Failure to watch |
|---|---|---|
| Classifier | Precision, recall, calibration | Missing high-risk cases |
| RAG assistant | Retrieval relevance, groundedness, citation accuracy | Confident unsupported claims |
| Agent workflow | Task completion, tool accuracy, intervention rate | Unsafe or unnecessary actions |
| Creative generator | Human preference, instruction adherence, brand fit | Inconsistent output or rights issues |
evaluation_case = {
  "input": "Can I change my plan after renewal?",
  "expected_behavior": "Answer from policy and cite it; escalate if policy is absent.",
  "risk_level": "medium"
}
Run evaluations after prompt edits, model changes, retrieval changes, and tool changes. Treat prompts and datasets as versioned production artifacts, not informal notes.
📡 11. Operate AI Systems With Observability and MLOps
Shipping is the beginning, not the end. Models drift, source documents change, APIs fail, costs vary, and user behavior reveals inputs no test set anticipated.
MLOps and LLM operations cover the practices that keep systems useful over time: experiment tracking, model or prompt versioning, deployment automation, monitoring, rollback, and incident response.
- Track request volume, response time, errors, and tool failures.
- Monitor quality metrics and human override rates.
- Record model, prompt, retrieval, and application versions.
- Set budget alerts and rate limits.
- Keep a simple rollback path for risky releases.
A common mistake is logging every prompt and response by default. Instead, define a retention policy and redact or avoid sensitive content. Observability must not become a privacy liability.
⚙️ 12. Optimize Cost, Latency, and Model Choice
Model selection is an engineering decision, not a loyalty test. Different tasks need different trade-offs among reasoning ability, speed, context capacity, reliability, deployment options, and cost.
Use the smallest approach that meets the quality bar. A deterministic extraction rule may beat a model call; a compact model may handle classification; a larger model may be reserved for difficult synthesis or review.
- Define a quality threshold with an evaluation set.
- Test suitable model options and non-model baselines.
- Measure end-to-end latency, not model latency alone.
- Estimate usage volume and failure-retry costs.
- Route complex cases only when the benefit justifies it.
Check official documentation for current capabilities, limits, data-handling terms, and deployment options. These details change often and should be verified before architecture decisions.
🔐 13. Build Privacy, Security, and Responsible Use In
Responsible AI is not an optional policy slide. It is practical engineering that protects users, companies, and your own career.
Classify data before sending it to a model or third-party service. Consider whether it contains personal information, confidential business information, credentials, regulated records, or intellectual property.
- Minimize data sent to the model and redact sensitive fields.
- Authenticate users and enforce document-level permissions.
- Defend against prompt injection in retrieved content and tool outputs.
- Separate untrusted text from system instructions.
- Require human review for high-impact decisions.
- Provide a clear way to report mistakes and correct records.
Never present an AI output as a guaranteed professional, legal, medical, financial, or security decision when human expertise and applicable controls are required. In regulated domains, partner early with security, privacy, legal, and domain owners.
🏗️ 14. Choose a Valuable Portfolio Project
Portfolio projects should demonstrate judgment, not merely API access. Pick a narrow workflow with realistic constraints and show how you evaluated it.
Good project directions include an evidence-backed policy assistant, an invoice-data extraction pipeline with confidence thresholds, a forecasting service with drift alerts, or a support-triage agent that drafts but cannot send messages.
Build an agentic support workflow in seven steps
- Choose a public or synthetic ticket dataset.
- Create categories and a human escalation policy.
- Build a classifier or structured-output triage endpoint.
- Add retrieval for approved support documentation.
- Allow only read-only search and draft creation tools.
- Create at least 30 evaluation cases, including unsafe requests.
- Document architecture, limitations, metrics, and next improvements.
Avoid claiming production scale you do not have. An honest project with thoughtful trade-offs is more credible than a glossy interface with no tests or explanation.
📝 15. Turn Projects Into Evidence of Impact
Hiring managers cannot infer all your skills from a repository. Make your work easy to evaluate with a short case study that explains the problem, users, architecture, decisions, evidence, and limitations.
Problem: Support agents spend time finding policy answers.
Approach: Permission-aware retrieval plus cited answer drafts.
Safety: No direct sending; unsupported questions escalate.
Evaluation: Tested groundedness and citation accuracy on a held-out set.
Result: Report measured outcomes honestly, including known failure modes.
Use impact-oriented resume bullets. Replace “built an AI chatbot” with language that identifies the workflow, technical constraints, evaluation method, and outcome.
- Weak: Built an AI agent using tools.
- Stronger: Built a human-approved ticket-drafting workflow with retrieval, typed tool calls, audit logs, and regression tests for high-risk requests.
🎯 16. Match Skills to the Role You Want
Trying to learn every area at once creates shallow knowledge. Select a primary direction, then build adjacent skills that make you effective on a team.
| Target role | Prioritize | Useful portfolio signal |
|---|---|---|
| Applied AI engineer | Backend, LLM apps, RAG, evaluation, UX | Deployed assistant with analytics and guardrails |
| ML engineer | Data pipelines, training, serving, monitoring | Reproducible prediction pipeline |
| Agentic AI engineer | Tool design, state, evaluation, security | Controlled workflow with approvals and traces |
| Research engineer | Deep learning, experiments, systems, papers | Reproduced and extended a technical method |
| AI product builder | Discovery, prototyping, metrics, integration | Case study tied to a user outcome |
For early-career builders, the applied AI path is often an accessible entry point because it rewards solid software engineering and product judgment. Deeper ML and research skills can become a powerful specialization over time.
🗣️ 17. Prepare for Interviews Beyond Coding Questions
AI interviews often test how you reason through ambiguity. Practice explaining why you chose an approach, how you would measure it, what could go wrong, and when you would reject AI entirely.
Use this answer structure: clarify the user and decision, establish a non-AI baseline, propose an architecture, define evaluation, explain safety controls, and describe operation after launch.
Interview prompt: Design an internal knowledge assistant.

My approach:
1. Identify users, documents, permissions, and high-risk topics.
2. Start with search and a RAG prototype, not autonomous actions.
3. Require citations and abstention when evidence is missing.
4. Evaluate retrieval and answer quality separately.
5. Monitor overrides, feedback, latency, and privacy controls.
Do not bluff model knowledge. A precise answer such as “I would verify that in the provider documentation and test it against our evaluation set” demonstrates mature engineering judgment.
📈 18. Build a 90-Day Skill Plan
A focused plan creates better results than collecting certificates. Allocate regular time to building, reading documentation, testing failures, and writing down what you learned.
- Days 1-30: strengthen Python, APIs, SQL, testing, and a basic LLM feature.
- Days 31-60: build a RAG or classical ML project with a small evaluation set.
- Days 61-90: add deployment, monitoring, safety controls, documentation, and a polished case study.
Each week, ship one visible artifact: a test suite, architecture diagram described in text, evaluation report, demo endpoint, or written postmortem. This creates a trail of evidence that is far more useful than passive study.
✅ 19. Use This Quick-Start Checklist
- Choose one target role and one domain you understand.
- Strengthen Python, APIs, SQL, testing, and version control.
- Learn the lifecycle of at least one classical ML use case.
- Build an LLM workflow with structured output and validation.
- Implement RAG with metadata, permissions, evidence, and abstention.
- Design agents as constrained workflows with approval gates.
- Create an evaluation set before claiming quality.
- Measure latency, errors, cost, and human interventions.
- Apply privacy, security, and least-privilege controls.
- Publish a concise case study that explains trade-offs and impact.
The most valuable AI engineers are the people who transform uncertain model capabilities into safe, measurable, maintainable outcomes for real users. Build that capability one evaluated workflow at a time. 🤖📈🛠️