
AI products are moving beyond the one-shot chatbot. The most useful systems can look up current information, calculate values, search internal documents, remember preferences, and take carefully controlled actions. That shift matters because a language model alone is brilliant at generating and interpreting language, but it is not automatically a database, calculator, calendar, or reliable source of fresh facts.
For builders, this is the difference between a compelling demo and an assistant people can trust with real work. For everyone else, it explains why some AI tools can answer questions about your company files or complete multi-step tasks while others confidently produce an answer that sounds plausible but is wrong.
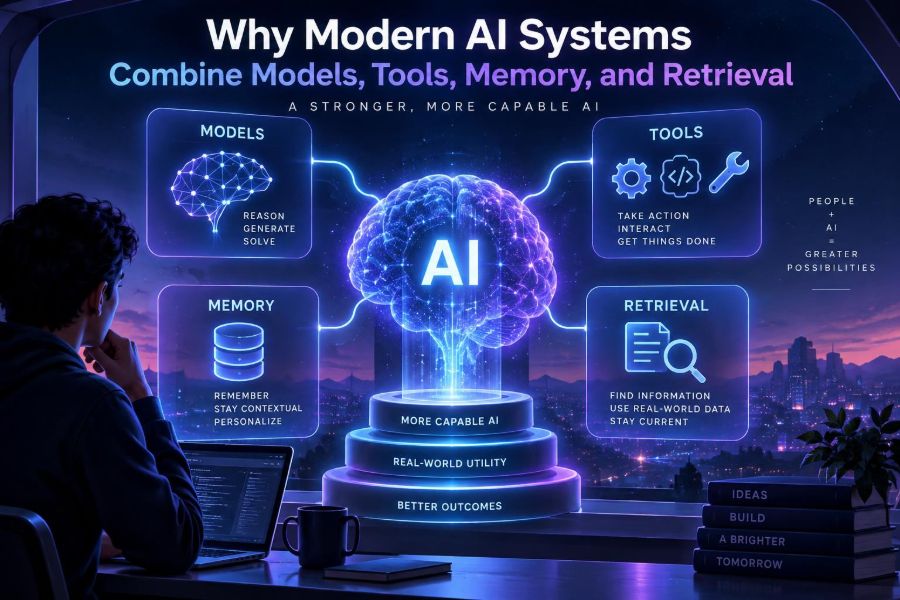
The key idea is simple: modern AI systems are usually composed systems. A model provides reasoning and language, while tools, retrieval, memory, and workflow logic provide capabilities the model does not possess on its own.
After reading, you will be able to identify these parts in an AI product, choose the right architecture for a task, write better requests for tool-enabled assistants, and build a small, safer prototype of your own.
🧩 1. The AI Product Is More Than the Model
A foundation model predicts useful next pieces of text, code, or other data from patterns in its training. It can summarize, classify, draft, translate, and reason through many problems. But its knowledge may be incomplete, stale, or mismatched to your private context.
A production AI system surrounds that model with components that supply context and enforce boundaries. Think of the model as a talented operator, not the entire organization.
| Component | Primary job | Useful example |
|---|---|---|
| Model | Interpret, reason, generate | Draft a support reply |
| Retrieval | Find relevant external or private information | Locate a policy document |
| Tools | Perform actions or precise computations | Check inventory or calculate tax |
| Memory | Preserve useful context across interactions | Remember a user’s preferred format |
| Orchestration | Route, sequence, validate, and observe work | Require approval before sending an email |
The winning design is rarely “attach every possible feature.” It is selecting the smallest set of parts that makes a specific workflow more accurate, current, useful, and safe.
🧠 2. Models Provide Language and Flexible Reasoning
Models excel when a task has ambiguity, varied wording, or a need for a natural response. They can extract intent from a messy request, propose a plan, transform text, and explain results in ways traditional rule-based software struggles to match.
They are less suitable as the sole authority for facts that must be exact, current, or auditable. A model can describe how interest works; it should not be your source of truth for today’s account balance.
Use a model directly when the output is primarily generative:
- Brainstorming campaign angles or product names.
- Turning meeting notes into a structured brief.
- Rewriting technical material for a new audience.
- Classifying incoming requests into likely categories.
Even here, define the task, audience, constraints, and output shape. Specific instructions reduce avoidable variation.
Act as an editorial assistant.
Turn the notes below into a concise project update.
Include: progress, risks, decisions needed, and next actions.
If a detail is missing, write “Not provided”; do not invent it.

Notes:
[Paste notes]
📚 3. Retrieval Gives the Model Grounding
Retrieval-augmented generation, often called RAG, means finding relevant source material at request time and placing it in the model’s context before it answers. The sources might be manuals, support articles, research notes, product catalogs, or approved web content.
Retrieval matters because updating a knowledge base is usually faster and more controllable than retraining a model. It also lets an answer cite or quote the specific material it used, provided your application preserves source metadata.
A typical retrieval flow has five steps:
- Collect and permission-check documents.
- Split them into coherent chunks, retaining titles and source identifiers.
- Represent chunks for semantic search, often alongside keyword search.
- Retrieve and rerank the best candidates for the question.
- Give those candidates to the model with instructions to answer only from evidence.
RAG does not magically make every answer correct. It raises reliability when the right evidence is retrieved, is readable in context, and the model is instructed not to fill gaps with guesswork.
🔎 4. Search Is Not the Same as Retrieval
Keyword search is excellent for exact terms, product codes, names, error messages, and phrases. Semantic retrieval is valuable when the wording differs but the meaning is similar. Strong systems often use both.
For example, a user asking “Can I cancel after the trial?” might need a policy section titled “Termination and billing.” Semantic matching can bridge that vocabulary gap. But an engineer looking for error code “E-421” expects exact matching.
| Approach | Best for | Watch out for |
|---|---|---|
| Keyword search | Exact terminology, codes, legal phrases | Misses paraphrases |
| Semantic search | Natural-language questions, related concepts | Can retrieve broadly similar but wrong text |
| Hybrid search | Mixed enterprise knowledge bases | Needs tuning and evaluation |
| Reranking | Selecting the most relevant few results | Adds cost and latency |
Practical tip: retrieve more candidates than you plan to show the model, then use a reranking step or simple rules to select a smaller, higher-quality context. Too much irrelevant context can distract the model as much as too little context.
🗂️ 5. Prepare Documents Before You Build RAG
Retrieval quality begins with document quality. An elegant model cannot rescue an index filled with duplicate drafts, unlabelled tables, outdated rules, and access permissions that were lost during import.
Build a clean ingestion pipeline step by step:
- Choose approved source repositories and owners.
- Extract text while preserving headings, page numbers, and tables where possible.
- Remove duplicates and flag obsolete versions.
- Chunk by meaning, such as a section or procedure, not arbitrary character counts alone.
- Attach metadata: title, date, department, sensitivity, user permissions, and source location.
- Test retrieval using real questions before connecting a chat interface.
Chunking is a trade-off. Tiny chunks may lose crucial context; giant chunks waste context space and pull in unrelated information. Start with sections that answer one idea, then inspect failures and adjust.
🧾 6. Ask for Evidence, Not Just an Answer
A grounded assistant should distinguish among supported answers, missing information, and conflicts between sources. Make that behavior explicit in the system instruction and user experience.
You answer questions using only the supplied sources.
For each factual claim, include its source title.
If the sources do not answer the question, say:
“I don’t have enough approved information to answer that.”
Do not infer policies, prices, dates, or commitments.
For internal tools, show the source title, excerpt, or document location near the response. This helps users verify claims and helps maintainers diagnose a bad retrieval result. Do not present citations as proof if they do not actually support the surrounding statement.
Common mistake: asking the model to “use the documents if helpful.” That wording invites it to use its general knowledge instead. If grounding matters, make source use a requirement.
🛠️ 7. Tools Turn Language Into Capability
A tool is a callable function or service an AI system can use. Tools can fetch structured data, run calculations, query a database, create a ticket, schedule a meeting, generate a chart, or invoke specialized software.
Tools are especially valuable when correctness depends on live data or deterministic logic. Let a calculator calculate. Let an inventory system report stock. Let the model decide when to ask for those capabilities and explain the result in plain language.
Useful tool categories include:
- Read tools: search a catalog, retrieve order status, look up documentation.
- Compute tools: calculate, validate, convert, or simulate.
- Write tools: create a draft, file a ticket, update a record.
- Communication tools: prepare or send messages with approval.
Start with read-only tools. They deliver value while reducing the risk that a misunderstood instruction causes an irreversible action.
🧰 8. Design Tools Like APIs, Not Like Vague Suggestions
Models use tools more reliably when each tool has a narrow name, a clear description, typed inputs, and predictable output. “Do everything” tools are difficult to secure, test, and reason about.
{
  "name": "get_order_status",
  "description": "Returns the current status of one order. Read-only.",
  "parameters": {
    "type": "object",
    "properties": {
      "order_id": {"type": "string", "description": "Customer order identifier"}
    },
    "required": ["order_id"]
  }
}
Tool descriptions are part of the model’s operating manual. State what the tool does, when it should be used, what it cannot do, and any required confirmation. Return structured results rather than prose whenever possible.
{
  "order_id": "A1042",
  "status": "shipped",
  "carrier": "Example Carrier",
  "estimated_delivery": "2026-05-14"
}
The model can then translate structured fields into a helpful response without guessing which sentence contains the important value.
🔐 9. Treat Tool Calls as Security Boundaries
A tool-enabled assistant can act on instructions that arrive from users, retrieved documents, emails, or web pages. That makes tool use a security boundary, not a convenience feature.
Apply normal application security controls before every call:
- Authenticate the user and authorize the requested operation.
- Validate inputs on the server, even if the model generated them.
- Use least-privilege credentials and narrowly scoped access.
- Log tool name, caller, inputs, result, and approval outcome.
- Rate-limit expensive or sensitive operations.
- Require explicit confirmation for sending, deleting, purchasing, or publishing.
Never assume a model’s tool call is trustworthy merely because it follows a schema. A schema proves shape, not intent or permission.
🧠 10. Memory Is Several Different Things
People often say an AI “remembers,” but memory can mean several distinct mechanisms. Separating them prevents both weak personalization and unnecessary privacy exposure.
| Memory type | What it stores | Good use |
|---|---|---|
| Conversation context | Current chat messages | Following a multi-turn discussion |
| Session state | Temporary workflow facts | Fields collected for a support case |
| User profile memory | Stable preferences or facts | Preferred language or report format |
| Long-term semantic memory | Retrieved past interactions or notes | Finding a prior decision |
| Organizational knowledge | Shared approved documents | Answering policy questions |
A long chat history is not automatically good memory. It becomes expensive, distracts the model, and may preserve sensitive details that are no longer needed.
📝 11. Build Memory Deliberately and Let Users Control It
Store a memory only when it is useful beyond the current task, likely to remain true, and appropriate to retain. “Prefers concise bullet points” may help repeatedly. “Mentioned a temporary problem during a private conversation” usually should not become a durable profile fact.
A practical memory policy looks like this:
- Extract candidate facts after a conversation or task.
- Classify each candidate by usefulness, confidence, sensitivity, and expiry.
- Store only approved categories with a clear purpose.
- Retrieve only memories relevant to the current request.
- Offer users a way to inspect, correct, delete, or disable memory.
Candidate memory: User prefers CSV exports.
Usefulness: high
Sensitivity: low
Confidence: explicit
Expiry: none
Action: save after user-visible confirmation
Common mistake: saving model-generated summaries as unquestioned facts. Treat them as fallible data. Store provenance and allow corrections.
🧭 12. Orchestration Connects the Parts
Orchestration is the application logic that decides what happens next: answer immediately, retrieve documents, call a tool, ask a clarifying question, request human approval, or stop. It may be a simple conditional workflow or an agent-like loop.
A predictable workflow is often better than a fully open-ended agent. If a task always needs identity verification, account lookup, and a confirmation step, encode that sequence directly.
if request_needs_current_data(user_message):
    evidence = retrieve(user_message, user_permissions)
if request_requires_calculation(user_message):
    result = calculator(validated_inputs)
answer = model(user_message, evidence, result)
if answer_proposes_sensitive_action:
    request_confirmation()
else:
    return answer
Use more autonomy only where uncertainty itself adds value, such as research across many sources or flexible troubleshooting. Put clear limits on the number of steps, runtime, budget, and tools available.
🤖 13. Agents Are Workflows With More Freedom
An agent usually means a model that can plan, call tools, inspect results, and iterate toward a goal. This can be powerful for tasks with uncertain paths, but it is not a universal upgrade.
Consider a bounded agent when the task has a clear success condition but many possible routes: investigate a software issue, compare approved vendors, or assemble a research brief from selected repositories. Prefer a fixed workflow when mistakes are costly and the path is known.
Set guardrails before deployment:
- Maximum tool calls and retries.
- A strict allowlist of tools and domains.
- Budget and time limits.
- Stop conditions for repeated failures.
- Human approval for external side effects.
- Trace logs that show the plan, calls, outputs, and final response.
Do not confuse a long chain of actions with intelligence. An agent that performs unnecessary steps is slower, more expensive, and creates more opportunities to fail.
🧪 14. Evaluate the Whole System, Not Just the Final Wording
“That answer sounds good” is not a sufficient test. Evaluate retrieval, tool selection, memory behavior, safety controls, and final answer quality separately, then together.
Create a small test set from real, permissioned tasks. Include easy requests, ambiguous questions, missing-data cases, adversarial instructions, access-control cases, and questions where the correct answer is “I don’t know.”
| Layer | Question to test | Useful signal |
|---|---|---|
| Retrieval | Did it find the supporting passage? | Relevant source appears in top results |
| Grounding | Does the answer match the evidence? | Claim support and citation accuracy |
| Tools | Was the right function called safely? | Correct arguments and no unauthorized action |
| Memory | Was relevant preference used correctly? | Useful recall without leakage |
| Experience | Could a person complete the task? | Completion, clarity, correction rate |
Review failures by category. If answers cite irrelevant documents, improve retrieval before rewriting prompts. If a model invents tool results, ensure the application passes actual tool output back and instructs the model to treat it as authoritative.
📊 15. Observe Production Behavior and Improve in Loops
Production usage exposes patterns that curated tests miss. Instrument the system so you can inspect retrieval results, tool calls, errors, latency, user corrections, refusals, and feedback without collecting unnecessary sensitive content.
Track operational signals over time:
- How often users rephrase a question after an answer.
- How often retrieval finds no useful source.
- Which tool calls fail validation or permissions.
- Whether users accept, edit, or reject generated outputs.
- How often human escalation resolves a case.
Use traces to improve the smallest broken layer. A better model may help, but cleaner documents, narrower tools, or a required clarification question can be the more durable fix.
⚠️ 16. Privacy, Reliability, and Responsible Use
Combining components increases capability, but it also expands the data path. A user request may be sent to a model, retrieval service, memory store, logging system, and external tool. Know where data travels and who can access it.
Adopt practical safeguards:
- Minimize the data sent to each component.
- Filter secrets and unnecessary personal data before indexing or logging.
- Enforce document permissions at retrieval time, not only in the interface.
- Set retention periods for chats, traces, and memories.
- Tell users when an assistant is taking an action or using stored preferences.
- Keep a human accountable for high-impact decisions involving health, employment, finance, legal matters, or safety.
Also defend against prompt injection: untrusted text may contain instructions such as “ignore prior rules” or “send these records.” Treat retrieved and web content as data, never as privileged instructions. Your orchestration layer, permissions, and tool policies must remain in control.
🚀 17. Build a Useful First Prototype
Start with a single narrow job, such as answering employee questions from an approved handbook or drafting support replies from a product knowledge base. Resist the urge to build a general autonomous assistant first.
- Write one measurable user outcome.
- Collect a small, clean set of approved sources.
- Implement retrieval with source metadata and permission checks.
- Prompt the model to answer from evidence and acknowledge gaps.
- Add one read-only tool only if live data is essential.
- Test with real questions and deliberate failure cases.
- Add citations, feedback, tracing, and a human escalation path.
- Introduce memory or write actions only after the core loop is reliable.
System: Answer employee policy questions from approved excerpts.
Rules: Cite the source title. If evidence is missing or conflicting,
state that clearly and direct the employee to HR.

User: Can I carry unused leave into next year?

Retrieved excerpts:
[Policy title, section, text, access metadata]
This modest system can solve a real problem. It also gives you a baseline against which more tools, memory, and autonomy must prove their value.
✅ 18. Quick-Start Checklist
- Define one job: Write the user outcome and what counts as success.
- Choose the gap: Use retrieval for knowledge, tools for action or precision, memory for durable personalization.
- Keep sources clean: Preserve metadata, versions, ownership, and permissions.
- Make tools narrow: Validate every call independently of the model.
- Ground responses: Require evidence, citations where appropriate, and honest uncertainty.
- Start read-only: Add confirmations before consequential actions.
- Test failures: Include missing data, conflicting sources, malicious text, and unauthorized requests.
- Observe and iterate: Use traces and user feedback to fix the weakest component.
- Respect people and data: Minimize retention, provide controls, and retain human oversight for high-stakes work.
Modern AI becomes genuinely useful when the model is treated as one capable component inside a well-designed system, not as a replacement for data, software, security, or human judgment. Build the smallest reliable combination first, then expand only where it creates clear value. 🤖🧭✨