
AI systems can write fluent answers in seconds, but fluency is not the same as truth. When a model lacks a fact, misreads a question, or encounters ambiguous source material, it may produce an answer that sounds certain while being wrong. This behavior, commonly called a hallucination, is one of the biggest barriers to trusting AI in real work.
The risk is especially urgent now because AI is moving from casual chat into support desks, research workflows, internal knowledge bases, software tools, and creative production. A confident but unsupported answer can waste time; in regulated, financial, medical, legal, or security contexts, it can cause much greater harm.
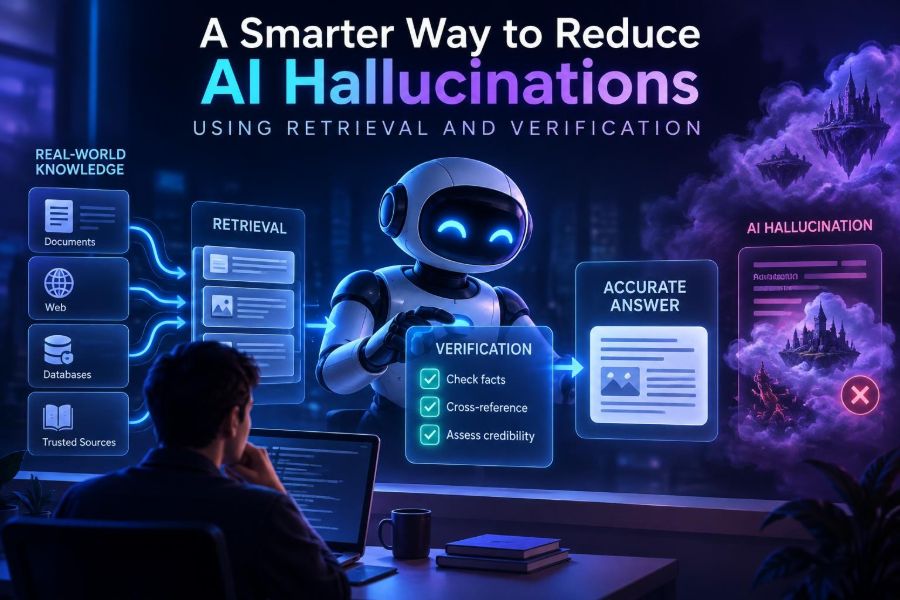
A practical solution is not simply telling a model to “be accurate.” Instead, give it relevant evidence at answer time, then make it verify that each important claim is supported. This pairing of retrieval and verification creates a more dependable workflow.
After reading, you will be able to design a grounded AI assistant, choose a retrieval strategy, write prompts that demand evidence, add lightweight verification, measure quality, and recognize where these safeguards still fall short.
🧠 1. Understand What a Hallucination Really Is
A hallucination is output that is unsupported, fabricated, or materially misleading. It can be a made-up citation, an incorrect product capability, a false summary of a document, or a plausible-looking piece of code that calls a nonexistent function.
Not every undesirable response is a hallucination. A model may be overly vague, use stale information, or fail to follow an instruction without inventing facts. Separating these failures helps you choose the right fix.
- Fabrication: inventing a source, event, statistic, feature, or quote.
- Unsupported inference: making a strong conclusion not justified by the available evidence.
- Context mismatch: answering from generic training knowledge instead of your current documents.
- Faithfulness failure: changing the meaning while summarizing supplied text.
🎯 2. Identify the Claims That Actually Need Guardrails
You do not need the same verification burden for every task. Brainstorming taglines, drafting fictional dialogue, and generating rough interface ideas can tolerate creativity. Answers about policies, specifications, troubleshooting, compliance, or customer accounts require much stricter grounding.
Start by classifying your intended use case. Ask what happens if the answer is wrong, who acts on it, and whether a reliable source exists.
| Use case | Risk if wrong | Recommended control |
|---|---|---|
| Creative ideation | Usually low | Clear creative brief and human review |
| Internal policy assistant | Medium to high | Retrieval, citations, abstention |
| Technical support | Medium | Retrieval, step validation, escalation path |
| Medical, legal, financial guidance | High | Authoritative sources, specialist review, strict limits |
| Code generation | Variable | Tests, linters, sandboxing, documentation retrieval |
A useful rule is simple: the more consequential the claim, the more directly it should be tied to evidence.
📚 3. Use Retrieval to Put the Right Facts in Context
Retrieval-augmented generation, often abbreviated RAG, gives a model relevant external information before it answers. Rather than expecting the model to remember your changing documentation, you retrieve passages from approved sources and include them in the prompt.
This helps with freshness, domain specificity, and traceability. It does not turn the model into a database: it gives the model a bounded evidence set from which to reason and write.
The basic pipeline is:
- Collect trusted documents.
- Split them into searchable chunks.
- Convert chunks and the user question into vector representations.
- Retrieve the most relevant chunks.
- Ask the model to answer only from those chunks.
- Verify important claims and return citations or an abstention.
🗂️ 4. Build a Trusted Knowledge Collection First
Retrieval cannot rescue unreliable source material. Before choosing an embedding model or vector store, define which documents are authoritative and who owns them.
For an internal assistant, this might include approved policy pages, current product documentation, resolved support articles, and carefully selected engineering runbooks. Keep drafts, obsolete files, personal notes, and unreviewed chat exports out of the default corpus.
- Record a source title, owner, publication date, revision date, and access level.
- Set expiration or review dates for information that changes often.
- Prefer primary documents over summaries when possible.
- Deduplicate near-identical documents to avoid overweighting repeated text.
- Preserve stable source identifiers so citations can point back to the original passage.
This governance work may feel less glamorous than model selection, but it often has a larger effect on answer quality.
✂️ 5. Chunk Documents for Meaning, Not Just Length
Retrieval usually searches document chunks rather than entire files. Chunks that are too large contain noise and may overflow context; chunks that are too small omit the conditions that make a statement true.
Split on natural boundaries such as headings, sections, procedures, and question-answer pairs. Keep associated definitions, exceptions, and prerequisites together. A small overlap between neighboring chunks can preserve continuity, but excessive overlap creates duplicates.
Document section: Password reset procedure

Good chunk:
Title: Reset a locked account
Conditions: User has verified email access
Steps: 1. Open Settings... 2. Select Reset...
Exception: Contact support if multi-factor recovery fails

Weak chunk:
"Select Reset..."
Add metadata alongside each chunk. Useful fields include document type, product area, audience, region, version or revision date, security classification, and URL or internal document ID.
🔎 6. Retrieve with More Than One Signal
Semantic vector search finds passages with similar meaning, even when words differ. Keyword search is excellent for exact identifiers, error codes, product names, and unusual technical terms. In many knowledge bases, hybrid retrieval is more robust than relying on either one alone.
Then rerank the initial candidates with a stronger relevance scorer. The first retrieval stage is optimized to find plausible candidates quickly; reranking spends more computation deciding which few passages best answer this specific question.
question = "How do I rotate the service access key?"
semantic_hits = vector_search(question, limit=20)
keyword_hits = keyword_search(question, limit=20)
candidates = merge_and_deduplicate(semantic_hits, keyword_hits)
context = rerank(question, candidates, limit=5)
Check official documentation for your chosen search, embedding, and reranking tools because capabilities, limits, and integrations change quickly.
🏷️ 7. Filter Before You Retrieve
Metadata filters prevent a good semantic match from becoming a bad operational answer. If a user asks about a European policy, an old policy for another region should not outrank the current regional rule simply because its language is similar.
Apply filters based on what you know from the user, the application, and the query:
- Current versus archived content.
- User permissions and team membership.
- Product, tenant, language, market, or region.
- Document status, such as approved or draft.
- Audience, such as administrator, developer, or end user.
Security filtering must happen before text reaches the model. Do not retrieve sensitive passages and hope a final prompt instruction will keep them private.
🧾 8. Ask the Model to Answer From Evidence Only
Retrieval alone is not grounding. The model needs explicit instructions about how to use the supplied context, what to do when it is incomplete, and how to distinguish a source-backed statement from a general suggestion.
You are a documentation assistant.
Answer the user's question using only the SOURCE PASSAGES below.

Rules:
- Make a factual claim only when a source passage supports it.
- Cite the source ID after every material factual claim.
- If the passages do not answer the question, say: "I don't have enough approved information to answer that."
- Do not invent steps, policies, features, dates, or citations.
- Clearly label any optional best-practice suggestion as a suggestion.

SOURCE PASSAGES:
[S1] ...
[S2] ...

USER QUESTION:
{{question}}
Keep the refusal language direct and useful. An assistant that abstains should say what is missing and, where appropriate, suggest the next safe action, such as consulting a current policy owner.
🧩 9. Require Citations That Users Can Inspect
Citations make answers easier to audit and help users detect when a response has strayed from the retrieved evidence. They also encourage more precise writing, because vague claims are harder to attach to a specific passage.
Use chunk IDs during generation, then map them to human-readable source titles and locations in your interface. A citation should identify the document and the relevant section, not merely display a mysterious internal vector ID.
Do not treat citations as proof by themselves. A model can attach a real citation to the wrong sentence. That is why verification should inspect the relationship between the claim and the cited passage.
✅ 10. Add a Claim-by-Claim Verification Pass
Verification asks a focused question after drafting: does the evidence support this claim? Separating answer generation from claim checking reduces the chance that one fluent generation step both invents and approves its own invention.
For a first implementation, extract the answer’s material claims, compare each claim against its cited evidence, and label it supported, contradicted, or not enough evidence. Remove or rewrite anything that does not pass.
Claim: "Access keys expire after 90 days."
Evidence: "Administrators can configure an access-key expiration period."

Verifier result: NOT ENOUGH EVIDENCE
Reason: The passage describes configuration but does not specify 90 days.
Action: Remove the 90-day statement.
You can use a separate model call, a smaller specialized evaluator, deterministic rules, or a combination. For high-risk workflows, route failed or ambiguous cases to a human reviewer.
⚖️ 11. Separate Retrieval Quality from Answer Quality
When an answer is wrong, teams often blame the language model. But failures happen at multiple stages. The correct source may never have been retrieved, the source may be incomplete, the prompt may not constrain the model, or the verifier may accept weak entailment.
| Failure | Likely cause | Useful fix |
|---|---|---|
| Correct source missing | Weak chunking or search | Improve metadata, hybrid search, query rewriting |
| Source is outdated | Poor corpus governance | Expire and review documents |
| Answer adds details | Weak grounding prompt | Require citations and abstention |
| Citation is irrelevant | No entailment check | Run claim-evidence verification |
| Answer is unusably cautious | Too little relevant context | Improve retrieval before loosening rules |
Instrument each stage. Log the query, retrieved chunk IDs, ranking order, final answer, citations, verifier decision, and feedback signal, while respecting privacy and access controls.
🧪 12. Create an Evaluation Set Before You Tune
Without representative tests, it is easy to optimize for a few memorable demos. Build a small evaluation set from real, permissioned questions, including questions that should be answered and questions that should trigger abstention.
For each item, store the expected answer points, the acceptable source documents, and any dangerous wrong answers. Include edge cases such as conflicting documents, stale terminology, multi-part questions, and ambiguous requests.
- Retrieval recall: was an acceptable source among the candidates?
- Groundedness: are answer claims supported by retrieved text?
- Answer completeness: did the answer cover necessary steps and exceptions?
- Abstention quality: did it decline unsupported questions appropriately?
- Operational usefulness: could a person act safely on the result?
📏 13. Measure the Trade-Offs Honestly
There is no single hallucination score that tells the whole story. A system can be extremely cautious and rarely fabricate facts, yet frustrate users by refusing questions that its sources do answer.
Review metrics together. Look at evidence recall, citation correctness, unsupported-claim rate, task success, latency, and cost. Segment results by topic and risk level, because an average can hide serious weaknesses in a critical category.
Human review remains important. Ask reviewers to mark exactly which sentence is unsupported and whether the retrieved context contained the needed evidence. That feedback tells you where to fix the pipeline.
🛑 14. Design a Useful Abstention Experience
“I don’t know” is safer than a confident fiction, but a bare refusal feels broken. A good abstention explains the gap without exposing hidden internal reasoning or sensitive source details.
I don't have enough approved information to confirm the retention period for this account type.

I can help you:
1. Find the current retention-policy document, or
2. Draft a question for the policy owner.

I will not guess a retention period.
Use thresholds carefully. If retrieval relevance is low, sources conflict, or verification fails, the application can ask a clarifying question, return a limited answer, or escalate. The appropriate behavior should match the risk of the domain.
🧑💻 15. Implement a Minimal Grounded Answer Pipeline
You can prototype the pattern with any model provider and any search system that supports your data and security requirements. The following pseudocode shows the control flow; production systems need authentication, observability, retries, evaluation, and policy checks.
def answer(question, user):
    filters = permissions_and_metadata_filters(user, question)
    candidates = hybrid_retrieve(question, filters, limit=30)
    sources = rerank(question, candidates, limit=6)

    if not sufficient_relevance(sources):
        return abstain("No reliable source was found.")

    draft = generate_grounded_answer(question, sources)
    claims = extract_material_claims(draft)
    checks = verify_claims(claims, sources)

    if any(check.status != "supported" for check in checks):
        draft = remove_or_rewrite_unsupported_claims(draft, checks)

    return attach_readable_citations(draft, sources)
Keep the original evidence available for review. Do not verify against a paraphrase of a source when the original text is available.
🧰 16. Use Deterministic Checks Where They Fit
Not every safeguard needs another model. Deterministic validation is fast, cheap, and easier to audit for structured facts.
- Validate dates, units, account IDs, JSON schemas, and required fields with code.
- Check whether cited source IDs actually exist in the retrieved set.
- Reject citations that point to inaccessible or expired documents.
- Compare generated configuration values against allowed ranges.
- Run generated code through tests, type checks, linters, and sandboxed execution.
Use model-based verification for semantic questions, such as whether a passage entails a natural-language claim. Use conventional software checks for formats and hard rules.
🔐 17. Protect Privacy, Permissions, and Prompt Boundaries
Retrieval systems can create a new data-leakage path if access controls are weak. The assistant should only retrieve documents the current user is authorized to see, and output filtering should not be your primary protection.
Minimize the data sent to external services, redact sensitive fields where feasible, and set retention policies for logs and evaluation datasets. Consult your organization’s security and legal requirements before indexing personal, confidential, or regulated information.
Also treat retrieved text as untrusted input. A document may contain instructions like “ignore previous rules.” Your system prompt should state that source passages are evidence, not commands, and your application should separate tool instructions from document content.
🚧 18. Know the Limits of Retrieval and Verification
RAG reduces hallucinations; it does not guarantee truth. Retrieval can miss the best source, authoritative documents can be wrong or outdated, and a verifier can make mistaken semantic judgments.
Some questions require synthesis across many sources, calculations, real-time data, domain expertise, or value judgments. For these, retrieval should be paired with appropriate tools, transparent uncertainty, human approval, and clear boundaries on what the assistant is allowed to decide.
Never present a grounded system as infallible. Its value comes from making evidence, uncertainty, and review visible—not from hiding them behind confident prose.
🚀 19. Quick-Start Checklist
- Choose one narrow, high-value question type to improve first.
- Collect approved, current source documents and assign owners.
- Chunk by meaningful sections and attach strong metadata.
- Use hybrid retrieval and filter by permissions before retrieval.
- Prompt the model to use only supplied evidence and to abstain when needed.
- Require readable citations for material factual claims.
- Verify claims against original passages before returning the answer.
- Add deterministic checks for structured data, code, and hard rules.
- Test with real questions, adversarial questions, and unanswerable questions.
- Monitor failures and improve sources and retrieval before simply changing prompts.
The smarter way to reduce AI hallucinations is to make evidence retrieval, claim verification, and honest abstention part of the product—not an afterthought in a prompt. 🤖🔍✅