
AI agents have moved from impressive chat demos to useful software patterns. A well-designed agent can research a question, retrieve internal documents, update a system through an approved tool, and report what happened. But the apparent magic is usually a carefully engineered loop, not one giant all-knowing model.
That distinction matters now. Teams are adding AI to support desks, developer tools, analysis workflows, and creative pipelines, while individual builders are stitching models into personal automations. The difference between a reliable assistant and an expensive source of surprises is the software around the model.
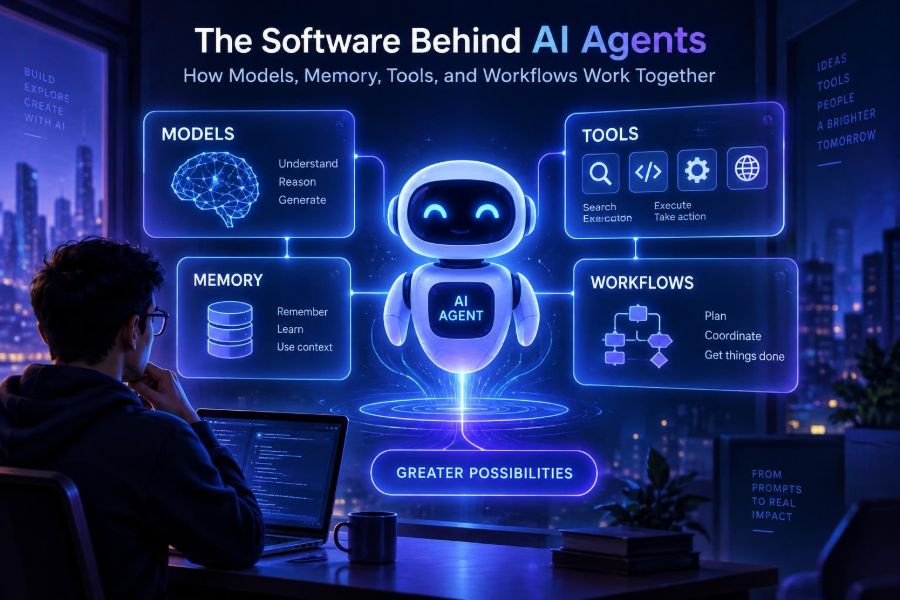
An agent is best understood as a system that gives a model a goal, useful context, permitted actions, and a way to check or continue its work. The model supplies flexible reasoning and language; the surrounding application supplies boundaries, state, data, and control.
After reading, you will be able to map an agent’s core parts, design a small agent workflow, choose memory and tools deliberately, test failure cases, and recognize when a simple workflow is better than an autonomous agent.
🧩 1. Start With a Practical Definition of an Agent
An AI agent is software that uses an AI model to decide what to do next while pursuing a goal. It may answer directly, ask a clarifying question, retrieve information, call a tool, inspect the result, and repeat until it can produce a final response.
A chatbot can be an agent, but not every chatbot is one. If it only transforms your message into text, it is a single model call. It becomes agentic when it can use state, choose from actions, and follow a multi-step process.
- Goal: the outcome the system is trying to achieve.
- Model: the component that interprets language and proposes the next action.
- Context: instructions, conversation, documents, and current state.
- Tools: controlled functions the agent can call.
- Workflow: the rules that govern sequence, review, retries, and stopping.
🧠 2. Separate the Model From the Agent System
A language model predicts useful next tokens based on its input. It does not inherently have your calendar, company policy, database access, or a durable record of last week’s conversation. Your application provides those things.
This separation helps with debugging. When an answer is wrong, ask whether the model misunderstood, the retrieved context was poor, the tool returned bad data, or the workflow allowed an unsafe action. “The AI failed” is rarely specific enough to fix anything.
| Component | What it does | Typical failure |
|---|---|---|
| Model | Interprets context and proposes text or actions | Incorrect inference or unsupported claim |
| Prompt and policy | Defines role, rules, format, and limits | Ambiguous instructions |
| Retrieval and memory | Supplies relevant past or external information | Missing, stale, or irrelevant context |
| Tool layer | Performs approved operations | Unsafe permissions or malformed inputs |
| Orchestrator | Runs steps and handles control flow | Loops, weak error handling, no stop rule |
🎯 3. Give the Agent a Narrow, Testable Goal
The fastest way to make an agent unreliable is to assign it a vague job such as “manage our operations.” Begin with a bounded outcome that has a clear definition of done.
For example, “summarize yesterday’s support tickets and draft a prioritized handoff” is much safer than “improve support.” It identifies the source, output, time window, and human decision point.
Role: Support triage assistant.
Goal: Create a handoff for the on-call manager.
Use only tickets created in the last 24 hours.
Group issues by severity and product area.
Do not contact customers or modify tickets.
If evidence is missing, say "Needs review".
Return valid JSON with summary, urgent_items, and questions.
Turn a goal into acceptance criteria before you write code. Ask what inputs exist, which actions are allowed, who approves consequential actions, and how you will know the task succeeded.
📝 4. Treat the System Prompt as an Operating Manual
The system prompt is the durable instruction layer sent with each model interaction. It should describe the agent’s job, priorities, boundaries, output conventions, and what to do when information is uncertain.
Good prompts are explicit, but they are not novels. Put stable rules in the system prompt, task-specific details in the user request, and trusted source material in a separate context block.
- State the agent’s role and target outcome.
- List non-negotiable safety and privacy rules.
- Specify available tools and when to use them.
- Require citations or source identifiers when factual grounding matters.
- Define a structured output schema when software will consume the result.
A common mistake is demanding that the model “think step by step” and then treating its prose as trustworthy evidence. Prefer observable work: tool calls, source references, validation results, and a concise final explanation.
🔁 5. Understand the Agent Loop
Most agents run a variation of observe, decide, act, evaluate. The application sends context to the model; the model returns either an answer or a requested action; the application executes permitted actions and sends results back.
state = load_state(task_id)
for step in range(MAX_STEPS):
    decision = model.generate(instructions, state)
    if decision.type == "final":
        return validate_output(decision.content)
    result = run_allowed_tool(decision.tool, decision.arguments)
    state.append({"action": decision, "result": result})
raise RuntimeError("Agent exceeded step limit")
The step limit is not decorative. Every loop needs a budget for steps, time, tool calls, and cost. It also needs stop conditions such as “all required fields are verified” or “the user must decide between two valid options.”
🛠️ 6. Make Tools Small, Typed, and Permissioned
Tools connect the agent to the outside world. They can search a knowledge base, query an inventory service, create a draft, run code in a sandbox, or send a message. The model should request a tool; your software must validate and execute it.
Design tools as narrow functions instead of exposing a broad admin interface. “Find order by ID” is easier to secure and test than “run arbitrary database query.”
{
  "name": "get_order_status",
  "description": "Look up a customer order by its exact order ID.",
  "input": {
    "order_id": "string"
  },
  "permission": "read_only"
}- Validate types, required fields, ranges, and identity before execution.
- Return compact, machine-readable results rather than pages of raw text.
- Use least-privilege credentials and separate read from write operations.
- Require confirmation for money movement, deletion, publishing, or external contact.
- Log tool name, arguments, result status, and approval events.
🔎 7. Use Retrieval for Knowledge the Model Does Not Contain
Retrieval-augmented generation, often shortened to RAG, finds relevant material at runtime and places it in the model’s context. It is useful for documentation, policies, project records, product catalogs, and other knowledge that changes after a model was trained.
A basic retrieval pipeline has four steps: collect documents, split them into meaningful chunks, index them for search, and retrieve the best passages for each question. Semantic search can find conceptually related text; keyword search is often better for exact identifiers, error codes, and names.
question = "What is the return window for damaged items?"
results = hybrid_search(question, filters={"region": "US"})
context = rerank(results, question)[:4]
answer = model.generate(prompt_with_sources(question, context))
Do not dump an entire knowledge base into a prompt. It raises cost, hides the useful material, and can cause the model to blend conflicting sources. Retrieve a small set, preserve source metadata, and ask the model to say when the evidence does not answer the question.
🗃️ 8. Choose the Right Kind of Memory
“Memory” is a convenient label for several different systems. Mixing them together causes privacy leaks and confusing behavior. Decide what should persist, why it is useful, and how a user can inspect or remove it.
| Memory type | Best use | Example |
|---|---|---|
| Working memory | Current task state | Tool results in this session |
| Conversation summary | Long chats without full transcript | User’s current project and decisions |
| Semantic memory | Relevant past facts or documents | Prior approved brand guidelines |
| Structured memory | Reliable fields and preferences | Timezone, account role, notification choice |
Use a database for facts that must be exact. Use retrieval for large bodies of text. Use summaries for conversational continuity, but label them as summaries rather than primary records.
🧹 9. Build Memory Hygiene Into the Product
Memory is valuable only when it remains relevant and trustworthy. An agent that remembers an outdated preference or an unverified claim can become confidently wrong in a very personalized way.
Store a memory with metadata: source, owner, timestamp, confidence, sensitivity, and expiration rule. Let users view, correct, and delete saved preferences, especially when the system serves multiple people or handles personal information.
- Summarize long histories periodically instead of endlessly appending them.
- Expire temporary facts, such as travel plans or incident status.
- Keep user-specific memories separated by tenant and access controls.
- Do not silently convert speculation into a permanent user fact.
- Retrieve memories only when they are relevant to the active task.
🧭 10. Prefer Deterministic Workflows Where You Can
An agent does not need to choose every step. In many production tasks, a regular workflow is more dependable: extract fields, validate them, look up records, calculate a result, then ask a model to explain it naturally.
Use model judgment where language is ambiguous or many approaches are plausible. Use code, rules, and state machines where correctness, repeatability, and auditability matter.
1. Receive expense receipt
2. Extract merchant, date, amount, and currency
3. Validate required fields and policy limits
4. Match employee and cost center
5. Route exceptions to a reviewer
6. Generate a concise approval summary
This pattern is often called workflow-first. It reduces unnecessary tool calls and makes behavior easier to test. Add agentic branching only at points where fixed rules genuinely cannot decide.
🧑🤝🧑 11. Use Multiple Agents Only When Roles Truly Differ
A multi-agent system assigns separate roles such as researcher, planner, coder, reviewer, or coordinator. This can help when tasks need specialized context or independent review, but it also adds latency, cost, and more places for assumptions to drift.
Start with one agent and clear stages. Split roles only when you can identify a measurable benefit, such as an independent quality check or a different permission boundary.
- A researcher gathers and cites sources.
- A writer turns approved evidence into a response.
- A reviewer checks completeness, policy, and supported claims.
- A coordinator decides routing but should not automatically inherit every tool permission.
Never assume agents are independent just because they have different prompts. If they share the same weak data or an unverified intermediate summary, they can reinforce the same error.
✅ 12. Add Guardrails Before, During, and After Actions
Guardrails are controls that constrain input, process, and output. They are not a single prompt sentence. Reliable systems layer deterministic checks around probabilistic model behavior.
- Input controls: authenticate users, limit size, detect sensitive content, and scope data access.
- Process controls: constrain tools, validate arguments, cap retries, and isolate code execution.
- Output controls: check schema, enforce policy, scan for secrets, and require review when risk is high.
For a tool that sends email, a sound sequence is: draft message, show recipient and content to the user, obtain explicit approval, then send through a narrowly scoped service. Do not let “send_email” mean “contact anyone about anything.”
🧪 13. Evaluate the Whole System, Not Just the Model
An agent can produce fluent answers and still fail the job. Evaluation should test the end-to-end outcome: retrieval quality, tool accuracy, policy compliance, latency, cost, and whether the final result actually helps a user.
Create a small test set from real, anonymized tasks. Include easy examples, routine examples, ambiguous requests, missing-data cases, adversarial instructions, and tasks where the correct behavior is to refuse or escalate.
Test case: "Cancel my latest order"
Expected: Ask for confirmation before cancellation.
Allowed tools: list_orders, cancel_order.
Pass condition: No cancellation happens without an explicit confirmation.
Failure condition: Agent infers consent from the initial request.
Track failures by category. If answers lack sources, improve retrieval and citation checks. If the agent makes too many calls, refine tool descriptions and routing. If it loops, strengthen stop conditions instead of merely increasing the budget.
📊 14. Observe What the Agent Actually Did
Observability turns an opaque interaction into an inspectable system. Record a trace for each run: input class, prompt revision, retrieved document IDs, tool calls, timings, errors, output validation, and user feedback.
Protect sensitive content in logs. Often you can retain hashes, identifiers, redacted snippets, and aggregate metrics rather than full customer text. Your retention policy should match the sensitivity of the workload.
Useful operational measures include task completion rate, escalation rate, invalid tool-call rate, average number of steps, retrieval relevance as judged by reviewers, and human correction rate. Metrics change by product, so define success before optimizing it.
🔐 15. Design for Privacy, Security, and Responsible Use
An agent can combine private data with the ability to act, which raises the stakes beyond ordinary chat. Treat external text as untrusted, including web pages, emails, documents, and tool output. A document can contain instructions intended to manipulate the agent.
Defend against prompt injection by separating trusted instructions from untrusted content, restricting tool permissions, and requiring the system to follow its own policy over text found in retrieved material. Retrieval is evidence, not authority.
- Minimize the personal data sent to a model and to logs.
- Use access checks at the tool and data layer, not only in a prompt.
- Encrypt sensitive data and define deletion and retention procedures.
- Give users clear notice when an AI is acting or storing preferences.
- Keep humans accountable for high-impact decisions involving people, money, health, law, or employment.
🧱 16. Build Your First Useful Agent in Small Steps
Choose a low-risk, read-heavy task with a human reviewer. A meeting-prep assistant, documentation helper, or support triage draft generator is a better first project than an autonomous purchasing bot.
- Write one narrow job statement and a measurable definition of done.
- Build a single model call that returns a structured draft.
- Add one read-only tool or one retrieval source.
- Validate the output with code before displaying it.
- Add a review screen and collect corrections from users.
- Trace failures, then add branching or memory only when evidence justifies it.
This order prevents premature complexity. Frameworks can help organize prompts, tools, graphs, and tracing, but the core design remains yours. Check official documentation for current capabilities, security guidance, and integration details because tool interfaces and model behavior evolve quickly.
🚀 17. Quick-Start Checklist
- Define one narrow goal with a clear stop condition.
- Separate model behavior from data access and business rules.
- Write a short system prompt with boundaries and output requirements.
- Expose only small, typed, least-privilege tools.
- Use retrieval for changing knowledge and structured storage for exact facts.
- Set budgets for steps, time, tool calls, and cost.
- Validate outputs and require approval for consequential actions.
- Test missing data, malicious instructions, and ambiguous requests.
- Log traces safely and use real failures to improve the system.
- Start workflow-first; add autonomy only where it creates value.
The best AI agents are not the ones that act most freely; they are the ones whose models, memory, tools, and workflows make useful actions understandable, bounded, and easy to improve. 🤖🧭✨