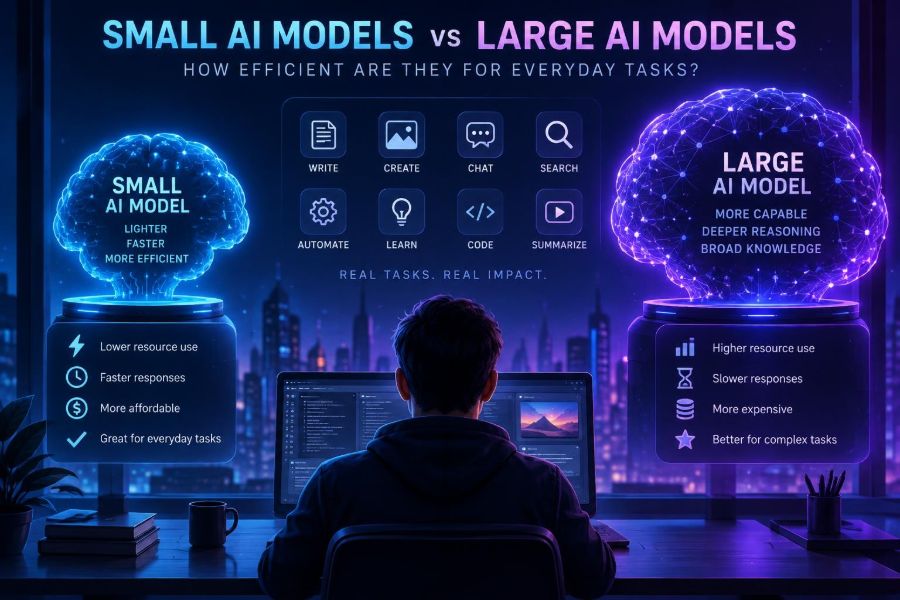

AI teams are no longer asking only, “What is the biggest model we can use?” They are asking a more practical question: “What is the smallest model that can reliably do this job?” That shift matters because everyday AI work is often repetitive, narrow, latency-sensitive, private, or expensive at scale.
A large model can be remarkably capable, especially when a task is ambiguous or needs broad knowledge. But a compact model can be faster, cheaper to run, easier to deploy locally, and surprisingly effective when the workflow is designed well.
The right choice is not a contest with one winner. It is a matching problem: model capability, task difficulty, acceptable error rate, context length, privacy needs, and operating cost all have to fit together.
After reading, you will be able to identify tasks that fit small models, test them fairly against larger models, build a simple routing strategy, improve results with prompts and retrieval, and avoid common deployment mistakes.
🧭 1. Start With What “Efficient” Actually Means
Efficiency is not just speed. A model is efficient when it delivers acceptable outcomes using the least time, money, energy, memory, and human review for a specific task.
That definition changes by project. A creator drafting ten social captions may care mostly about quality. A support team processing thousands of ticket classifications may care much more about consistency, response time, and cost per request.
- Latency: how quickly the first useful output arrives and how long the full response takes.
- Throughput: how many requests or tokens a system handles over time.
- Cost: spending on hosted inference or hardware and operations for self-hosting.
- Memory footprint: the RAM or accelerator memory needed to load and run the model.
- Quality: correctness, usefulness, tone, format compliance, and safety.
- Operational effort: monitoring, deployment, fallback handling, and review work.
Do not label a model “efficient” until you define the job and the minimum acceptable result. A tiny model that creates many wrong answers is inefficient once correction time is included.
🧠 2. Understand the Difference Between Small and Large Models
Small language models generally have fewer parameters and lower inference requirements than large language models. Parameter count is not the whole story, but it is a useful shorthand for capacity and resource needs.
Small models are often optimized for compact deployment, structured output, instruction following, or a limited set of tasks. Large models tend to offer stronger general reasoning, wider world knowledge, better handling of unusual requests, and more resilience when instructions are incomplete.
| Characteristic | Small model tendency | Large model tendency |
|---|---|---|
| Response speed | Often faster, especially locally | Can be slower for long or complex outputs |
| Running cost | Usually lower | Usually higher |
| Generalization | Best on familiar, constrained patterns | Better on novel or mixed tasks |
| Deployment | Can fit edge devices or modest servers | Often needs a managed service or substantial hardware |
| Prompt tolerance | Benefits from explicit instructions | Often handles ambiguity more gracefully |
| Failure handling | May fail abruptly outside its scope | May still be wrong, but can provide richer recovery |
Neither category guarantees quality. Training data, architecture, quantization, tuning, context handling, and the surrounding application design can matter as much as size.
📋 3. Classify Your Everyday Task Before Choosing a Model
Most model-selection mistakes begin with vague requirements such as “summarize documents” or “build an assistant.” Split the broad goal into smaller, observable tasks.
For example, an inbox assistant may need to detect language, classify intent, extract order IDs, summarize a message, draft a reply, and decide whether to escalate. These components do not all require the same level of intelligence.
- Write down the exact input and desired output.
- Mark whether the output must be factual, creative, structured, or safety-sensitive.
- Estimate input length and expected response length.
- List edge cases that would cause harm or extra work.
- Define who checks the result and what happens after a failure.
A narrow task with a stable output format is an excellent small-model candidate. A task requiring open-ended judgment across many domains is more likely to benefit from a larger model.
⚡ 4. Identify Tasks Where Small Models Usually Shine
Small models are particularly effective when the answer is short, the pattern repeats, the allowed output is constrained, and examples are plentiful. These are common high-volume business and product workflows.
- Sentiment, topic, urgency, and intent classification.
- Named-entity extraction, such as pulling dates, products, invoice numbers, or locations.
- Short summaries of consistent document types.
- Language detection, rewriting, grammar cleanup, and tone normalization.
- Structured data extraction into a schema.
- FAQ routing and retrieval-answer synthesis from approved documents.
- Autocomplete, code formatting hints, and boilerplate generation.
- Content moderation triage, with careful escalation rules.
The key word is usually. If a legal, medical, financial, or security decision depends on the result, the workflow needs stronger controls regardless of model size.
🧩 5. Know When a Large Model Is Worth It
Use a larger model when the task contains uncertainty that cannot be removed with better instructions, retrieval, or decomposition. Larger models are often worth their extra resources when a wrong answer is costly or when the task demands flexible synthesis.
Typical examples include multi-step planning, nuanced analysis of long and inconsistent materials, difficult code debugging, cross-domain research synthesis, complex negotiations in natural language, and creative work where unexpected ideas are valuable.
A large model can also be the right choice for the first version of a product. It lets you learn what users actually ask for before investing in task-specific optimization.
Use a larger model when the request needs any of these:
- interpretation of conflicting evidence
- multi-step reasoning with checks
- broad domain knowledge
- long-context synthesis
- high-quality creative variation
- recovery from unclear instructions
Even then, do not send every request to the largest available model by default. A routing layer can reserve expensive capacity for requests that genuinely need it.
🧪 6. Build a Realistic Evaluation Set
Public benchmarks can be useful signals, but they rarely represent your data, wording, users, and failure costs. Build a small evaluation set from the work your system will actually receive.
Collect examples with permission and remove sensitive information where needed. Include normal requests, confusing requests, long inputs, adversarial inputs, multilingual inputs, and cases that previously required human intervention.
- Gather 50 to 200 representative examples to begin.
- Create a reference answer, label, or review rubric for each example.
- Separate a development set from a final holdout set.
- Run every candidate model with the same prompt and settings.
- Score quality, latency, formatting, and failure severity.
A holdout set matters. If you repeatedly change prompts after seeing every result, you are testing your memory rather than the system’s ability to generalize.
📏 7. Measure Quality Beyond “It Looks Good”
Casual testing favors impressive prose and misses quiet operational failures. Measure the outcome that matters to the workflow.
| Task type | Useful measurements | Important failure to inspect |
|---|---|---|
| Classification | Accuracy, precision, recall, class-level errors | Confidently misrouted requests |
| Extraction | Field accuracy, valid schema rate | Invented or missing values |
| Summarization | Factual coverage, reviewer preference | Unsupported claims |
| Support drafting | Approval rate, edit distance, resolution rate | Wrong policy or unsafe promise |
| Code assistance | Tests passed, review acceptance | Security flaws or broken edge cases |
Also score abstention. A model that says it lacks enough information may be more useful than one that confidently fabricates an answer.
⏱️ 8. Test Latency in the Way Users Experience It
Average latency can hide a frustrating product. Measure time to first token, total response time, and slow-tail behavior under realistic concurrency.
For a live chat interface, a fast first token often feels more responsive than a slightly faster total completion. For overnight document processing, throughput and reliability may matter far more than interactive delay.
- Test short, medium, and long prompts separately.
- Test expected peak concurrency rather than one request at a time.
- Include retrieval, safety checks, parsing, and network travel in the measurement.
- Record timeout and retry behavior.
- Measure on the hardware and region you plan to use.
Small local models can avoid network round trips. Hosted large models may still win in some settings because their infrastructure is optimized, so benchmark your complete pipeline instead of assuming.
💸 9. Calculate Total Cost, Not Just Model Cost
A low per-token price or low hardware requirement does not automatically create the lowest-cost system. Include every component that turns a model response into a useful result.
total cost per successful task =
  inference cost
  + retrieval and embedding cost
  + hosting and monitoring
  + retries and fallbacks
  + human review cost
  + cost of errors
The final term is frequently ignored. A small model that saves compute but causes agents to rewrite half its responses may cost more than a stronger model that produces usable drafts.
For self-hosting, consider hardware utilization, model loading time, scaling, logging, patching, and on-call ownership. For hosted services, check current official documentation for context limits, data policies, rate limits, and pricing because those details change.
🪜 10. Improve Small-Model Results With Task Decomposition
Do not ask a compact model to solve a sprawling problem in one prompt. Break the job into steps that have clear inputs and outputs.
Suppose you need to process a customer message. Instead of requesting “analyze this and write the perfect response,” separate identification, extraction, policy lookup, drafting, and confidence checking.
Step 1: classify the request
Step 2: extract account or order details
Step 3: retrieve approved policy passages
Step 4: draft a response using only retrieved passages
Step 5: validate required fields and escalation rules
This design makes errors easier to detect and lets you assign different models to different stages. A small model may handle the first, second, and fifth steps extremely well.
📝 11. Write Prompts That Reduce Ambiguity
Small models have less room for guessing what you meant. Give a precise role, a narrow goal, allowed evidence, output schema, and clear behavior when information is missing.
You are a support-ticket classifier.

Classify the message into exactly one label:
billing, technical, account_access, cancellation, other.

Return only this JSON shape:
{"label":"...","confidence":0-1,"needs_human":true|false}

Set needs_human to true if the message contains a threat,
legal claim, account-security concern, or insufficient information.

Message:
{{ticket_text}}
Place the most important instruction near the end as well as near the beginning if your prompt is long. Use one or two representative examples when labels are subtle, but do not crowd out the user’s actual content.
Common prompt mistakes
- Combining multiple unrelated goals in one request.
- Requesting “detailed” output without defining what details matter.
- Leaving the output format optional.
- Assuming the model knows internal terms or policies.
- Demanding certainty when the system should escalate uncertainty.
📚 12. Add Retrieval Instead of Asking the Model to Remember Everything
Retrieval-augmented generation gives the model selected, relevant source material at request time. It often lets a small model answer domain-specific questions far better than it could from its parameters alone.
- Collect approved source documents.
- Split them into coherent chunks with titles and metadata.
- Index the chunks for semantic and, when useful, keyword search.
- Retrieve a small number of relevant passages for each question.
- Tell the model to answer only from those passages or say it cannot find support.
Answer the question using only the supplied sources.
If the sources do not support an answer, say:
"I don't have enough approved information to answer that."
Do not infer policy details.

Sources:
{{retrieved_passages}}

Question:
{{user_question}}
Retrieval is not magic. Bad chunking, stale documents, poor search, and irrelevant context can lower quality. Evaluate retrieval separately from generation so you know where the failure occurred.
🧱 13. Enforce Structured Output in Your Application
For automation, prose is often the wrong interface. Ask for a predictable structure, validate it in code, and retry or escalate when validation fails.
Use a schema supported by your chosen platform when available. Otherwise, request JSON and treat it as untrusted input until your application parses and checks it.
function handleResult(text) {
  const result = JSON.parse(text);
  const labels = ["billing", "technical", "account_access", "cancellation", "other"];

  if (!labels.includes(result.label)) throw new Error("Invalid label");
  if (typeof result.needs_human !== "boolean") throw new Error("Invalid flag");
  if (result.confidence < 0 || result.confidence > 1) throw new Error("Invalid confidence");

  return result;
}
Validation is especially valuable with small models because a narrow output contract reduces the amount of language generation they must do correctly.
🔀 14. Route Requests to the Right Model
A practical architecture often uses a small model as the default and a larger model as a fallback. This approach is called model routing.
Route based on observable signals, not a vague feeling that a request looks hard. Signals can include input length, language, retrieval confidence, task type, policy risk, parser failures, low model confidence, or a user request for deeper analysis.
if request.is_sensitive:
    send_to_human_or_specialized_flow()
elif retrieval.score < MIN_RETRIEVAL_SCORE:
    use_large_model()
elif request.type in ["classify", "extract", "rewrite"]:
    use_small_model()
elif small_model.confidence < 0.75:
    use_large_model()
else:
    return_small_model_result()
Test the router itself. A routing error can be more damaging than a model error if it consistently sends difficult cases down the cheap path.
🖥️ 15. Consider Local and Edge Deployment
Small models can run on a workstation, private server, mobile device, or edge computer, depending on the model and available hardware. This can reduce response delay, improve offline capability, and keep some data within your environment.
Quantization, which stores model weights with lower numerical precision, can reduce memory use and sometimes improve practical deployment speed. It may also lower quality, especially on difficult tasks, so evaluate the exact deployed form rather than the original model alone.
- Start with a single-device prototype and realistic prompts.
- Monitor memory usage, heat, battery impact, and concurrent requests.
- Keep a server-side fallback for tasks that exceed local capability.
- Plan secure updates for both model files and application code.
Local does not mean automatically private or secure. Your application still needs access control, encrypted storage where appropriate, and careful logging policies.
🔒 16. Protect Privacy, Security, and People
Model selection is also a data-governance decision. Before sending content to any hosted service, understand what data is transmitted, retained, logged, and used under the provider’s current terms. Check official documentation and your organization’s policies.
Minimize the data in prompts. Replace identifiers with placeholders when possible, redact sensitive fields before inference, and keep retrieval permissions aligned with the user’s access rights.
- Never treat model output as authorization to disclose private information.
- Defend against prompt injection in retrieved documents and user content.
- Use human review for high-impact decisions.
- Record enough audit information to investigate failures without storing unnecessary sensitive text.
- Test for unequal performance across languages, writing styles, and user groups.
A smaller model can reduce data exposure when run locally, but it does not remove the need for responsible design.
🧯 17. Plan for Failure Instead of Hiding It
Every model can hallucinate, misunderstand context, produce invalid formatting, or reflect gaps in its training. Strong AI products expect these failures and make them recoverable.
Build explicit escape hatches: a human-review queue, a “not enough information” response, a retry with a simplified prompt, a larger-model fallback, and clear user controls for correction.
Track real-world outcomes after launch. Watch for rising escalation rates, repeated edits, complaints, parsing failures, and changes in request patterns. The model that won your initial test may stop being the best option as your product evolves.
🛠️ 18. Run a Simple Comparison Experiment This Week
You do not need a large platform team to make an evidence-based choice. Run a focused experiment with one real workflow and two candidate models.
- Choose one narrow task, such as classifying support messages.
- Select a small model and a larger model that your environment can access.
- Create a fixed prompt and a representative evaluation set.
- Run both models with the same inputs and output rules.
- Measure quality, valid-output rate, latency, and total cost.
- Review all severe failures manually.
- Set a routing or fallback rule based on the results.
Write down the decision in plain language: “Use the small model for standard tickets; escalate messages with low confidence, security issues, or poor retrieval.” That is a deployable policy, not just an interesting benchmark result.
✅ 19. Use This Quick-Start Checklist
- Define the task with a specific input, output, and success criterion.
- Start small for repeated, constrained, high-volume work.
- Use large models selectively for ambiguity, difficult reasoning, and complex synthesis.
- Test on real examples, including edge cases and failures.
- Measure end-to-end cost, including review and correction work.
- Constrain outputs with schemas, validation, and escalation rules.
- Add retrieval for changing or proprietary knowledge.
- Route intelligently instead of choosing one model for every request.
- Protect data and keep humans in high-impact loops.
- Monitor after launch and revisit the choice as usage changes.
The most efficient AI model is the smallest one that reliably meets your real-world quality bar, with a safe path to escalate when it does not. Build around that principle, and you can deliver faster, more affordable AI without treating capability as an all-or-nothing choice. ⚡🧠🚀