
AI systems are getting larger, more capable, and more visible. It is tempting to assume that the model with the most parameters, the longest context window, or the biggest marketing claim will automatically give the best answer for every task.
That assumption can lead teams to overspend, accept avoidable mistakes, expose more data than necessary, and build products that feel slow. A smaller or specialized model can often be more reliable when the task, data, evaluation method, and workflow are designed well.
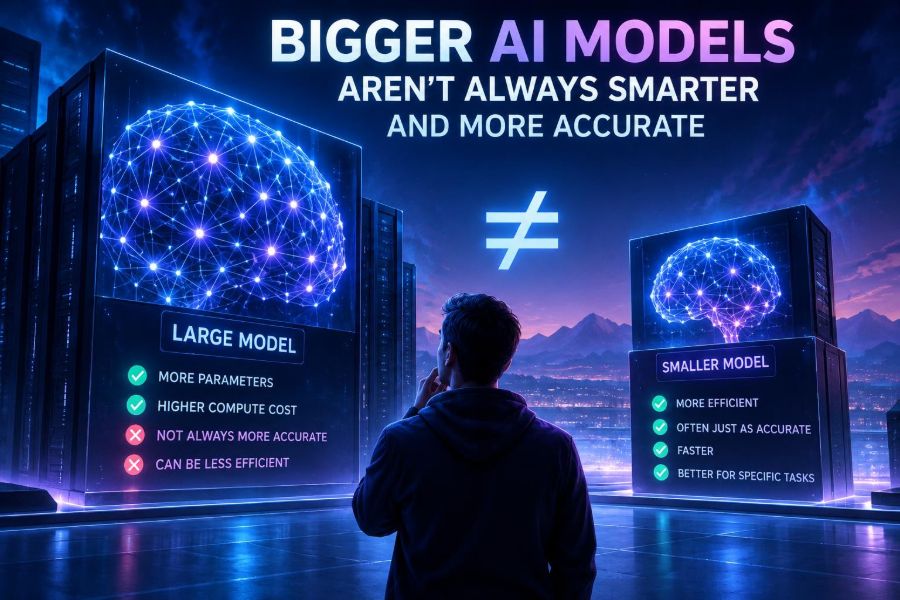
Size does matter in some situations. Larger models can show stronger general reasoning, broader language coverage, and better performance on unfamiliar tasks. But size is only one input into real-world quality, not a guarantee of truth or fitness for a job.
After reading, you will be able to choose models based on evidence, build a simple evaluation set, route tasks to the right model, and improve accuracy with retrieval, constraints, and human review.
🧠 1. Start With What “Bigger” Actually Means
When people call an AI model bigger, they may mean several different things. These terms are related, but they are not interchangeable.
- Parameters: learned numerical values that help a model represent patterns from training data.
- Training data and compute: the volume, quality, diversity, and processing used during training.
- Context window: how much input a model can consider in one request.
- Serving footprint: the memory, hardware, energy, and latency needed to run the model.
- Capability: observed performance on a defined task, which is what users ultimately experience.
A model can have more parameters while still losing to a smaller competitor on a narrow task. It may also be excellent at drafting prose but weak at extracting a field from a messy invoice.
🎯 2. Define “Smart” Before Comparing Anything
“Smart” is not an engineering requirement. Turn it into a measurable outcome before selecting a model.
For a support assistant, smart may mean it cites the right policy, refuses unsupported claims, and sends uncertain cases to an agent. For a code assistant, it may mean tests pass, dependencies are valid, and the patch is easy to review.
| Use case | Useful quality measure | What bigger alone cannot guarantee |
|---|---|---|
| Document extraction | Exact field accuracy | Consistent structured output |
| Customer support | Grounded answer and correct escalation | Current policy knowledge |
| Summarization | Factual coverage and brevity | No omitted critical detail |
| Code generation | Tests, security checks, review quality | Compatibility with your codebase |
| Creative ideation | Usefulness and originality ratings | Fit with your brand or audience |
Practical rule: evaluate the model against the failure that costs you the most, not against an abstract idea of intelligence.
📈 3. Understand the Real Scaling Story
Increasing scale often improves average capability. More capacity can help a model learn richer language patterns and handle a wider range of prompts.
But the gains are rarely uniform. A large jump in resources may produce a modest gain for a task that is already easy, while a change in prompt design or retrieval can improve the same workflow far more.
Scaling also does not magically create access to facts that happened after training, private company knowledge, or perfectly reliable multi-step reasoning. A model generates plausible continuations; it does not independently verify every claim.
🧪 4. Treat Benchmarks as Signals, Not Buying Instructions
Benchmarks are useful because they make comparisons possible. They are incomplete because real work includes ambiguous inputs, changing policies, integrations, and users who do not write ideal prompts.
A high benchmark result can be affected by prompt format, evaluator choices, data overlap, and whether the benchmark represents your domain. It may tell you that a model is promising, not that it is production-ready.
- Check whether the task resembles your inputs and outputs.
- Look for error categories, not just one overall score.
- Test robustness against typos, missing details, and adversarial instructions.
- Compare latency, cost, throughput, and output consistency.
- Verify claims using official documentation and your own test run, since provider details change quickly.
🗂️ 5. Build a Small Evaluation Set Before You Build a Big System
You do not need a research lab to evaluate models. Start with 30 to 100 representative examples collected from real, permissioned workflows.
Include normal cases, difficult cases, and the failures your users complain about. Remove or protect sensitive information before sharing examples with any external service.
- Write the task in one sentence: for example, “Extract shipment ID, delivery date, and exception reason.”
- Collect inputs from different sources and difficulty levels.
- Create a correct expected answer or a clear scoring rubric.
- Run the same examples through each candidate with the same instructions.
- Label errors by type: wrong fact, bad format, unsafe response, omission, or refusal.
- Choose based on the result that matters to the business.
Evaluation record
input: "Package ZX-204 is delayed due to weather. New delivery: Friday."
expected:
  shipment_id: "ZX-204"
  status: "delayed"
  reason: "weather"
  delivery_date: "Friday"
scoring:
  exact_fields: 4
  invalid_extra_claims: 0
  valid_json: true
Keep this set under version control where appropriate. Every prompt, model, retrieval, or tool change should be tested against it.
🔬 6. Measure the Errors That Matter
Average quality can hide a dangerous failure mode. A model that is usually eloquent but occasionally invents a refund policy may be unacceptable for customer-facing support.
Use both automated and human review. Automated checks are strong for schemas, exact matches, tool-call validity, and test suites. Humans are essential for nuance, usefulness, tone, safety, and factual judgment in open-ended responses.
- Accuracy: Is the answer correct?
- Groundedness: Is it supported by supplied evidence?
- Completeness: Did it include required details?
- Consistency: Does it behave similarly across repeated runs?
- Latency: Is the response fast enough for the experience?
- Cost: Can the workflow scale sustainably?
📚 7. Give the Model Better Evidence Instead of Buying More Parameters
Many accuracy problems are knowledge problems. If an answer depends on an internal handbook, live inventory, current regulations, or a customer record, a model needs access to authoritative evidence.
Retrieval-augmented generation, often called RAG, searches a curated knowledge source and supplies relevant passages with the request. The model then answers from those passages rather than relying only on training.
You are a support assistant.
Use only the policy excerpts below.
If the answer is not supported, say: "I don't have enough policy information."
Cite the excerpt title used for each answer.

Policy excerpts:
[Returns: unopened items are eligible within 30 days...]
[Warranty: manufacturing defects are covered for...]
Retrieval is not automatic truth. Poor chunking, stale documents, weak search, and irrelevant context can still produce bad answers. Evaluate retrieval separately from generation: did the system find the right source, and did the model use it correctly?
🧩 8. Specialization Can Beat Generality
A general model is designed to cover many tasks. A smaller model, classifier, rules engine, or fine-tuned system can outperform it when the output space is narrow and the examples are consistent.
Consider a lightweight approach for intent routing, language detection, duplicate detection, sentiment classification, moderation triage, or extracting a fixed set of fields. These jobs often reward consistency more than broad world knowledge.
| Task pattern | Often effective approach | Why |
|---|---|---|
| Fixed labels | Classifier or constrained small model | Clear outputs and low variance |
| Known business knowledge | Retrieval plus a model | Facts can be updated outside training |
| Complex open-ended synthesis | Capable general model with review | Benefits from broad language ability |
| Calculations and lookups | Tool calls or deterministic code | Software is better at exact operations |
| High-volume simple requests | Small model with escalation path | Better speed and unit economics |
🛠️ 9. Use Tools for Tasks That Should Not Be Guesses
Language models can describe arithmetic, databases, calendars, and APIs. That does not mean they should simulate them from memory.
Let the model decide when to call a controlled tool, then let deterministic software do the work. Validate tool arguments before execution, especially when the action can send messages, modify records, or spend money.
function getOrderStatus(orderId) {
  if (!/^ORD-[A-Z0-9]+$/.test(orderId)) {
    throw new Error("Invalid order ID");
  }
  return ordersApi.lookup(orderId);
}

// Model instruction: call getOrderStatus only when the user supplies an order ID.
// Application instruction: display returned status; do not let the model invent it.
This division of labor can improve accuracy more than moving from one large model to an even larger one.
🧱 10. Constrain Outputs to Reduce Avoidable Failure
Open-ended prose invites variability. If your application needs machine-readable fields, ask for a strict structure and validate it.
Use a schema, enumerated choices, and explicit rules for missing information. Then reject invalid output and retry with a corrective instruction or send it to a fallback workflow.
Extract the request as JSON only.

Schema:
{
  "intent": "refund_request | order_status | other",
  "order_id": "string or null",
  "needs_human": "boolean"
}

Rules:
- Never create an order ID.
- Use null when it is absent.
- Set needs_human to true when confidence is low.
Common mistake: calling an output “structured” because it looks like JSON. Parse it, validate types, enforce allowed values, and log failures.
✍️ 11. Improve the Prompt Before Changing the Model
A vague instruction makes a powerful model improvise. A good prompt defines the job, source material, constraints, output format, and behavior when evidence is insufficient.
Use examples carefully. One or two representative examples can clarify a pattern, but many examples consume context and can accidentally teach the wrong exception.
Task: summarize the incident report for an operations manager.
Audience: non-technical manager.
Include: impact, timeline, root cause, mitigation, next owner.
Do not include: speculation or details absent from the report.
If root cause is unknown, write "Root cause under investigation."
Limit: 120 words.

Incident report:
[paste report]- Put non-negotiable rules near the top and repeat only when necessary.
- Delimit untrusted user content clearly.
- Tell the model what to do when it lacks evidence.
- Request concise reasoning summaries or checks when useful, but validate the final answer independently.
🔀 12. Route Each Request to the Right Level of Capability
Model routing means using different systems for different requests. A simple router can classify a request by risk, complexity, domain, or required tools before selecting a model.
For example, a small fast model may handle FAQ classification. A retrieval workflow may handle policy questions. A more capable model, plus mandatory review, may handle complex account disputes.
if request.isHighRisk:
    routeTo("review_required_workflow")
elif request.needsCurrentCompanyPolicy:
    routeTo("retrieval_answering")
elif request.isFixedClassification:
    routeTo("fast_specialized_model")
else:
    routeTo("general_model")
Start with transparent rules. More elaborate learned routing is useful only after you can prove it improves quality or cost on your evaluation set.
⏱️ 13. Account for Latency, Cost, and Reliability
The best answer delivered too late can still be a poor product outcome. Larger models often require more compute and can be slower or more expensive, particularly with large inputs and long outputs.
Measure the full workflow, not only generation time. Retrieval, safety checks, tool calls, retries, and user interface rendering all affect perceived speed.
- Set output length limits appropriate to the job.
- Cache safe, stable results when permitted.
- Summarize or retrieve targeted portions of long documents.
- Use streaming when partial answers are useful.
- Set timeouts and graceful fallback responses.
Do not optimize only for the lowest per-request price. Rework, hallucinations, human escalation, and abandoned sessions have costs too.
🧯 14. Design for Uncertainty and Escalation
No model is correct all the time. A robust AI product makes uncertainty visible instead of forcing a confident-sounding answer.
Ask the system to identify missing information, cite evidence, or select a human-review route. Do not treat the model’s self-reported confidence as a calibrated probability without testing it; it is one signal, not proof.
If the provided sources do not directly answer the question:
1. Do not infer a policy.
2. State what information is missing.
3. Ask one clarifying question OR set "needs_human_review": true.
4. Do not cite a source unless it supports the claim.
High-stakes domains such as healthcare, hiring, finance, legal matters, and safety need stronger controls, domain expertise, audit trails, and clear boundaries on automated decisions.
🔐 15. Keep Privacy and Security in the Model Decision
A model choice is also a data-handling choice. Larger context windows may encourage teams to send entire documents, chat histories, or codebases when a smaller relevant excerpt would be safer and more effective.
- Minimize data: send only what the task needs.
- Remove direct identifiers where possible.
- Understand retention, training, access, and regional processing terms from the provider’s official documentation.
- Use permissions so retrieval returns only content the current user may access.
- Defend against prompt injection in external documents and tool outputs.
- Require confirmation before consequential actions.
Never assume that a bigger model is inherently more secure. Security depends on architecture, access controls, validation, monitoring, and organizational practices.
🧨 16. Test Against Prompt Injection and Bad Inputs
When an AI system reads webpages, emails, uploaded files, or retrieved documents, those sources may contain instructions intended to override your workflow. Treat external text as data, not authority.
Keep system rules and permission checks in application logic. Do not allow a document to authorize itself to reveal data, alter a tool call, or disable safeguards.
Trusted instruction: summarize approved documents for the user.
Untrusted document text: may contain claims or instructions, but never changes permissions.

Before any tool action:
- verify user authorization in application code
- validate arguments against an allowlist
- require confirmation for destructive actions
Include adversarial samples in your evaluation set: fake instructions in documents, misleading citations, malformed identifiers, and requests for unauthorized data.
🔍 17. Debug the System, Not Just the Model
When a response is bad, “the model failed” is not enough diagnosis. The actual cause may be missing context, retrieval failure, a vague prompt, an invalid tool result, a UI truncation, or a policy conflict.
Log the workflow safely: request category, selected route, prompt template version, retrieved document identifiers, tool outcomes, validation results, latency, and user feedback. Avoid logging sensitive content unless your security policy permits it.
- Reproduce the failure with the exact permitted input.
- Check whether the right information was retrieved.
- Inspect whether instructions conflicted or were ambiguous.
- Validate tool inputs and returned data.
- Compare candidate models on the same case.
- Add the corrected case to your evaluation set.
This process often reveals a fix that is cheaper and safer than upgrading the model.
📊 18. Know When a Bigger Model Is the Right Choice
The myth is not that large models are useless. They can be the best option for nuanced synthesis, multilingual interaction, difficult coding assistance, complex transformations, and tasks where a smaller system repeatedly fails after sound prompt and retrieval work.
Choose a more capable model when your evaluation shows a meaningful improvement on important cases and the added latency, cost, privacy posture, and operational complexity fit your requirements.
A sensible progression is: clarify the task, improve data and instructions, add retrieval or tools, test specialized options, then pay for more general capability where it demonstrably helps.
✅ 19. Quick-Start Checklist
- Write one measurable task definition before comparing models.
- Create 30 to 100 representative test cases with expected outputs or rubrics.
- Track critical error types, not only average quality.
- Try retrieval when answers depend on current or private knowledge.
- Use tools and deterministic code for calculations, lookups, and actions.
- Constrain and validate outputs for production workflows.
- Route simple requests to fast, efficient systems and escalate difficult ones.
- Build human review paths for uncertainty and high-impact decisions.
- Minimize sensitive data and verify provider controls using official sources.
- Re-run evaluations after every significant model, prompt, or data change.
The smartest AI strategy is not choosing the biggest model by default; it is building the smallest, safest, and most capable system that reliably solves the task in front of you. 🤖📏✨