
AI systems increasingly need to work with information that is messy, abundant, and expressed in human language. A support ticket, product description, meeting note, image caption, code comment, and search query may use different words while referring to the same idea. Traditional keyword search often misses those connections.
Embeddings give software a practical way to represent meaning so related pieces of information can be found, grouped, recommended, and supplied to an AI model at the right time. They are a core building block behind semantic search, recommendation systems, retrieval-augmented generation, and many AI applications.
You do not need advanced mathematics to use embeddings well, but understanding the basic mental model prevents expensive mistakes. The choices you make around chunking, metadata, distance metrics, evaluation, and privacy matter as much as the embedding model itself.
After reading, you will be able to explain embeddings clearly, design a small semantic search workflow, write better retrieval queries, choose an appropriate storage approach, and evaluate whether your AI is actually finding useful information.
🧭 1. Start With the Core Idea: Meaning as Coordinates
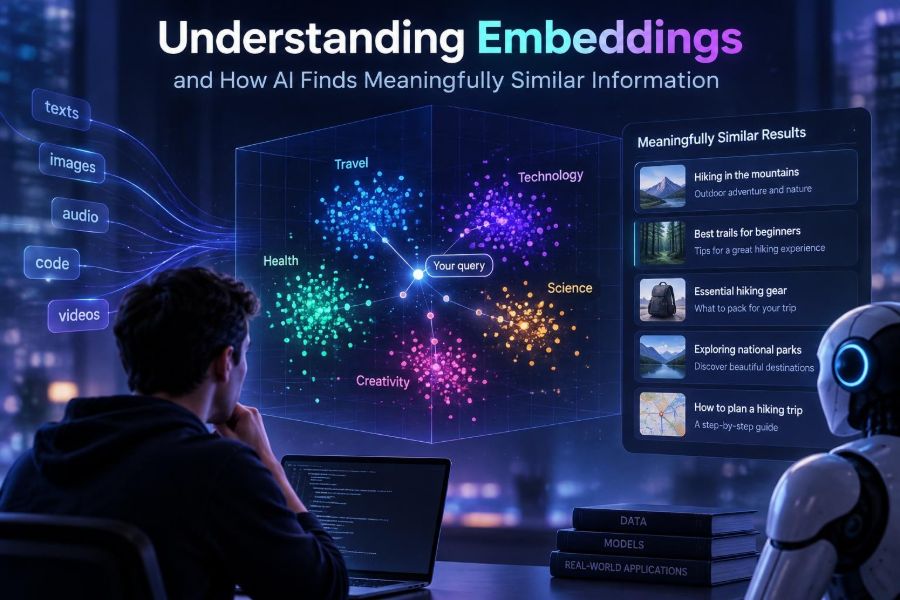
An embedding is a list of numbers, often called a vector, that represents the meaning or characteristics of something. The “something” can be text, an image, audio, code, a product, or even a user’s behavior.
Imagine placing every document in a vast map. Documents about password resets would land near one another, even if one says “cannot sign in” and another says “forgot my credentials.” A document about shipping delays would land elsewhere.
The coordinates are not designed for humans to interpret one by one. Their value comes from comparing complete vectors: items with similar meanings tend to be closer together in this mathematical space.
Text: "My account is locked"
Embedding: [0.18, -0.07, 0.42, ...]

Text: "I cannot access my profile"
Embedding: [0.20, -0.05, 0.39, ...]

Text: "Track my parcel"
Embedding: [-0.31, 0.66, -0.12, ...]
🔎 2. See Why Keyword Search Is Not Enough
Keyword search looks for literal terms. It is fast, transparent, and still extremely useful, especially for exact identifiers, names, error codes, and legal phrases.
Its weakness is vocabulary mismatch. A user searching “make text larger” may never find a guide titled “adjust font size” if the system depends solely on matching words.
Semantic search uses embeddings to retrieve items that are conceptually related rather than textually identical. It can bridge synonyms, paraphrases, varying levels of detail, and sometimes related wording across languages.
| Need | Keyword search | Embedding search |
|---|---|---|
| Find an exact error code | Excellent | Usually unnecessary alone |
| Find answers phrased differently | Often weak | Strong |
| Search a tiny collection | Simple and sufficient | May be unnecessary |
| Retrieve relevant context for an AI assistant | Useful signal | Often essential |
| Explain why a result matched | Easy to inspect | Needs added evidence and labels |
The practical answer is often hybrid search: combine keyword matching with vector similarity, then rank the candidates using both signals.
🧠 3. Understand What an Embedding Model Learns
An embedding model is trained to convert an input into a vector while preserving useful relationships. Its training teaches it patterns in language, structure, context, and sometimes multiple kinds of media.
It does not contain a perfect dictionary of truth. It creates a useful approximation based on patterns from its training and the way it was optimized. “Similar” can mean topical similarity, semantic similarity, stylistic similarity, or a blend of these.
- Text embeddings represent sentences, passages, queries, and documents.
- Multimodal embeddings can place text and images in a shared or comparable space.
- Code embeddings may capture programming concepts, APIs, and code structure.
- Domain-specific embeddings can work better for specialized language when properly validated.
Choose a model based on your task, languages, input size, deployment constraints, privacy needs, and measured retrieval quality. Provider details evolve quickly, so check official documentation before committing to a model or platform.
📏 4. Compare Vectors With Similarity Metrics
Once you have vectors, the system needs a way to determine which ones are nearest to a query vector. This calculation is called a similarity metric or distance function.
Cosine similarity compares the direction of vectors and is widely used for semantic retrieval. Dot product is also common, particularly when a model and index are designed for it. Euclidean distance measures straight-line distance and can be suitable in some setups.
# Illustrative cosine similarity in Python
from math import sqrt

def cosine_similarity(a, b):
    dot = sum(x * y for x, y in zip(a, b))
    magnitude_a = sqrt(sum(x * x for x in a))
    magnitude_b = sqrt(sum(y * y for y in b))
    return dot / (magnitude_a * magnitude_b)
Do not casually switch metrics after indexing data. Your embedding model, vector database, normalization strategy, and search metric should be compatible. Follow the model provider’s guidance, then validate with real queries.
🗂️ 5. Turn Documents Into Searchable Chunks
Embeddings generally work better on focused passages than on huge documents. A 50-page handbook may discuss dozens of topics; one vector for the whole file blurs them together.
Chunking splits source material into retrievable units. A useful chunk contains enough context to answer a question but stays focused on a coherent topic.
- Extract clean text from your source files.
- Remove navigation, duplicate footers, and irrelevant boilerplate.
- Split by headings, paragraphs, or semantic sections where possible.
- Set a reasonable chunk length for your model and content type.
- Add a small overlap so important context is not cut at boundaries.
- Create one embedding per chunk and store the original chunk text.
For a policy document, a section and its exceptions may belong together. For a troubleshooting guide, one problem-and-solution block is often a better unit. There is no universal chunk size; test against questions your users genuinely ask.
🏷️ 6. Treat Metadata as a First-Class Signal
A vector tells you what a chunk broadly means. Metadata tells you what it is, where it came from, when it applies, and who can access it.
Store metadata next to every vector so you can filter results before or during search. This improves precision and is essential for access control.
{
  "id": "help-204-section-3",
  "text": "To reset a password, select Forgot Password...",
  "embedding": [0.18, -0.07, 0.42],
  "metadata": {
    "source": "account-help",
    "section": "Password reset",
    "language": "en",
    "updated_at": "2025-01-15",
    "audience": "customer",
    "access_group": "public"
  }
}- Filter by product, region, language, document type, or publication status.
- Preserve source titles, section labels, and stable source identifiers for citations.
- Track update timestamps so stale content can be identified or excluded.
- Enforce permissions in retrieval, not only in the application interface.
🧱 7. Build a Minimal Semantic Search Pipeline
A basic pipeline has two phases: indexing and querying. Indexing happens when content changes; querying happens when a person or application searches.
- Collect and clean approved source content.
- Chunk it and attach metadata.
- Create embeddings for each chunk.
- Store vectors, text, and metadata in an index.
- Create an embedding for the user’s query.
- Retrieve the nearest permitted chunks.
- Present results or pass selected context to an AI model.
# Pseudocode: provider and database APIs vary
chunks = split_into_chunks(document_text)

for chunk in chunks:
    vector = embedding_model.embed(chunk.text)
    vector_index.upsert(
        id=chunk.id,
        vector=vector,
        metadata={"text": chunk.text, "source": chunk.source}
    )

query_vector = embedding_model.embed("How do I get back into my account?")
results = vector_index.search(query_vector, top_k=5)
Keep this first version small. A well-curated collection of a few hundred chunks can teach you more than a poorly prepared archive of millions.
🧰 8. Choose Storage Based on Your Actual Requirements
You can store vectors in a dedicated vector database, a search platform with vector features, a relational database extension, or an in-memory library for prototypes. The best choice depends on scale, filtering, operations, latency, compliance, and team skills.
| Approach | Best fit | Watch for |
|---|---|---|
| In-memory vector library | Learning, local experiments, small datasets | Persistence, scaling, production operations |
| Relational database with vector support | Teams already centered on relational data | Index tuning and large-scale performance |
| Search platform with vector retrieval | Hybrid search and mature search workflows | Configuration complexity |
| Dedicated vector database | Vector-heavy workloads and managed operations | Cost, portability, filter capabilities |
Before choosing, test the features that matter: metadata filters, updates and deletes, hybrid ranking, tenant isolation, backups, observability, and permission enforcement. Marketing claims are not a substitute for a representative proof of concept.
💬 9. Use Retrieval-Augmented Generation Carefully
Retrieval-augmented generation, often shortened to RAG, gives a language model relevant external context before it answers. Embeddings are commonly used to select that context.
RAG can make an assistant more grounded in current internal documentation, product manuals, or approved knowledge. It does not magically guarantee truth: poor retrieval produces poor context, and a model can still misread, omit, or invent details.
System instruction:
Answer using only the supplied reference passages. If the passages do not
answer the question, say that you do not have enough information. Cite the
source title and section for each factual claim.

User question:
Can an administrator reset a team member's password?

Reference passages:
[1] Account Administration — Password Management
...
Ask the model to distinguish the answer from the evidence. In high-stakes settings, return source passages to the user and route uncertain cases to a human instead of optimizing only for a smooth-sounding response.
🎯 10. Write Queries That Retrieve Better Context
Embedding models can handle natural language, so users should not need to think in database syntax. Still, a vague question creates a vague retrieval target.
For an AI workflow, you can rewrite a short conversational question into a clear retrieval query while preserving the user’s intent. Do not change the meaning or add unsupported assumptions.
Original: "It keeps rejecting me"

Retrieval query: "Troubleshooting account sign-in rejection and locked account access"

Original: "Can we use this in Germany?"

Retrieval query: "Product availability, compliance, and supported use in Germany"- Include the product, task, audience, or timeframe when known.
- Use metadata filters for known attributes instead of hoping semantic search infers them.
- Run multiple query formulations for ambiguous requests when warranted.
- Keep the original user wording for the final response and audit trail.
🔀 11. Improve Results With Hybrid Retrieval and Reranking
Vector search is excellent at semantic recall, but it can miss exact phrases that matter. Keyword search catches terms such as model numbers, commands, rare names, and error messages.
Hybrid retrieval combines both candidate sets. A second stage, called reranking, can then score the top results against the full query with a more precise but slower model or rule set.
- Retrieve candidates from vector similarity.
- Retrieve candidates from keyword matching.
- Merge and remove duplicates.
- Apply filters for permissions and relevance constraints.
- Rerank the remaining small set.
- Return the best passages with their sources.
This two-stage approach is often more valuable than replacing an embedding model repeatedly. First retrieve broadly, then decide precisely.
🧪 12. Evaluate With a Real Query Set
“The results look good” is not an evaluation plan. Create a small, representative set of questions with known good documents or passages, then measure whether your system brings them near the top.
Include easy questions, paraphrases, exact-term lookups, ambiguous requests, outdated-content traps, and questions that your knowledge base cannot answer.
| Signal | Question it answers | Why it matters |
|---|---|---|
| Recall at k | Did a relevant result appear in the top k? | Retrieval cannot use context it never finds |
| Precision at k | How many top results were useful? | Too much noise wastes model context |
| Answer groundedness | Is the answer supported by retrieved text? | Reduces persuasive unsupported claims |
| Latency | How quickly does the workflow respond? | Shapes user trust and usability |
Review failures manually. A numerical score tells you that something failed; reading the retrieved chunks tells you whether the problem is chunking, missing documents, poor metadata, an ambiguous question, or ranking.
🛠️ 13. Debug Retrieval Before Blaming the Chatbot
When a RAG answer is wrong, inspect the pipeline in order. The generator is frequently blamed for a retrieval failure that happened earlier.
- Was the correct source ingested at all?
- Was it parsed cleanly, without tables or headings being mangled?
- Was it split into a meaningful chunk?
- Did the query retrieve that chunk among the candidates?
- Did filters accidentally exclude it?
- Did reranking push it down?
- Did the language model use the supplied context correctly?
Log the query, applied filters, candidate identifiers, similarity scores, reranked order, prompt context, and final answer. Avoid logging sensitive raw content unless your security policy explicitly permits it.
⚠️ 14. Avoid the Most Common Embedding Mistakes
Many embedding projects fail through data and workflow design, not because vectors are mysterious. Watch for these recurring issues.
- Embedding an entire document as one record: retrieval becomes broad and imprecise.
- Discarding source text: a vector alone cannot provide readable evidence.
- Ignoring stale content: old policies can become highly relevant for the wrong reason.
- Using similarity as truth: close vectors indicate relevance, not factual correctness.
- Skipping access filters: semantic search can expose sensitive information across teams.
- Testing only polished demo questions: real users phrase needs unpredictably.
- Comparing scores across incompatible models: score scales and behavior can differ.
Also avoid treating a similarity threshold as universal. A useful threshold depends on the model, metric, collection, content quality, and risk tolerance.
🔐 15. Protect Privacy, Permissions, and Sensitive Data
Embedding data can still be sensitive. Although a vector is not ordinary readable text, it may reveal information when combined with the source, metadata, logs, or other systems.
Send only approved data to external services. Understand where inputs are processed, retained, and used according to the provider’s current terms and your organization’s requirements.
- Classify data before indexing it.
- Apply tenant and user permission filters before returning results.
- Minimize stored personal information in chunk text and metadata.
- Define deletion and re-indexing workflows for changed or removed content.
- Encrypt data in transit and at rest where appropriate.
- Test for cross-user and cross-tenant retrieval leaks.
For medical, legal, financial, employment, or safety-critical uses, involve domain experts and compliance teams. Retrieval can improve access to information, but it does not replace accountable review.
🌍 16. Account for Language, Culture, and Domain Vocabulary
Multilingual embedding models can make cross-language search possible, but quality varies by language and use case. Test with the languages your audience actually uses, including regional phrasing and mixed-language queries.
Specialized fields introduce another challenge. A word such as “cell,” “bond,” “claim,” or “port” means different things in biology, finance, insurance, and networking.
Improve performance by keeping domain context in chunks, adding controlled metadata, including realistic domain queries in evaluation, and considering a domain-appropriate model only after establishing a baseline. More specialized is not automatically better.
📈 17. Know When to Re-Embed Your Data
You need to create embeddings again when source content changes, when chunks are restructured, or when you intentionally change to a new embedding model. Store model and pipeline metadata with each record so this process is manageable.
{
  "chunk_id": "guide-17-04",
  "content_hash": "...",
  "embedding_model": "approved-text-embedding-model",
  "embedding_pipeline": "chunking-policy-a",
  "indexed_at": "2025-01-15"
}
A content hash helps detect whether a chunk has materially changed. Use queues or scheduled jobs for updates rather than re-embedding everything blindly, unless a model migration requires a full rebuild.
During a migration, do not mix vectors from incompatible embedding spaces in the same similarity comparison. Rebuild the index or maintain separate indexes while testing the new system.
🚀 18. Build a Useful First Project This Week
A small internal knowledge search tool is an ideal first embedding project. Pick a narrow, low-risk collection such as published team documentation, a product FAQ, or your own notes.
- Collect 20 to 50 high-quality documents.
- Write 25 realistic questions before building the interface.
- Chunk the documents by heading and paragraph.
- Create embeddings and store them with source metadata.
- Build a simple search screen that shows the top five passages.
- Evaluate retrieval before adding answer generation.
- Add a grounded AI answer only after the passages are consistently useful.
For creators, this can become a searchable archive of past scripts and research. For developers, it can become documentation discovery. For support teams, it can become an agent-assist layer that suggests approved material without replacing judgment.
✅ 19. Quick-Start Checklist
- Define one retrieval task rather than “make everything searchable.”
- Prepare clean source content with clear ownership and permissions.
- Chunk by meaning and retain enough local context.
- Store metadata for source, date, language, permissions, and filters.
- Use a compatible metric for your chosen embedding model and index.
- Test hybrid search when exact words or identifiers matter.
- Create a real evaluation set before declaring success.
- Inspect failures from ingestion through final response.
- Show sources when an AI answers from retrieved material.
- Protect sensitive data throughout indexing, retrieval, logging, and deletion.
Embeddings turn meaning into something software can compare, but thoughtful data design and evaluation turn that capability into a trustworthy AI experience. 🤖🧭✨