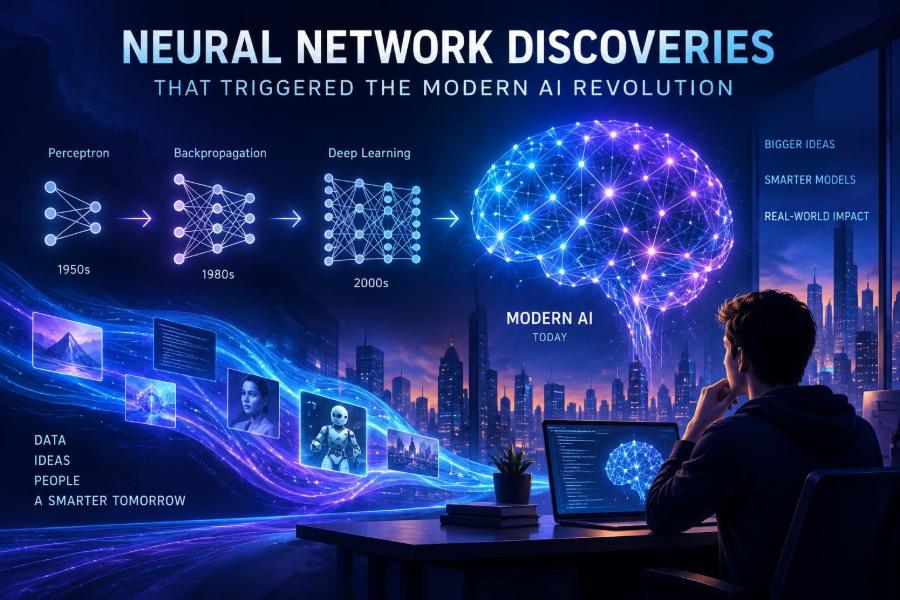

Modern AI can write, see, translate, predict, and generate code because a set of neural-network ideas finally began to reinforce one another. The apparent overnight revolution was actually the result of decades of research meeting abundant data, specialized computing, and better training techniques.
This history matters now because it makes today’s AI less mysterious. Once you understand the breakthroughs, you can choose the right model family, diagnose weak results, and make better decisions about building, buying, or using AI systems.
For creators and professionals, this article provides a practical map of what different neural networks are good at. For developers, it connects foundational concepts to implementation choices, evaluation, and deployment trade-offs.
By the end, you will be able to identify the discoveries behind current AI, recognize their limits, and sketch a small neural-network workflow without treating the model as magic.
🧠 1. Start with the central idea: learning representations
A neural network is a function with adjustable numerical parameters, usually called weights. Instead of programmers explicitly writing every rule for recognizing a cat or completing a sentence, training adjusts those weights from examples.
The decisive insight was representation learning: useful features can be learned from raw or lightly processed data. Early layers might detect edges or character patterns; later layers combine them into objects, concepts, or likely next words.
- Input: pixels, audio samples, tokens, tabular columns, or sensor signals.
- Parameters: values the training process changes.
- Output: a class, probability, number, sequence, or generated artifact.
📜 2. Remember that the “neuron” was a useful abstraction
The earliest artificial neurons were simplified mathematical units, not detailed simulations of biology. A unit takes inputs, multiplies them by weights, adds a bias, and applies an activation function.
z = w1*x1 + w2*x2 + b
output = activation(z)
This simplicity was a strength. It created a composable building block that can be arranged into layers and optimized with mathematics.
➕ 3. See why the perceptron was exciting and insufficient
The perceptron showed that a machine could learn a linear decision boundary from labeled examples. It could separate simple categories when a straight line, plane, or hyperplane was enough.
Its famous limitation was that a single layer cannot express many important relationships, including XOR. That limitation did not invalidate neural networks; it pointed to the need for hidden layers and a way to train them.
# XOR cannot be separated by one straight boundary
# Inputs: (0,0)->0, (1,0)->1, (0,1)->1, (1,1)->0
🔁 4. Understand backpropagation, the engine of deep learning
Backpropagation efficiently calculates how each parameter contributed to an error. It applies the chain rule from calculus from the output layer backward through the network.
An optimizer then nudges parameters in the direction that reduces loss. This made multi-layer networks trainable at a scale that hand-designed rules could not match.
- Run examples forward through the model.
- Measure error with a loss function.
- Compute gradients of that loss for every parameter.
- Update parameters.
- Repeat across many batches of data.
prediction = model(batch_x)
loss = loss_function(prediction, batch_y)
loss.backward()      # compute gradients
optimizer.step()     # update weights
optimizer.zero_grad()
Common mistake: thinking backpropagation is intelligence by itself. It is an optimization procedure; the data, objective, architecture, and evaluation define what the system learns.
📉 5. Use gradient descent without expecting a smooth ride
Training usually uses gradient descent or a variant. Full-dataset updates are costly, so practitioners commonly use mini-batches: small slices of examples that offer a practical approximation.
The learning rate controls update size. Too large and training becomes unstable; too small and progress is painfully slow or settles in an unhelpful region.
| Symptom | Likely cause | First action |
|---|---|---|
| Loss explodes or becomes invalid | Learning rate too high or unstable inputs | Lower rate; inspect data and gradients |
| Loss barely changes | Rate too low, weak features, or bug | Test a small dataset and inspect labels |
| Training improves, validation worsens | Overfitting | Add data, regularization, or early stopping |
🧩 6. Appreciate nonlinear activations
Stacking only linear layers still produces a linear function. Nonlinear activation functions let layered networks model curves, interactions, and conditional patterns.
Modern architectures often use efficient piecewise or smooth activations. The exact choice depends on architecture and task, so follow the conventions and documentation of the framework or model you use.
- Without nonlinearities: deeper is not more expressive.
- With nonlinearities: depth can build complex features from simpler ones.
- With poor activation or initialization: gradients can become too small or too large.
🖼️ 7. Recognize convolution as the vision breakthrough
Convolutional neural networks, or CNNs, made a powerful assumption about images: nearby pixels are related, and a useful pattern such as an edge can appear anywhere. Small filters scan across an image while sharing weights.
This reduced parameter count compared with connecting every pixel to every unit. It also gave models a useful form of translation awareness, enabling hierarchical visual features.
# Conceptual image classifier pipeline
image -> convolution -> activation -> pooling
      -> convolution -> feature map -> classifier
CNN-style ideas transformed image classification, detection, segmentation, medical imaging, and quality inspection. They remain valuable even as transformer-based vision models grow.
🧹 8. Learn the data lesson: scale helps only when data is credible
Neural networks improved dramatically when datasets became larger, more diverse, and more practical to process. But scale is not a substitute for data quality.
Before training, perform this minimum audit:
- Define what one example represents and who it excludes.
- Check duplicates, corrupt records, missing values, and label conflicts.
- Split data by a real-world boundary, such as time, user, device, or organization.
- Review class imbalance and rare but high-impact cases.
- Document collection, consent, licensing, and retention rules.
Common mistake: random splitting when near-duplicate examples cross into validation. The reported score can look excellent while real-world performance fails.
⚙️ 9. Connect specialized hardware to practical deep learning
Training is dominated by large matrix operations. Parallel processors and optimized numerical libraries made these operations much faster, allowing researchers to test larger models and datasets.
Hardware did not replace algorithmic discovery, but it changed what was feasible. Today, compute choice still determines batch size, model size, iteration speed, energy use, and cost. Consult current official documentation for supported accelerators and memory requirements because these details change quickly.
🧪 10. Make regularization your defense against memorization
A model can memorize training examples instead of learning patterns that generalize. Regularization includes techniques that discourage this behavior, alongside careful validation and more representative data.
- Early stopping: stop when validation performance stops improving.
- Weight decay: discourage overly large parameter values.
- Dropout: temporarily disable selected units during training.
- Augmentation: create plausible variations of training examples.
For image augmentation, preserve the label. A small crop might be valid for an object classifier but unsafe for a medical image where location matters.
🕰️ 11. See why sequence models needed memory
Language, speech, code, and time series depend on order. Recurrent neural networks process tokens or observations step by step while carrying a hidden state forward.
Gated variants improved their ability to preserve or forget information over longer ranges. They powered many sequence applications, but sequential processing limited parallelism and long-range dependencies remained difficult.
state = initial_state
for token in sequence:
    state = recurrent_cell(token, state)
    prediction = output_layer(state)
🎯 12. Understand attention before you use transformers
Attention lets a model weigh which other elements are most relevant to the current element. When translating a word, for example, the model can focus on the useful source words rather than compressing an entire sentence into one fixed vector.
This discovery made relationships more direct and inspectable at the mechanism level, though attention weights alone are not a complete explanation of a model’s reasoning.
score(query, key) -> relevance
softmax(scores) -> attention weights
weighted_sum(values) -> contextual representation
📚 13. Meet the transformer, the architecture behind many general models
The transformer combined attention with layers that transform each position’s representation. It can process many positions in parallel during training, a major advantage over strictly recurrent designs.
Transformers now support text, code, images, audio, biology, and mixed modalities. Their core benefit is not that they “understand” exactly like people; it is that they learn rich statistical representations from large collections of examples.
| Architecture | Strong fit | Practical caution |
|---|---|---|
| CNN | Images, local spatial patterns | May need task-specific design for global context |
| Recurrent network | Streaming sequences and compact temporal tasks | Long contexts and training parallelism are harder |
| Transformer | Flexible multimodal and long-context modeling | Compute and memory needs can grow quickly |
🗣️ 14. Follow self-supervised learning to understand foundation models
Labels are expensive. Self-supervised learning creates a training signal from data itself: predict a missing piece, the next token, a masked region, or a paired modality.
This enabled broad pretraining followed by adaptation to specific tasks. A foundation model may then be prompted, fine-tuned, or connected to retrieved documents and tools.
Pretraining: predict the next or missing part of broad data
Adaptation: teach task behavior with curated examples
Evaluation: test on realistic, held-out workflows
Do not confuse broad capability with domain reliability. A model trained on general text may still require domain data, retrieval, review, and guardrails.
🧭 15. Choose prompting, retrieval, or fine-tuning deliberately
These are complementary ways to adapt a model. Start with the lightest method that reliably solves the user problem.
| Approach | Use it when | Watch for |
|---|---|---|
| Prompting | Instructions and examples are enough | Fragile wording and inconsistent output |
| Retrieval-augmented generation | Answers need current or private documents | Bad retrieval, stale sources, access control |
| Fine-tuning | Repeated specialized style or task behavior is needed | Data quality, regression, maintenance effort |
Role: You are a support analyst.
Task: Summarize the incident using only the supplied notes.
Output: JSON with impact, timeline, unknowns, next_actions.
Rule: If evidence is absent, write "unknown" rather than guessing.
🧱 16. Build a small classifier as a learning project
A small project teaches more than a giant model you cannot inspect. Choose a narrow question, such as classifying support requests into a few categories or predicting whether a sensor reading needs review.
- Write a success criterion, including a human baseline.
- Collect examples and define labels with edge cases.
- Create train, validation, and test sets before experimenting.
- Build a simple baseline such as rules or logistic regression.
- Train a compact neural model only if it beats the baseline meaningfully.
- Inspect failures by category, not just one aggregate number.
# Pseudocode for an honest experiment
train(model, train_data)
tune(model, validation_data)
final_report = evaluate_once(model, untouched_test_data)
review_errors(final_report)
The baseline is essential. If a simpler method works as well, it is often cheaper, faster, easier to explain, and easier to maintain.
📏 17. Evaluate behavior, not just a single score
Accuracy can hide costly mistakes. Select measurements that match the decision: precision for expensive false alarms, recall for missed hazards, calibration for probabilities, and latency for interactive products.
- Test common cases and deliberately difficult edge cases.
- Break down results by language, input source, user group, and environment where appropriate and lawful.
- Have experts review samples for factuality, safety, usefulness, and tone.
- Monitor after deployment because inputs and user behavior change.
For generative systems, build a small evaluation set of real tasks with expected properties. “Sounds plausible” is not an adequate acceptance test.
🔍 18. Debug neural systems systematically
Most apparent model problems begin with data, objectives, or pipelines. Debug the smallest version of the system first.
- Verify input shapes, ranges, tokenization, and label alignment.
- Try to overfit a tiny clean sample; failure often signals a code or data bug.
- Compare against a simple baseline.
- Visualize or inspect representative inputs, outputs, and errors.
- Change one variable at a time and record the experiment.
Common mistake: repeatedly increasing model size before proving the pipeline is correct. Larger models can make a data leak or flawed labeler look temporarily convincing.
🛡️ 19. Treat privacy, bias, and safety as design requirements
Neural networks can expose sensitive information, reproduce harmful patterns in training data, and make confident errors. Responsible use begins before training and continues after launch.
- Minimize collection and remove unnecessary personal data.
- Use access controls and protect training, evaluation, and retrieval data.
- Obtain appropriate permission and respect licensing and governance requirements.
- Test for disparate failures and provide a human escalation path.
- Do not use generated output as the sole basis for high-impact decisions without suitable oversight.
For consumer tools, never paste confidential client data, secrets, or regulated records unless your organization has approved the workflow and data handling. Check the official terms, security documentation, and applicable policies for current details.
🚀 20. Quick-start checklist
- Identify whether your problem is vision, language, audio, time series, or structured data.
- Write down the user decision the system should improve.
- Start with a simple baseline and a small, well-defined dataset.
- Use backpropagation-based training with a validation plan, not just training loss.
- Choose CNNs for local visual structure, sequence models for streams, and transformers for flexible contextual modeling.
- Use prompting or retrieval before committing to fine-tuning.
- Test real failure modes, privacy constraints, and human handoff paths.
- Monitor deployed systems for drift, errors, and changing requirements.
The modern AI revolution came from combining learnable representations, scalable optimization, specialized architectures, data, and responsible engineering—not from one miraculous discovery. Build with that full picture in mind. 🤖✨