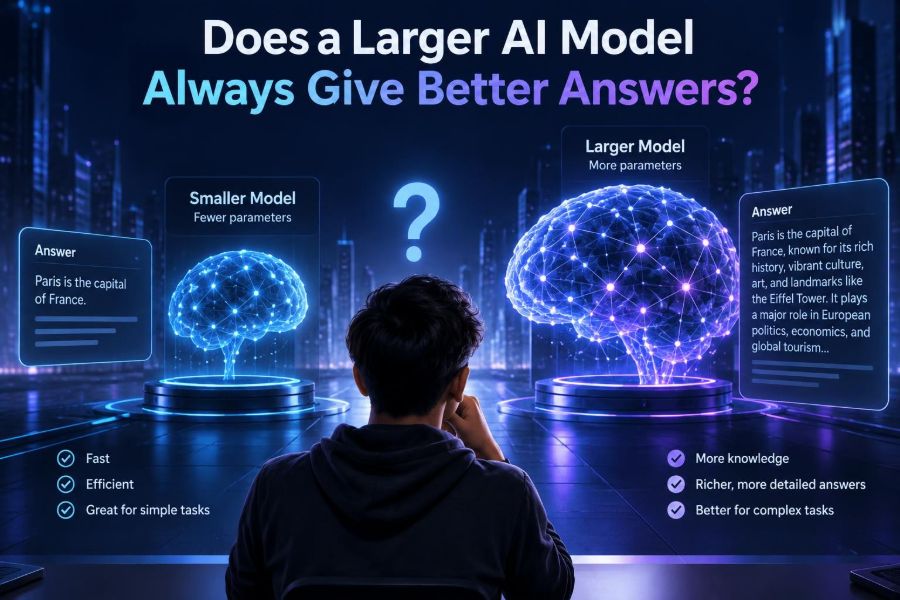

AI systems are getting bigger, more capable, and more expensive to run. It is tempting to assume that a larger model automatically produces a better answer. Sometimes it does. But “better” depends on the task, the data, the instructions, the available tools, and what you are willing to trade in cost, speed, privacy, and reliability.
This question matters now because teams are embedding AI into support desks, coding workflows, content pipelines, search products, and internal knowledge systems. Choosing a model by size or reputation alone can create slow, costly systems that still fail on the exact work users care about.
For creators and everyday users, understanding the difference helps you get stronger results without always reaching for the most powerful option. For developers, it leads to more disciplined evaluation, smarter routing, and systems that combine several kinds of models effectively.
By the end, you will be able to match model capability to a task, write tests that reveal real quality, decide when a small model is enough, and build a practical escalation path for harder requests.
🧠 1. “Larger” Is Not One Simple Thing
When people call an AI model larger, they often mean it has more parameters: adjustable numerical values learned during training. More parameters can give a model more capacity to represent patterns, language, and relationships.
But parameter count is not the whole story. A model’s useful performance also depends on training data, training methods, architecture, context capacity, post-training alignment, and whether it can use tools such as search, code execution, or document retrieval.
- Parameters: learned capacity inside the model.
- Training data: the examples and information shaping its behavior.
- Context window: how much supplied text it can consider at once.
- Post-training: methods that improve instruction following and safety.
- Tool use: access to fresh data, calculators, databases, or software.
A smaller, well-tuned model with the right document retrieval can beat a much larger general model on a narrowly defined company policy question.
📈 2. Scale Often Helps, but the Gains Are Uneven
Increasing model capacity has historically improved performance across many language, reasoning, coding, and multimodal tasks. Larger models frequently follow complex instructions better, handle ambiguity more gracefully, and make fewer obvious errors on broad evaluations.
Yet gains are usually not linear. Moving from a weak model to a capable one may transform a workflow. Moving from a capable model to an even larger one may improve only difficult edge cases while adding noticeable latency and cost.
Think of it as diminishing returns. The last increment of quality may matter enormously for a high-stakes legal review workflow, but barely matter for labeling a support ticket as billing, login, or bug report.
🎯 3. Define “Better” Before Comparing Models
An answer can be better in several conflicting ways. A model that writes a beautiful explanation may not be the best model for extracting an exact invoice field. A fast answer may be more valuable than a slightly more nuanced one when a customer is waiting.
| Goal | What to measure | Likely priority |
|---|---|---|
| Customer support routing | Correct category, speed, structured output | Small or medium model |
| Technical research summary | Accuracy, source grounding, caveats | Capable model plus retrieval |
| Code refactoring | Tests pass, patch quality, repository awareness | Stronger coding model plus tools |
| Creative brainstorming | Novelty, tone, controllability | Model chosen by human preference |
| Safety-sensitive advice | Appropriate boundaries, uncertainty, escalation | Carefully evaluated system |
Write your success criteria in plain language first. If you cannot say what a good answer does, a general benchmark score will not solve the selection problem.
🧪 4. Use Your Own Tasks, Not Just Public Benchmarks
Benchmarks are useful signals, but they are not a guarantee for your workload. They can emphasize academic questions, curated coding exercises, or multiple-choice formats that do not resemble messy user requests.
Build a small evaluation set from real, privacy-safe examples. Start with 30 to 100 representative cases, then grow it as your product changes.
- Collect representative tasks and remove sensitive details.
- Include easy, typical, and difficult cases.
- Write the expected result or a scoring rubric.
- Run the same prompt and settings across candidate models.
- Review failures by category, not just average score.
Task: Classify the customer message into one label only.
Labels: billing, account_access, technical_issue, cancellation.

Message: “I was charged twice after updating my card.”

Return JSON only:
{"label":"...","confidence":0.0}
For this task, exact JSON and correct classification matter more than eloquent prose. A compact model may be the superior production choice.
🔍 5. Separate Knowledge Problems from Reasoning Problems
Many apparent reasoning failures are actually information failures. If the model does not have current, proprietary, or obscure facts, making it larger will not reliably fix the gap.
For questions about your manuals, contracts, product catalog, or current policy, retrieve relevant material first. Then ask the model to answer using that material and state when the evidence is insufficient.
You are a support assistant. Answer only from the supplied policy excerpts.
If the excerpts do not answer the question, say: “I don’t have enough policy information.”

Policy excerpts:
[insert retrieved passages]

Customer question:
[insert question]

Give a concise answer and cite the excerpt title used.
This pattern is often called retrieval-augmented generation. It makes the answer more grounded and auditable, regardless of model size.
🧰 6. Tools Can Matter More Than Raw Model Size
A model without a calculator can make arithmetic mistakes. A model without database access cannot verify inventory. A model without code execution cannot truly run the script it proposes.
Give the system a constrained tool for the job, and define when it must use it. The model becomes an orchestrator: it interprets a request, calls the appropriate capability, then explains the result.
- Use a calculator or code sandbox for numerical work.
- Use approved search or retrieval for current information.
- Use databases or APIs for account-specific facts.
- Use validators for JSON, schemas, dates, and business rules.
Tool-enabled systems need careful permissions. A model should not be able to send emails, change records, or run destructive commands merely because it generated a convincing instruction.
⚡ 7. Small Models Win When Speed and Volume Dominate
For repeated, bounded tasks, smaller models can be excellent. They generally respond faster, cost less per request, and are easier to deploy close to where data is created.
Good candidates include classification, extraction, short summarization, format conversion, autocomplete, moderation pre-filtering, and first-pass triage. The key is that the task has clear boundaries and measurable output.
Extract fields from the text below.
Return valid JSON with exactly: name, order_id, issue.
Use null for missing fields. Do not infer unknown values.

Text: “Hi, I’m Maya Chen. Order A-1049 arrived with a damaged cable.”
A common mistake is choosing a large conversational model for every API call. Start with the smallest model that meets your quality threshold, then reserve stronger capacity for exceptions.
🧩 8. Bigger Models Help Most on Ambiguous, Multi-Step Work
Larger or more capable models tend to earn their place when requests are underspecified, involve several constraints, require synthesis across long material, or need careful planning before action.
Examples include debugging across multiple files, comparing competing proposals, drafting a tailored strategy, reconciling conflicting requirements, and interpreting nuanced tone. Even here, they can fail, so use checks rather than blind trust.
Ask the model for a structured deliverable, not an invitation to improvise. Clear output constraints reduce ambiguity for both the model and the person reviewing it.
Review this design proposal against these requirements.

Requirements:
1. Must support offline use.
2. Must not store customer content by default.
3. Must provide an audit trail for changes.

Return:
- requirement-by-requirement verdict: meets, partially meets, or does not meet
- evidence from the proposal
- open questions
- top three risks

Do not claim a requirement is met unless the proposal explicitly supports it.
🗣️ 9. Prompt Design Changes the Comparison
An unfair model comparison gives one model vague instructions and another model a refined prompt. Use identical inputs, formatting, and output requirements when testing candidates.
Strong prompts provide a role only when it adds useful context, a concrete goal, relevant input, constraints, and a requested output shape. They do not need theatrical language to work well.
- State the task before adding background.
- Specify what to do with uncertainty.
- Give an output schema or example where formatting matters.
- Set a length limit when concise output is desired.
- Include counterexamples for common failure modes.
Summarize the meeting notes for an engineering manager.

Include only:
1. decisions made
2. owners and deadlines explicitly stated
3. blockers
4. unresolved questions

Do not invent owners or dates. If none are stated, write “not specified.”
Use four labeled bullet lists.
Prompting cannot turn a weak model into a specialist expert, but it can eliminate avoidable failures and make a modest model much more dependable.
🧱 10. Structured Outputs Make Models Easier to Trust
Free-form prose is pleasant for people but difficult for software. When an answer will trigger a workflow, ask for a schema and validate it before taking action.
Use your platform’s supported structured-output or schema feature when available. If not, instruct the model to produce strict JSON, parse it defensively, and retry or escalate when validation fails.
{
  "action": "reply | escalate | request_information",
  "priority": "low | medium | high",
  "reason": "short explanation",
  "missing_information": ["string"]
}
function handleModelOutput(text) {
const result = JSON.parse(text);
const allowed = ["reply", "escalate", "request_information"];
if (!allowed.includes(result.action)) throw new Error("Invalid action");
if (result.action === "escalate") return queueForHumanReview(result);
return result;
}Validation does not prove the content is true. It does ensure that a response cannot silently break your application because a field changed shape or a required value is missing.
🛣️ 11. Build a Model Routing Strategy
You do not need one model for every request. A routing strategy sends straightforward work to a fast, economical model and directs difficult or high-risk work to a stronger model or a human reviewer.
Route using signals that are observable and testable: request length, task type, language, required tools, confidence, validation errors, or the user’s explicit request for deeper analysis.
if task in ["classify", "extract", "format"]:
    use_fast_model()
elif contains_sensitive_decision(task):
    use_review_workflow()
elif retrieval_has_low_coverage() or output_validation_failed():
    use_stronger_model()
else:
    use_standard_model()
Do not treat a model’s self-reported confidence as proof. Combine it with external signals such as retrieval coverage, agreement between checks, rule validation, and historical error rates.
💰 12. Calculate Total Cost, Not Just the Model Call
A large model’s usage cost is only one part of the equation. Slow responses may reduce conversion, retry loops may inflate spending, and poor answers may create expensive human rework.
Measure total workflow cost: model calls, retrieval, tool execution, storage, monitoring, engineering time, and the cost of wrong actions. A cheaper model that needs constant correction is not necessarily economical.
| Approach | Main benefit | Main trade-off |
|---|---|---|
| One powerful model | Simple architecture, broad capability | Can overpay for easy tasks |
| One small model | Fast, low-cost operation | May fail on complex edge cases |
| Routed model stack | Balances quality and efficiency | Needs evaluation and monitoring |
| Model plus retrieval/tools | Grounded, current task performance | More system components to secure |
| Model plus human review | Safer high-stakes outcomes | Slower, requires clear handoffs |
⏱️ 13. Latency Is Part of Answer Quality
An answer that arrives after the user has moved on is often a poor answer in practice. Latency matters especially in interactive interfaces, agent assistance, live creation tools, and high-volume operations.
Reduce perceived waiting time by streaming text where appropriate, showing useful progress states, retrieving documents in parallel, caching stable results, and doing lightweight tasks before invoking a larger model.
Be cautious with premature streaming for structured data or sensitive actions. Validate the complete result before displaying a final decision or executing a consequential tool call.
🧭 14. Long Context Is Useful, Not Magical
A model that accepts a large amount of text can review lengthy documents or repositories, but stuffing everything into the prompt is rarely the best method. More context can increase cost, slow responses, distract the model, and bury the relevant evidence.
First, select the most relevant material. Then organize it with clear titles, source identifiers, and separators. Ask questions that force the model to distinguish supplied evidence from assumptions.
Sources are separated below. Compare only the stated requirements.
For each conclusion, name the source section that supports it.
If sources conflict, describe the conflict instead of choosing silently.

=== Source A ===
...
=== Source B ===
...
Test “needle in a haystack” cases: place an important detail among realistic irrelevant text and see whether the model finds and uses it correctly.
🔁 15. Iteration Beats One-Shot Perfection
For complex tasks, a dependable workflow often uses stages. One step extracts facts, another creates a draft, another checks requirements, and a final step presents the answer.
Breaking work apart can make errors easier to locate. It also lets you use a small model for routine extraction and save expensive reasoning for the synthesis step.
- Retrieve or collect trusted inputs.
- Extract facts into a defined structure.
- Generate a draft from those facts.
- Check the draft against rules and source material.
- Escalate uncertain or high-impact cases.
More steps are not always better. Every handoff can introduce errors, latency, and complexity, so keep only the stages that demonstrably improve your evaluation results.
🧑💻 16. Developers: Instrument Failures from Day One
Production AI quality cannot be managed from a demo alone. Log enough information to reproduce failures while minimizing retention of sensitive content.
At a minimum, record model identifier, prompt template identifier, task category, latency, token or usage metrics where available, tool calls, validation result, fallback path, and human feedback. Follow your organization’s privacy rules when storing inputs and outputs.
event = {
  "task_type": "invoice_extraction",
  "prompt_template": "extract_v3",
  "model_tier": "fast",
  "validation_passed": true,
  "fallback_used": false,
  "latency_ms": latency,
  "human_correction": null
}
log(event)
Review samples regularly. A rising validation-failure rate, a new user phrasing pattern, or an updated source document can quietly change performance.
🛡️ 17. Bigger Models Do Not Remove Privacy or Safety Risks
Model capability does not eliminate the need for responsible system design. Any model can expose sensitive information if you send it data without proper controls, follow malicious instructions embedded in documents, or give it excessive tool permissions.
Apply data minimization: send only the content needed for the task. Redact identifiers where possible, establish retention rules, and verify the provider and deployment controls appropriate for your requirements. Details vary, so consult official documentation and your security team.
- Keep secrets, access tokens, and unnecessary personal data out of prompts.
- Treat retrieved documents and web content as untrusted input.
- Require confirmation before irreversible external actions.
- Use least-privilege credentials for every tool.
- Provide a human escalation path for consequential decisions.
Never present AI output as professional medical, legal, financial, or safety advice without appropriate expert review and clear boundaries.
🚫 18. Common Model-Selection Mistakes
The most frequent mistake is asking, “Which model is best?” The better question is, “Which system produces acceptable outcomes for this task under our constraints?”
- Buying capacity before defining a task: write the rubric first.
- Testing only happy paths: include typos, ambiguity, missing data, and adversarial inputs.
- Trusting fluent language: assess correctness separately from style.
- Ignoring formatting failures: validate outputs programmatically.
- Using self-confidence as a score: compare against evidence and outcomes.
- Never revisiting the choice: rerun evaluations as prompts, data, and models change.
A model can sound certain and still be wrong. In many real products, a clearly phrased “I don’t have enough information” is a higher-quality outcome than a polished fabrication.
📋 19. A Practical Evaluation Scorecard
Create a scorecard that reflects your actual workflow. Weight the categories according to risk: a casual writing assistant can prioritize style, while a compliance workflow may prioritize factual grounding and correct abstention.
| Category | Question to ask | Example evidence |
|---|---|---|
| Task accuracy | Did it reach the right result? | Expected-label match or expert review |
| Grounding | Did it use supplied evidence correctly? | Source citation and claim check |
| Format reliability | Can software consume the result? | Schema validation rate |
| Safety | Did it refuse or escalate appropriately? | Red-team and policy cases |
| Latency | Is it responsive enough? | End-to-end timing |
| Cost | Is the outcome worth the resources? | Cost per successful task |
Use this scorecard to compare model-and-system combinations, not just bare models. A modest model with excellent retrieval and validation can be the winner.
✅ 20. Quick-Start Checklist
- Define what “good” means for one specific task.
- Create a privacy-safe test set with easy, typical, and difficult examples.
- Test at least one smaller and one stronger model using the same prompt.
- Measure accuracy, formatting, latency, cost, and failure behavior.
- Add retrieval when the task depends on current or proprietary knowledge.
- Add schema validation before automation acts on an answer.
- Route straightforward tasks to faster capacity and escalate exceptions.
- Log outcomes, review failures, and rerun evaluations regularly.
- Minimize sensitive data and limit tool permissions.
- Keep humans in the loop for high-impact decisions.
A larger AI model can give better answers, but the best answer usually comes from matching the right level of capability to a well-designed task, reliable information, and meaningful checks. 🤖⚙️✨