
AI is becoming a normal part of daily work: drafting code, summarizing meetings, searching documents, generating images, classifying support tickets, and powering products. For many of these jobs, sending a prompt to a cloud model is the fastest way to begin. But it is not always the best architecture.
Running a model locally means inference happens on hardware you control: a laptop, workstation, on-premises server, edge device, or private machine in your own environment. The model may be open-weight or internally deployed, but the important distinction is that data and computation do not have to leave your chosen boundary.
The local-versus-cloud decision is no longer just for infrastructure teams. It affects privacy, reliability, latency, recurring cost, developer workflow, and what kinds of products creators and companies can responsibly build.
After reading, you will be able to evaluate a workload, choose an appropriate deployment pattern, test a local model safely, estimate the real trade-offs, and avoid treating “local” as either a magic privacy switch or a universal replacement for cloud AI.
🧭 1. Start With the Real Decision
The question is not simply, “Is local AI better?” A better question is: where should this specific model run for this specific task?
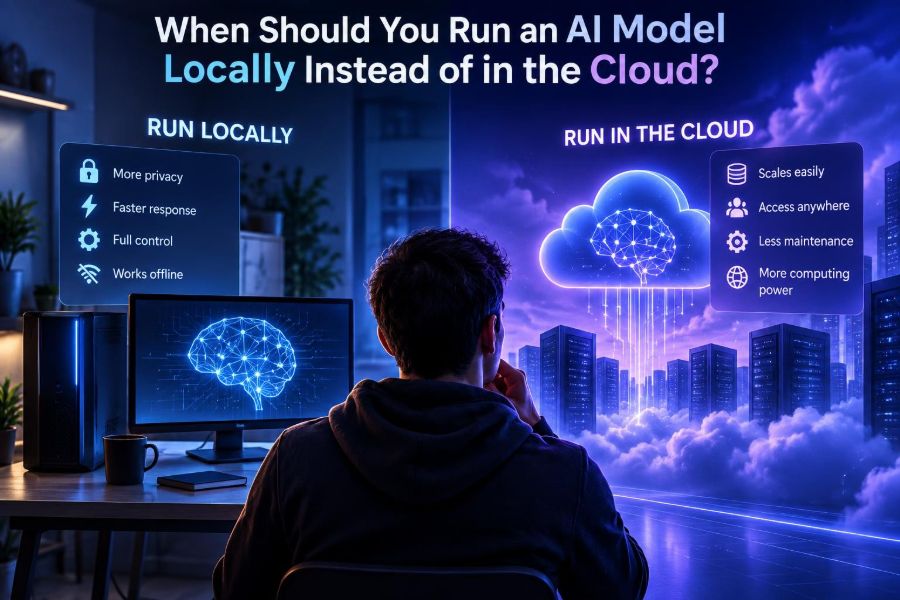
Cloud AI usually means an application sends a request to a provider-operated service over a network. Local AI means the request is processed on your device or infrastructure. A private cloud or virtual private deployment sits between these extremes: it can offer dedicated controls without physically running on your desk.
| Deployment | Best shorthand | Typical strength | Typical trade-off |
|---|---|---|---|
| Public cloud API | Use a managed remote model | Fastest access to capable models | Network dependency and data-sharing review |
| Local device | Run on a laptop or desktop | Privacy, offline operation, low local latency | Limited hardware and model size |
| On-premises server | Run in your organization’s environment | Control with shared capacity | Operations and hardware responsibility |
| Private hosted environment | Dedicated controlled cloud setup | Flexible scale and governance options | Still requires vendor and network trust |
| Hybrid routing | Choose per request | Balanced capability and control | More design complexity |
🔒 2. Choose Local When Data Cannot Comfortably Leave
The strongest reason to run locally is often not performance. It is that prompts, uploaded files, retrieved passages, tool outputs, and generated responses may contain information that should remain in a tightly controlled environment.
Examples include patient information, legal case files, source code, unreleased designs, financial records, security logs, internal strategy, and private creative work. Even if a provider offers strong protections, some organizations have contractual, regulatory, customer, or risk-management reasons to minimize external processing.
- Ask what enters the prompt: names, identifiers, document text, database results, screenshots, and tool outputs all count.
- Ask what leaves the model: generated answers can expose source material or sensitive inferences.
- Map the full path: client logs, proxies, observability tools, vector databases, backups, and support tooling can matter as much as the model endpoint.
- Read the current terms: retention, training use, regional processing, encryption, and enterprise controls can change. Verify them in the official documentation and your agreement.
Local operation reduces exposure, but it does not automatically create compliance. You still need access control, disk encryption, audit logging, retention rules, secure backups, and a policy for downloaded models and documents.
📡 3. Choose Local When the Network Is the Weak Link
A cloud request depends on connectivity, DNS, routing, provider availability, authentication, and an external service limit. In a warehouse, aircraft, field site, secure facility, remote studio, or unreliable home connection, that chain may be unacceptable.
Local inference can keep a transcription tool, image classifier, coding assistant, or document search system useful when offline. It also makes an application more resilient during a provider outage or an internet disruption.
Be precise about “offline.” A local model may work without the internet after installation, but your application might still call cloud analytics, license checks, embeddings, search, or update services. Test the actual workflow with networking disabled.
Offline readiness test

1. Download the model, tokenizer, and any required runtime files.
2. Cache test documents and dependencies locally.
3. Disable network access for the application environment.
4. Run a representative task from start to finish.
5. Record every failed request or missing asset.
6. Document an update process for the next connected window.
⚡ 4. Understand Latency Beyond “Fast”
For interactive features, the first visible token often matters more than total generation time. A cloud model can be highly capable yet feel slow because every interaction adds network round trips, queueing, and request setup.
A local model can start responding quickly because the request is already nearby. This is especially valuable for voice interfaces, autocomplete, live translation, real-time vision, industrial control, and creative tools where people repeatedly adjust a result.
But local is not inherently faster. A small model on a modern workstation may be responsive; a large model forced onto insufficient memory can be painfully slow. Compare end-to-end experience, not an isolated model metric.
- Measure time from user action to first useful output.
- Measure total completion time for a typical response.
- Test under concurrent users, not just one prompt.
- Include retrieval, document parsing, tool calls, and UI rendering.
💸 5. Calculate Cost as a Workload, Not a Sticker Price
Cloud services usually turn AI spending into a variable operating cost. Local deployment shifts more cost upfront: devices, accelerators, electricity, cooling, setup time, monitoring, replacement hardware, and the people who maintain it.
Local AI can become economical for steady, high-volume, predictable workloads. It can be wasteful for occasional use, rapidly changing needs, or workloads that need the largest available models only a few times a month.
Use a simple comparison before buying hardware:
Monthly cloud cost = requests per month × average cost per request

Monthly local cost =
(hardware cost ÷ expected useful months)
+ electricity
+ hosting or rack costs
+ maintenance labor
+ monitoring and backup costs
+ cost of capacity that sits idle
Do not omit engineering time. A managed endpoint can be the cheaper option when it lets a small team ship safely. Conversely, a local server can save money only if utilization is high enough to justify its ownership burden.
🧠 6. Match Model Size to Task Difficulty
The best local model is often not the largest model you can squeeze into memory. It is the smallest model that reliably completes the task at the quality bar your users need.
Narrow tasks such as classification, extraction, intent routing, structured formatting, basic summarization, or retrieval-grounded question answering can work well with compact models. Open-ended reasoning, nuanced writing, complex coding, multilingual work, and difficult visual generation may benefit from larger or specialized cloud models.
Create an evaluation set before choosing. Include normal examples, edge cases, adversarial inputs, short and long documents, and outputs that a domain expert considers unacceptable.
Evaluation record

Input: Support message with account details removed
Expected: Billing / urgent / needs human review
Model output: Billing / urgent / needs human review
Pass: Yes
Notes: Correctly avoided inventing a refund promise
Ten carefully selected examples are better than choosing a model based on a single impressive demo. Expand the set as you learn from production failures.
🖥️ 7. Check Your Hardware Before Downloading a Model
Local models need memory for model weights, runtime overhead, prompt context, generated tokens, and sometimes multiple simultaneous requests. The main practical constraints are usually system RAM, accelerator memory, storage speed, and cooling.
Quantization reduces memory use by representing weights with fewer bits. It can make local deployment practical, though quality and speed effects depend on the model, runtime, and task. Test the exact combination you plan to ship.
| Hardware situation | Good local starting point | Watch for |
|---|---|---|
| Everyday laptop | Small text model, lightweight embeddings, transcription | Thermal throttling and battery drain |
| Developer workstation | Interactive chat, coding helper, document workflows | Memory pressure from other applications |
| Server with accelerators | Team service, batch processing, multi-user inference | Scheduling, isolation, power, and operations |
| Edge device | Vision, sensor analysis, command recognition | Model footprint, heat, and update reliability |
Run a realistic test with your longest intended context and your expected concurrency. A model that answers a one-line prompt can fail when fed a long contract plus retrieved context.
🧰 8. Pick a Local Runtime That Fits Your Goal
Local AI tooling broadly falls into three groups. Desktop applications make experimentation easy. Developer runtimes expose local APIs for building features. Server-oriented inference systems focus on throughput, batching, observability, and multi-user deployment.
Choose based on the job, not popularity. A creator may want a graphical interface and simple model downloads. A developer may want an HTTP endpoint compatible with an existing app. A platform team may need authentication, metrics, model lifecycle controls, and request queues.
- Desktop tool: best for private personal workflows and evaluation.
- Local API runtime: best for prototypes, automations, and developer integrations.
- Inference server: best for shared internal applications.
- Specialized runtime: best when targeting a particular accelerator, mobile device, or edge environment.
Tool capabilities evolve quickly. Check official compatibility information for your operating system, hardware, model format, license, and API behavior before committing to an architecture.
🧪 9. Run Your First Local Experiment Step by Step
Keep the first experiment deliberately small. Your goal is not to recreate a full cloud platform; it is to discover whether a local model can meet one valuable requirement.
- Choose one task, such as summarizing private notes or classifying incoming messages.
- Define success in plain language and collect a small, sanitized evaluation set.
- Install a trusted local runtime from its official source.
- Download a model whose license permits your intended use.
- Run the same test prompts locally and with your current baseline.
- Record quality, first-response latency, total latency, memory use, and failures.
- Decide whether to keep local, use cloud, or route selectively.
A useful initial prompt makes constraints explicit:
You are a careful internal document assistant.
Summarize the text in five bullets.
Separate facts from recommendations.
If the text does not support an answer, write: "Not supported by the document."
Do not add external facts.

Document:
[PASTE TEXT HERE]
🧩 10. Use Retrieval Instead of Stuffing Everything Into Context
Many local projects fail because they try to place an entire knowledge base into every prompt. That consumes memory, slows generation, and makes answers less focused.
Retrieval-augmented generation, often called RAG, finds relevant chunks first and provides only those chunks to the model. The embedding model, vector index, source documents, and language model can all remain local if required.
Basic local RAG flow

1. Split approved documents into small, labeled chunks.
2. Create embeddings for each chunk locally.
3. Store embeddings and metadata in a local index.
4. Embed the user question.
5. Retrieve the most relevant chunks.
6. Ask the language model to answer only from those chunks.
7. Return source labels or citations to the user.
Common mistake: treating retrieval as truth. Retrieved text can be outdated, irrelevant, maliciously written, or incomplete. Require the model to identify uncertainty and show users the source material when the decision matters.
🧑💻 11. Build an App That Can Switch Providers
A provider-neutral interface gives you options. You can begin with a cloud endpoint, test a local endpoint later, and route sensitive requests locally without rewriting your entire product.
Keep your application’s business logic separate from provider-specific request formats. Normalize messages, tool schemas, response text, usage metadata, and error handling in one adapter layer.
function generateReply(request, policy) {
  if (policy.containsSensitiveData || policy.mustWorkOffline) {
    return localModel.generate(request);
  }

  if (policy.needsHighestCapability) {
    return cloudModel.generate(request);
  }

  return localModel.generate(request);
}
This is illustrative pseudocode, not a security policy. In production, add authorization, rate limits, input validation, timeouts, logging rules, model version tracking, and a safe fallback when a chosen route is unavailable.
🛣️ 12. Adopt Hybrid Routing for the Best of Both
Hybrid architecture is often the practical answer. Use local models for routine, sensitive, low-latency, or offline tasks. Use cloud models for difficult requests, burst capacity, specialized modalities, or tasks where the quality gain clearly justifies external processing.
For example, an internal assistant can classify a request locally, redact identifiers locally, retrieve private documents locally, and send only an approved abstracted question to a cloud model when policy allows.
- Route based on sensitivity labels, not a user’s vague preference.
- Route based on task complexity using tests, not assumptions.
- Let users know when a task may use an external service.
- Provide a local-only mode where the use case requires it.
- Log routing decisions without storing sensitive prompt contents unnecessarily.
Do not build hybrid routing before you can measure it. A simple two-route system with clear policy is safer than an opaque “smart router” nobody can audit.
🛡️ 13. Treat Local AI as a Security System
Local inference removes one category of exposure, but it also makes you responsible for more of the stack. A workstation hosting private models may contain valuable weights, prompts, retrieved files, credentials, and generated artifacts.
Apply standard security practices:
- Use full-disk encryption and encrypted backups.
- Restrict who can call a local API; do not expose it broadly on a network by default.
- Run services with least privilege and separate service accounts.
- Verify model files, dependencies, and containers from trusted sources.
- Patch the operating system, runtime, and application dependencies.
- Protect logs, which may accidentally preserve prompts and responses.
- Set limits on file uploads, context size, generation length, and tool access.
Prompt injection still applies locally. A malicious document can instruct a model to reveal context, ignore rules, or call tools dangerously. Treat model output as untrusted input, especially before executing code, sending email, changing records, or accessing files.
⚖️ 14. Review Licenses, Safety, and Human Accountability
“Downloadable” does not always mean unrestricted. Model licenses can govern commercial use, redistribution, attribution, use cases, or derivative work. Dataset and embedding-model terms may matter too.
Local models can hallucinate, reflect bias, produce unsafe instructions, and misunderstand context just as cloud models can. If the output affects employment, healthcare, finance, education, safety, legal matters, or access to services, build human review and appeal paths into the workflow.
A strong rule is simple: privacy of processing does not guarantee correctness of output. Evaluate harms, define who is accountable, and avoid presenting probabilistic generations as verified facts.
📊 15. Monitor Quality Without Collecting Everything
Cloud products often provide dashboards by default. With local deployment, you must intentionally design observability. That is a benefit when done carefully: you can collect the minimum signals needed to improve the system.
Track operational metrics such as request counts, error rates, queue time, first-token latency, total duration, memory use, and hardware temperature. Track product quality with opt-in ratings, reviewer samples, and structured error categories.
For sensitive workflows, store redacted traces or short-lived encrypted records rather than full prompts forever. Document who can inspect evaluations and how users can report a harmful or incorrect output.
🚫 16. Avoid These Common Local-AI Mistakes
- Buying hardware before defining a task: start with an evaluation and workload estimate.
- Assuming no internet means secure: local services, logs, downloads, and backups still need controls.
- Using a giant model for simple extraction: small structured systems are often cheaper and more reliable.
- Ignoring licenses: validate use rights before prototypes become products.
- Comparing only one prompt: use a representative test set and repeat it after changes.
- Exposing a local endpoint to the internet: keep it private unless you have proper authentication and network protections.
- Automating irreversible actions: add confirmation and human review for high-impact tools.
- Forgetting updates: models, runtimes, drivers, and policies need a maintenance plan.
✅ 17. Use This Quick-Start Checklist
- Identify one workload with a clear privacy, latency, offline, cost, or control requirement.
- Classify the data that enters prompts, retrieval, logs, and outputs.
- Write down quality requirements and failure conditions.
- Build a small, sanitized evaluation set with real-world edge cases.
- Test a local runtime and a suitable compact model on your actual hardware.
- Measure end-to-end latency, memory use, quality, and operational effort.
- Check model and tool licenses for your intended use.
- Secure the host, local API, model files, logs, and backups.
- Choose local, cloud, private hosting, or hybrid based on evidence.
- Re-evaluate as traffic, regulations, hardware, and model capabilities change.
Run AI locally when control over data, availability, latency, or predictable high-volume economics outweighs the convenience and peak capability of a managed cloud service. For many teams, the most capable strategy will be a deliberate hybrid: local where boundaries matter, cloud where it earns its place. 🔐🧠⚡