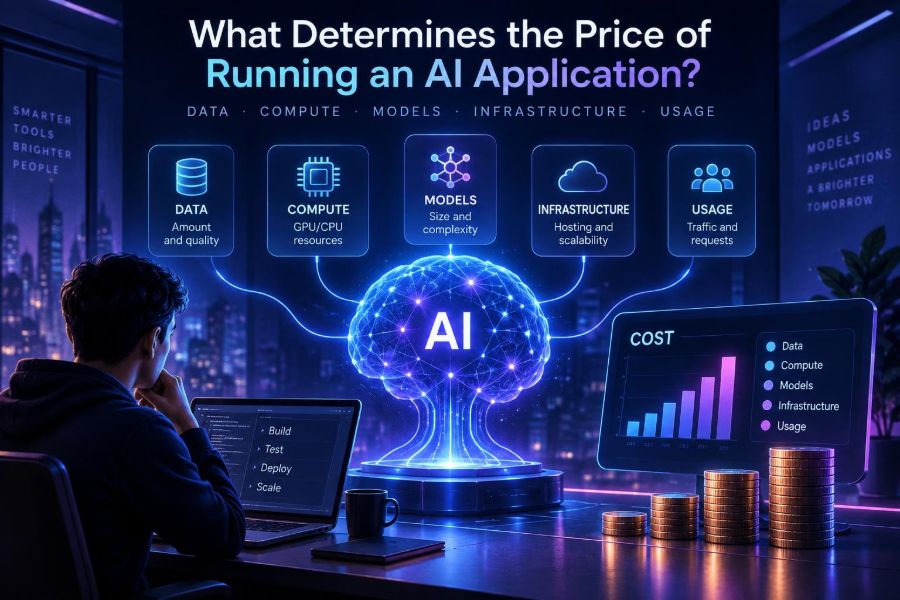

AI applications can feel inexpensive during a prototype and surprisingly costly after launch. A chatbot, document assistant, image generator, or autonomous workflow may call a model thousands of times a day, retrieve data, store conversation history, run safety checks, and send results through other services.
The important question is not simply, “What does the model cost?” The real cost is the combined price of every step required to turn a user action into a useful, reliable answer.
That matters now because AI features are moving from experiments into everyday products. Teams need to estimate budgets, select an architecture, set limits, and make sensible trade-offs before usage grows.
After reading, you will be able to map an AI application’s cost drivers, calculate a practical per-request estimate, identify waste, and choose optimizations that protect both quality and user experience.
🧾 1. Think in Cost per Successful Outcome
A model request has a visible usage charge, but that is only one part of the bill. An AI product also uses application servers, databases, retrieval systems, storage, monitoring, security controls, and people who maintain it.
A useful framing is cost per successful outcome. For a support assistant, that might mean the cost of resolving a customer question. For a writing tool, it could mean the cost of a completed draft that the user accepts.
cost per successful outcome = total operating cost / number of useful completed outcomesThis metric prevents a misleading optimization: choosing the lowest-cost model even when it causes failures, retries, escalations, or unhappy users.
- Measure model usage and infrastructure separately.
- Track failures, retries, and abandoned sessions.
- Compare cost with quality signals, not cost alone.
🔤 2. Tokens Are the Main Meter for Language Models
For many text-based AI applications, usage is measured in tokens, small chunks of text that models read and generate. A word may be one token, multiple tokens, or part of a token depending on the language and tokenizer.
Providers commonly distinguish between input tokens and output tokens. The input includes your instructions, user message, examples, retrieved documents, tool results, and conversation history. The output is what the model generates.
Input: system instructions + chat history + user question + retrieved context
Output: model answer + structured fields + tool-call arguments
Output can be especially important because long answers cost more, take longer, and can encourage users to ask follow-up questions. Check your chosen provider’s current pricing and tokenization guidance because rates and product options change frequently.
📏 3. Context Length Quietly Expands Every Request
Context is everything placed in the model’s current working input. It is tempting to include the entire chat, every policy document, and all available customer records “just in case.” That creates repeated cost on every turn.
Consider a conversation with 20 previous messages. If you resend all 20 messages for each new question, the same old text is billed and processed again and again.
Use a deliberate context policy:
- Keep the latest turns that are directly relevant.
- Summarize older conversation into a compact memory.
- Retrieve only the documents needed for the current question.
- Set a token budget before sending the request.
Conversation memory:
- User runs a small online store.
- Preferred answer style: concise, practical.
- Current task: improve product-return response.

Latest messages:
[only the most recent relevant turns]
A summary is not perfect memory, so retain the original conversation securely when your product needs auditability or users need to review prior exchanges.
🧮 4. Estimate the Cost of One Request
Start with a simple model. It will be imperfect, but it makes assumptions visible and gives you a number to improve.
request cost =
  (input tokens / 1,000,000 × input rate) +
  (output tokens / 1,000,000 × output rate) +
  retrieval cost +
  tool cost +
  infrastructure cost
Then include the requests that do not succeed the first time. If 10% of requests retry because of timeouts, malformed output, or user corrections, your effective cost rises.
effective request cost = average request cost × (1 + retry rate)| Cost component | What increases it | Useful control |
|---|---|---|
| Input tokens | Long prompts, chat history, large documents | Summarize and retrieve selectively |
| Output tokens | Verbose answers, unrestricted generation | Set output limits and formats |
| Retrieval | Many searches, large chunks, reranking | Use metadata filters and top-k limits |
| Tools | Search, APIs, code execution, transactions | Call tools only when needed |
| Infrastructure | Always-on capacity and slow workloads | Autoscale and queue background tasks |
🧠 5. Model Choice Is a Quality, Speed, and Cost Decision
Larger or more capable models can reason more effectively on difficult tasks, follow complex instructions, and produce stronger outputs. They can also cost more and take longer to respond.
Do not choose one model for every task by default. Classify your workload by the level of reasoning and reliability it needs.
- Small tasks: labeling, extraction, short summaries, routing, and simple rewriting.
- Medium tasks: grounded customer support, structured drafting, and document comparison.
- High-stakes or complex tasks: multi-step analysis, difficult coding, planning, and expert review assistance.
Run representative evaluations before changing models. Test real, privacy-safe examples and score factual grounding, format compliance, latency, safety behavior, and user acceptance.
🛣️ 6. Route Each Task to the Right Model
Model routing sends easy tasks to an economical option and reserves more capable models for requests that need them. A router can use explicit rules, a lightweight classifier, or a small model that categorizes the request.
if request.type == "intent_classification":
    use_economical_model()
elif request.has_sensitive_decision or request.requires_complex_reasoning:
    use_high_capability_model()
else:
    use_default_model()
Start with rules that your team can explain. For example, route a task to a stronger path when it involves a long document, multiple constraints, legal or medical language, a failed first attempt, or a user asking for detailed analysis.
A common mistake is routing purely by message length. A short request can still be difficult, while a long request can be routine extraction.
🗜️ 7. Design Prompts for Precision, Not Maximum Length
Every prompt should earn its tokens. Repeated background, duplicated instructions, and giant sets of examples can inflate costs while making behavior less predictable.
Write a compact instruction that specifies the task, boundaries, output format, and uncertainty behavior.
You classify incoming support requests.
Return JSON with: category, urgency, needs_human.
Use "unknown" when the message lacks enough information.
Do not invent account details.
For a user-facing answer, constrain length when a brief response is genuinely better.
Answer in no more than 120 words.
Use three bullet points at most.
If the source does not answer the question, say so clearly.- Remove instructions that duplicate product code.
- Use examples only for formats the model repeatedly gets wrong.
- Ask for concise outputs by default, with an expand option.
- Version prompts so cost and quality changes are traceable.
📚 8. Retrieval Adds Costs but Can Prevent Bigger Mistakes
Retrieval-augmented generation, often called RAG, finds relevant information from your knowledge base and supplies it to the model. It can reduce hallucinations and keep answers current without retraining a model.
Its costs include turning documents into embeddings, storing vectors, searching an index, optionally reranking results, and sending selected chunks to the model. The final step is often the largest recurring cost when chunks are oversized.
- Split documents into meaningful sections rather than arbitrary huge blocks.
- Add metadata such as product, region, date, permission level, and document type.
- Search with filters before broad semantic retrieval.
- Retrieve a small number of candidate chunks.
- Rerank only when search quality justifies the extra work.
- Pass the smallest evidence set that can answer the question.
Measure retrieval quality separately. If the wrong source is retrieved, more tokens will not reliably fix the answer.
🧱 9. Chunking and Top-K Control Your RAG Budget
A chunk is the unit of text stored and retrieved. Very small chunks can lose context and create many search results. Very large chunks can carry irrelevant text into every prompt.
Top-k is the number of retrieved candidates you send onward. Increasing it may improve recall, but it also raises input tokens and can distract the model with conflicting evidence.
search knowledge base with filters:
  product = "billing"
  audience = "customer"
  status = "published"

retrieve 8 candidates
rerank candidates
send best 3 short evidence chunks to model
Evaluate chunk size, overlap, top-k, and reranking together. There is no universal best setting; the right configuration depends on document structure and the questions users ask.
🔁 10. Multi-Step Agents Multiply Spend
An agent may plan, search, call tools, inspect results, revise a plan, and generate a final answer. Each loop can add model calls, tool calls, latency, and opportunities for failure.
Agents are valuable when tasks truly require variable, multi-step work. They are wasteful when a deterministic workflow would do.
| Approach | Best for | Cost behavior |
|---|---|---|
| Single model call | Simple drafting, classification, extraction | Predictable and usually lowest |
| Fixed workflow | Known steps such as retrieve, validate, answer | Controlled number of calls |
| Agent loop | Open-ended research or adaptive tool use | Variable; needs strict limits |
Set maximum steps, a time budget, a tool-call budget, and a clear stop condition. Log each step so expensive behavior is visible rather than mysterious.
MAX_STEPS = 4
MAX_TOOL_CALLS = 2

if steps >= MAX_STEPS or tool_calls >= MAX_TOOL_CALLS:
    return request_human_review_or_partial_answer()
🛠️ 11. External Tools Have Their Own Price Tags
AI applications often use web search, maps, payment systems, internal APIs, code sandboxes, email, and databases. A model may be inexpensive compared with the service it invokes.
Track tool cost as a first-class event. Include provider charges, compute time, database reads, and downstream effects such as creating support tickets or sending messages.
- Validate tool arguments before execution.
- Use read-only tools by default.
- Require confirmation before irreversible actions.
- Cache safe, repeatable lookups.
- Put spending caps on metered external services.
Never allow a model’s natural-language output to directly authorize a financial, security, or destructive action without deterministic checks.
⚡ 12. Latency Is Also a Financial Metric
Slow answers cost money indirectly. Users may resend a request, refresh a page, abandon a workflow, or contact human support. Long-running server processes and held connections can add direct infrastructure costs too.
Break latency into components: queue time, retrieval, model time to first token, streaming duration, tool calls, validation, and database operations. Measure percentiles, not just average response time, because slow edge cases shape the user experience.
Streaming can make an answer feel faster, but it does not necessarily lower token cost. Use it when early visible progress improves the experience, and still enforce output limits.
🗃️ 13. Caching Can Eliminate Repeated Work
Caching stores a prior result so you do not repeat identical or nearly identical computation. It is especially effective for stable system content, common questions, embeddings, document processing, and predictable tool results.
Use several forms of caching:
- Exact cache: reuse a response for an identical normalized request.
- Semantic cache: reuse a vetted answer for a meaningfully similar question.
- Embedding cache: avoid recreating vectors for unchanged text.
- Retrieval cache: store results for frequent searches with safe filters.
cache_key = hash(model + prompt_version + user_permission_scope + normalized_question)

if cache.has(cache_key):
    return cache.get(cache_key)
else:
    answer = generate_answer()
    cache.put(cache_key, answer, ttl="appropriate duration")
Do not let one user receive another user’s private data through a shared cache. Include tenant, permission, region, and content-version boundaries in the cache design.
📦 14. Batch Work Whenever a User Does Not Need an Instant Answer
Real-time generation is appropriate for interactive chat and immediate assistance. Many workloads are not real-time: catalog enrichment, document tagging, nightly analytics, content moderation queues, and evaluation runs can be processed asynchronously.
Batching improves utilization and lets you control concurrency. It can also allow use of provider features designed for deferred workloads, where available; check official documentation for current capabilities and terms.
- Place jobs in a durable queue.
- Group compatible tasks by model, prompt, and priority.
- Set a worker concurrency limit.
- Retry transient failures with backoff.
- Send irrecoverable jobs to a review queue.
Separate urgent user work from background work so a large import cannot slow down your live product.
🧪 15. Test Quality Before and After Every Cost Change
Cost reduction is an experiment, not a guess. A shorter prompt, cheaper model, smaller retrieval set, or lower output limit can save money while silently harming quality.
Create a small evaluation set from representative, consented, and appropriately anonymized examples. Include easy requests, difficult ones, ambiguous queries, adversarial inputs, long documents, and cases where the correct response is “I do not know.”
Evaluation record:
- task category
- expected facts or constraints
- acceptable answer criteria
- safety requirements
- output format requirement
- human rating
- token count
- latency
- total request cost
Compare changes on both quality and economics. Keep a baseline, define a pass threshold, and roll out cautiously when an adjustment affects real users.
📊 16. Build Observability Into Every AI Call
You cannot manage what you cannot attribute. Log structured data for each request, while minimizing or redacting sensitive content.
- Request and session identifiers
- Model and prompt version
- Input and output token counts
- Retrieval document identifiers and chunk counts
- Tool calls, durations, and results
- Cache hits and misses
- Latency stages, errors, retries, and user feedback
Create dashboards for daily spend, cost by feature, cost by customer or tenant, cost per completed task, and high-percentile latency. Alerts should catch unusual volume, token spikes, retry storms, and runaway agent loops.
Good observability also makes product conversations more concrete: you can decide whether a popular expensive feature deserves investment rather than treating every AI cost as an unexplained overhead.
🛡️ 17. Privacy, Security, and Safety Affect the Budget
Responsible AI operations can add cost, but skipping them can create much larger legal, reputational, and operational risks. Sensitive data handling is part of system design, not an optional add-on.
Minimize the data sent to a model. Redact unnecessary personal information, enforce access controls before retrieval, define retention periods, and use providers and deployment options that fit your organization’s requirements.
- Do not place secrets, credentials, or unnecessary personal data in prompts.
- Defend tools against prompt injection and untrusted instructions.
- Apply permission checks outside the model, not only in prompt text.
- Use human review for high-impact decisions.
- Document what data is processed and why.
Review current provider policies, contractual terms, regional requirements, and internal security guidance before deploying sensitive workloads.
💸 18. Set Product Guardrails, Not Just Infrastructure Budgets
A monthly spending limit is useful, but it is too late if a single abusive session or bug burns through a large share of it. Build limits close to the request.
Per request: maximum input, output, and tool calls
Per session: maximum turns and total token budget
Per user: daily usage quota or credit balance
Per tenant: monthly budget alert and hard ceiling
Per feature: allowed models and fallback behavior
Design a graceful fallback for each limit. You might return a shorter response, defer a heavy job, ask the user to narrow a request, switch to a lower-cost path, or offer human support.
Be transparent when a limit changes what the product can do. Hidden degradation damages trust and creates more support work.
✅ 19. Quick-Start Checklist
- Define the successful user outcome your AI feature should produce.
- Calculate a baseline cost per request and cost per successful outcome.
- Log tokens, model calls, tools, retries, retrieval, latency, and cache behavior.
- Set input, output, tool, and agent-step budgets.
- Trim chat history and retrieve only relevant, permission-safe evidence.
- Route routine tasks to economical models and test the quality impact.
- Cache stable results and batch work that is not interactive.
- Build an evaluation set before changing prompts, models, or retrieval settings.
- Protect sensitive data and keep authorization outside the model.
- Review spend by feature and user value at a regular cadence.
The price of running an AI application is determined by the full system around the model, so the best savings come from thoughtful product and architecture decisions rather than blindly choosing the cheapest model. 🤖📈⚙️