
AI systems now recommend candidates, flag suspicious transactions, summarize medical records, prioritize customer tickets, and help creators make decisions. When an answer affects money, access, safety, or reputation, “the model said so” is not a useful explanation.
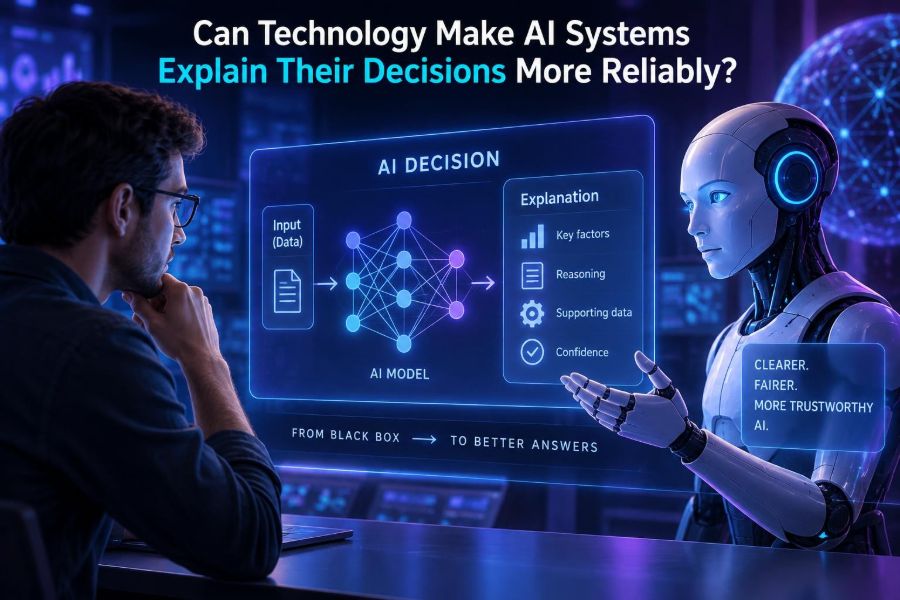
That gap has created a fast-moving field called explainable AI, or XAI. Its goal is not merely to make models sound convincing. It is to give people evidence they can inspect, challenge, reproduce, and use to make better decisions.
The timing matters because generative AI can produce polished rationales even when its underlying answer is wrong. A fluent explanation may be a post-hoc story rather than a faithful account of what drove the output.
After reading, you will be able to distinguish useful explanation methods from persuasive guesswork, add explanation checks to an AI workflow, choose techniques for different model types, and build a small evaluation harness for your own AI system.
🔍 1. What Does It Mean for AI to Explain Itself?
An explanation translates a model output into information a person can act on. For a loan-risk model, that could mean the features that most influenced a score. For a chatbot, it could mean the source passages supporting a claim and the steps used to verify them.
There is no single best explanation. The right form depends on who needs it and what decision they must make.
| Audience | Useful explanation | Typical action |
|---|---|---|
| Customer | Plain-language reasons and appeal path | Correct an error or request review |
| Analyst | Feature effects, evidence, uncertainty | Approve, reject, or investigate |
| Developer | Traces, test results, model behavior slices | Debug and improve the system |
| Auditor | Data lineage, logs, documented controls | Assess compliance and risk |
Explanation is not the same as transparency. A model can be open for inspection yet too complex to understand. Conversely, a closed model can provide useful evidence, citations, and audit logs without revealing every internal parameter.
🧠 2. Why a Good-Sounding Rationale Is Not Enough
Language models are trained to continue text plausibly. When asked “why did you decide that?”, they can generate a coherent answer that resembles reasoning without necessarily reporting the actual process that caused their output.
This is often called an unfaithful explanation. It can be dangerous because people naturally trust a detailed narrative more than a bare prediction.
- A model may cite a factor that sounds relevant but had no effect on its score.
- A chatbot may explain a conclusion using sources that do not actually support it.
- A system may expose a chain of steps while hiding uncertainty or a missing assumption.
Treat free-form rationales as user-interface content until you connect them to measurable evidence. The key question is not “does this explanation sound reasonable?” but “would the output change if the stated reason changed?”
⚖️ 3. The Three Tests: Faithfulness, Usefulness, and Stability
Reliable explanations should pass three practical tests. Faithfulness asks whether the explanation reflects model behavior. Usefulness asks whether the intended user can make a better decision with it. Stability asks whether small irrelevant changes cause wild swings in the explanation.
For example, suppose a classifier marks a support request as urgent because it mentions “locked out.” Remove that phrase and its urgency score should fall. If it does not, the explanation may be misleading.
- State the claim the explanation makes.
- Change or remove the cited evidence.
- Run the model again under the same conditions.
- Measure whether the predicted output changes in the expected direction.
- Record cases where the explanation and behavior disagree.
This simple intervention test is more valuable than asking a model to rate its own explanation.
🧩 4. Match the Explanation to the Model and Decision
Some AI systems are naturally easier to inspect. A small decision tree can show a sequence of rules. A large neural network or language model requires indirect tools, such as attribution, example retrieval, probes, or controlled experiments.
| System type | Strong starting approach | Watch for |
|---|---|---|
| Rules or decision trees | Decision path and rule review | Rules becoming too numerous |
| Linear model | Coefficient and feature-effect analysis | Correlated features misleading readers |
| Image model | Saliency maps and occlusion tests | Heat maps that look precise but are unstable |
| Tabular ensemble | Local feature attribution and counterfactuals | Attributions mistaken for causation |
| Retrieval-based chatbot | Claim-level citations and source verification | Irrelevant or unsupported citations |
| Generative workflow | Tool logs, structured outputs, evaluator checks | Invented intermediate reasoning |
Choose explanations based on the cost of a bad decision. A movie recommender can prioritize clarity and user control. A high-impact decision needs testing, review, and a human escalation route.
🧪 5. Start With an Explanation Contract
Before selecting a tool, write an explanation contract: a short specification of what the system must explain, to whom, and how it will be tested. This prevents teams from adding decorative explanations at the end of a project.
Decision: Flag an invoice for manual review.
Audience: Finance analyst.
Must show: top evidence, source fields, confidence range,
           and actions that could change the result.
Must not claim: fraud, intent, or causal certainty.
Validation: remove cited fields; verify score movement;
            sample explanations for analyst review.
Escalation: analyst can override and record a reason.
Make the contract visible in product requirements, model cards, and acceptance tests. If a team cannot state what an explanation should enable, it is unlikely to build one that matters.
📊 6. Use Feature Attribution Carefully
Feature attribution estimates how much each input contributed to a prediction. Common methods compare a prediction with a baseline, perturb features, or approximate each feature’s contribution across possible combinations.
For a tabular model, an explanation might say: “The risk score increased primarily because of repeated failed payments and a recent account change.” That is often useful for investigation, but it is not proof that either factor caused the outcome in the real world.
# Pseudocode: test an attribution claim
original = model.predict(invoice)
changed = invoice.copy()
changed["failed_payment_count"] = 0
counterfactual = model.predict(changed)

print({
  "original_score": original,
  "score_without_cited_feature": counterfactual,
  "change": original - counterfactual
})- Show the input value alongside each attributed feature.
- Use understandable baselines, not arbitrary zeros.
- Test correlated features together; one may stand in for another.
- Label attribution as model influence, not real-world causality.
🔄 7. Ask “What Would Need to Change?”
A counterfactual explanation describes a nearby input that would receive a different outcome. It answers a practical question: what changes could alter this result?
For example: “If verified monthly income were higher and debt were lower, the model would likely move this application into a different review category.” In a well-designed system, this can be more actionable than a ranked list of features.
Counterfactuals need constraints. Telling someone to change their birth year, neighborhood, or protected characteristic is useless and potentially harmful. Only propose feasible, lawful, and relevant changes.
Find the smallest allowed change that flips the decision.
Constraints:
- Never alter protected or immutable attributes.
- Keep values within realistic ranges.
- Change only fields the user can legitimately update.
- Return uncertainty if no reliable counterfactual exists.
Also check whether the suggested change truly flips the result when passed back through the production model. A generated counterfactual that cannot be reproduced is not an explanation; it is a broken promise.
🖼️ 8. Treat Visual Explanations as Hypotheses
In computer vision, saliency maps and heat maps attempt to show the regions associated with a prediction. They are useful for spotting obvious failures, such as a wildlife classifier focusing on a watermark instead of an animal.
But an attractive heat map is not automatically reliable. Some methods can produce similar-looking maps even when model parameters or labels are changed, which means visual plausibility alone is weak evidence.
- Generate a map for the original image.
- Mask the highlighted region and rerun the model.
- Mask a non-highlighted region of the same size.
- Compare confidence drops across many examples.
- Inspect difficult cases with domain experts.
The explanation becomes more credible when removing the highlighted evidence consistently affects the relevant prediction more than removing unrelated content.
📚 9. Ground Generative AI in Verifiable Evidence
For an AI assistant, the most useful explanation is often not an internal narrative. It is a trail from each important claim to the documents, database records, calculations, or tools that support it.
Build answers around claim-level grounding. A response should separate sourced facts, calculations, assumptions, and recommendations.
You are an evidence-first assistant.
For every material factual claim:
1. Cite the provided source ID immediately after the claim.
2. If no source supports it, say "Not supported by the supplied evidence."
3. Put assumptions in a separate section.
4. Show calculations with inputs and formula.
5. Never fabricate a citation or imply that a source says more than it does.
Then verify citations programmatically where possible. Check that a cited passage was actually retrieved, is relevant to the claim, and was current enough for the task. The exact implementation depends on your search stack, so consult your tool provider’s official documentation for current capabilities.
🧾 10. Make Outputs Structured Before Making Them Conversational
Free text is hard to evaluate consistently. A structured explanation schema lets an application validate required fields, block unsupported claims, and present information differently to users and auditors.
{
  "decision": "manual_review",
  "confidence": "medium",
  "evidence": [
    {"field": "payment_history", "observation": "3 failed payments", "source_id": "ledger_17"}
  ],
  "uncertainties": ["merchant category was unavailable"],
  "recommended_next_step": "verify merchant documentation",
  "human_review_required": true
}
Validate types, allowed values, source identifiers, and evidence completeness before displaying the result. Do not let an interface silently turn missing evidence into a confident prose explanation.
🛠️ 11. Build an Explanation Evaluation Harness
Evaluation should be a repeatable system, not a one-time demo. Create a small test set with ordinary examples, edge cases, known failures, and cases involving sensitive groups or contexts.
for case in evaluation_cases:
    result = system.run(case.input)
    assert result.decision in allowed_decisions
    assert all(e.source_id in case.available_sources for e in result.evidence)
    assert no_unsupported_claims(result.explanation)
    assert explanation_is_stable(case.input, result)
    log(case.id, result, reviewer_feedback=None)
Useful metrics include citation support rate, evidence coverage, intervention pass rate, explanation stability, override rate, and time-to-resolution for human reviewers. Track these by user segment and input type, not just as a global average.
🧯 12. Test for Shortcut Learning and Data Leakage
Models often discover shortcuts. A recruiting model may learn that a file format predicts a historical outcome. A medical image model might key off a scanner marker. A support model may associate a customer’s writing style with escalation rather than the underlying problem.
Create targeted tests that vary one suspected shortcut at a time. If an irrelevant change flips a decision, you have found either a robustness problem, leakage, or an explanation gap.
- Shuffle a suspected feature while holding meaningful features constant.
- Use matched pairs that differ only in irrelevant wording or formatting.
- Test data from a different time period or source.
- Review training labels for proxies and historical bias.
Explanations are especially valuable here because they can reveal the wrong reason for a correct-looking answer.
👥 13. Keep Humans in the Loop Where It Counts
Human review is not a magic safety layer. Reviewers can over-trust confident AI outputs, become fatigued, or lack the authority to override a system. A good workflow gives them evidence, context, and a clear responsibility.
Design the review screen around the decision, not the model. Show the original input, relevant evidence, uncertainty, alternative interpretations, and the reason an item was routed to review.
- Allow an override without requiring the reviewer to agree with the model.
- Require a short rationale for consequential overrides.
- Sample automated approvals for quality checks.
- Feed recurring override reasons into model and data improvements.
A useful rule: if a person cannot identify what evidence would make them disagree, they are not meaningfully reviewing the AI.
🔐 14. Protect Privacy While Explaining Decisions
More visibility can create more exposure. Logs, prompts, retrieved documents, and explanation dashboards may contain personal, confidential, or regulated data.
Apply data minimization to explanations just as you would to model inputs. Show users what they need, give investigators controlled access to more detail, and avoid exposing another person’s information as a reason for a decision.
- Redact sensitive fields before storing prompts and traces.
- Set retention periods for logs and evaluation datasets.
- Use role-based access for raw evidence and audit exports.
- Document which data sources are allowed in explanations.
- Test whether generated text leaks confidential context.
For regulated or high-impact use cases, involve legal, privacy, security, and domain experts early. Requirements vary by jurisdiction and application, so verify current obligations through appropriate official and professional guidance.
🚧 15. Know the Limits of Explainability Technology
Technology can make AI decisions more inspectable and contestable, but it cannot turn every complex model into a complete causal theory. Attribution tells you about a model’s behavior under a method’s assumptions; it does not automatically reveal truth, fairness, or intent.
Some trade-offs are unavoidable. A highly interpretable model may be less accurate for a task, while a more complex model may require stronger monitoring and narrower deployment. Sometimes the responsible choice is a simpler model, a restricted use case, or no automation at all.
Be skeptical of any product that promises a single “explainability score.” Reliability comes from layers: appropriate model design, quality data, evidence grounding, intervention tests, human governance, and ongoing monitoring.
✅ 16. Quick-Start Checklist
- Define the decision: write down what the AI is allowed to decide and what requires human approval.
- Name the audience: identify what each user needs to understand or challenge.
- Create an explanation contract: specify evidence, uncertainty, constraints, and escalation.
- Use structured outputs: separate decisions, evidence, assumptions, and recommendations.
- Test faithfulness: remove or alter cited factors and measure output changes.
- Verify sources: check every important generative-AI claim against retrieved evidence.
- Measure stability: test harmless wording, formatting, and data variations.
- Log responsibly: retain enough for audits without unnecessarily collecting sensitive data.
- Review overrides: turn human disagreement into evaluation cases and product improvements.
- Reassess continuously: models, data, policies, and real-world conditions change.
Technology can make AI explanations more reliable when teams treat them as testable evidence systems rather than persuasive stories. Build for challenge, verification, and correction—and your AI will be more useful when it matters most. 🤖🔎✨