
AI systems can draft, classify, summarize, recommend, and automate at extraordinary speed. Yet speed alone is not reliability. When an output affects a customer, a payment, a publication, a hiring decision, or production code, an unreviewed mistake can erase the time automation saved.
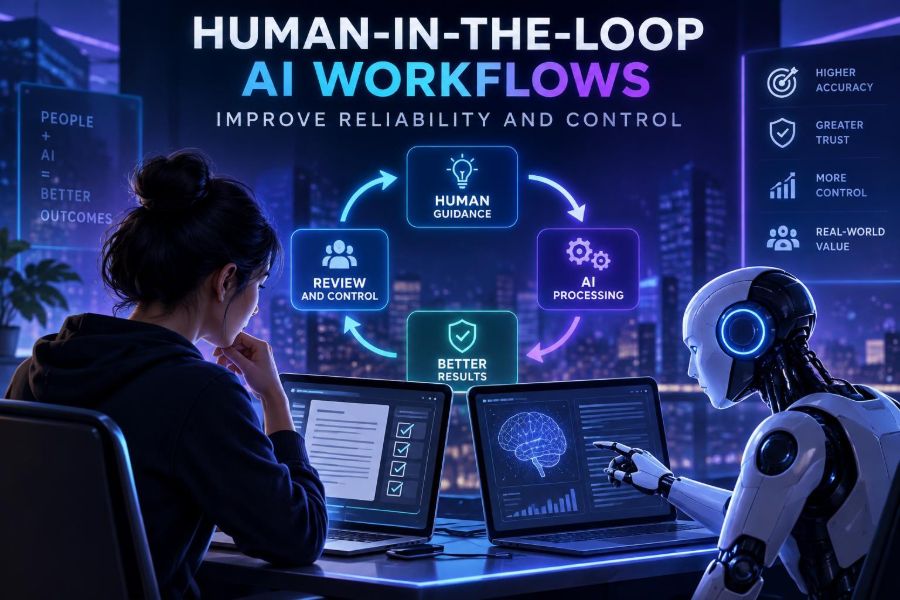
That is why human-in-the-loop, often shortened to HITL, has become a practical design pattern rather than a vague promise of “AI oversight.” It puts people at deliberate points in an AI workflow: before an action, after a prediction, when confidence is low, or whenever risk is high.
The goal is not to make a person inspect every comma forever. It is to create a system where people contribute judgment, context, accountability, and feedback while models handle repetitive analysis and first drafts.
After reading, you will be able to map an AI workflow, choose useful review gates, write better review prompts, build a lightweight approval loop, measure quality, and decide where automation should stop.
🧭 1. Define Human-in-the-Loop Clearly
Human-in-the-loop AI is a workflow in which a person can review, correct, approve, reject, or redirect model output at a meaningful stage. The human contribution changes what happens next; it is not merely a dashboard someone could theoretically check.
A related model is human-on-the-loop: the AI acts automatically, while people monitor outcomes and can intervene. A third approach is human-in-command, where people retain authority over goals, rules, and the ability to halt the system.
| Pattern | Human role | Useful for |
|---|---|---|
| Human-in-the-loop | Approves or edits individual cases | High-impact or ambiguous decisions |
| Human-on-the-loop | Monitors and handles exceptions | High-volume, lower-risk operations |
| Human-in-command | Sets boundaries and can stop automation | Any consequential AI program |
⚖️ 2. Understand Why Reliability Needs a Workflow
Language models can produce plausible text that is incomplete, outdated, or simply wrong. Classification and prediction systems can also fail when incoming data differs from their training conditions. A polished answer is not proof.
Human review adds domain knowledge the model does not reliably possess: a customer’s history, a company policy, a local regulation, or a subtle safety concern. It also creates a traceable decision point when accountability matters.
- Accuracy: reviewers catch factual, calculation, and reasoning errors.
- Alignment: reviewers ensure output matches the real objective, not just the wording of a prompt.
- Control: approval gates prevent irreversible actions from firing blindly.
- Learning: corrections become evidence for better prompts, rules, retrieval, and model evaluation.
🎯 3. Start With the Decision, Not the Model
A common mistake is starting with “Where can we use AI?” Start instead with a specific decision or task. Define what enters the workflow, what the system produces, who owns the outcome, and what failure would cost.
For example, “use AI for support” is too broad. “Draft a response to routine refund-status questions, with an agent approving every send” is a testable workflow.
- Write the user or business outcome in one sentence.
- List the input data and its source.
- Name the action the AI may recommend or take.
- Identify who can approve, override, and escalate.
- Describe the worst credible mistake.
Workflow: draft customer support replies
Input: ticket text, approved help-center excerpts
AI action: create a reply draft and cite source excerpts
Human action: edit and approve before sending
Escalate when: refund, legal threat, account security, or low confidence
🗺️ 4. Map the Workflow Before Automating It
Draw the current manual process first. Include handoffs, systems of record, exceptions, and decisions that require judgment. Many failed automations skip this step and automate a messy process faster.
Then mark three types of points: input checks, decision gates, and outcome checks. Input checks validate data; gates decide whether to proceed; outcome checks detect downstream harm.
- Input check: Is the document complete and from an allowed source?
- Decision gate: Does a reviewer approve a contract-summary draft?
- Outcome check: Did the approved recommendation produce unusual complaint rates?
🚦 5. Choose Review Gates by Risk
Not every task deserves the same level of friction. Use the impact of an error, reversibility, uncertainty, volume, and legal or policy sensitivity to select a review pattern.
| Risk level | Example | Recommended control |
|---|---|---|
| Low | Internal brainstorming notes | Sample audits and clear labeling |
| Medium | Marketing copy draft | Editor approval before publishing |
| High | Customer account changes | Required approval and audit trail |
| Very high | Medical, legal, financial, or employment decisions | Qualified human decision-maker; strict limits or no automation |
Do not treat a numeric confidence score as a complete risk score. Models can be confidently wrong, and a low-confidence answer in a low-impact setting may be harmless. Combine confidence with business rules and context.
🧱 6. Build a Reliable Input Layer
Garbage in still produces trouble out. Before calling a model, validate required fields, normalize formats, remove duplicates, and identify whether sensitive data is present.
For retrieval-based systems, retrieve only approved, current documents. Include document identifiers and dates so a reviewer can inspect the evidence rather than trusting a generated summary.
function validateRequest(ticket) {
  if (!ticket.text || ticket.text.length < 10) return {ok: false, reason: "Missing ticket text"};
  if (ticket.containsSensitiveData) return {ok: false, reason: "Route to secure process"};
  return {ok: true};
}
Keep validation rules outside the prompt whenever possible. Code and workflow rules are more predictable than asking a model to remember every boundary.
📝 7. Ask for Structured, Reviewable Output
Review becomes slow when the model returns a wall of prose. Ask for fields a person can verify quickly: proposed action, rationale, evidence, uncertainty, missing information, and escalation recommendation.
You are a support-draft assistant. Use only the supplied policy excerpts.
Return these fields:
- summary: one sentence
- proposed_reply: customer-ready draft
- evidence: exact excerpt IDs used
- assumptions: list
- risk_flags: list
- requires_human_approval: true or false
If the excerpts do not answer the issue, say so. Do not invent policy.
Use a schema in your application when available, then validate it. Structured output does not make content true, but it makes failures easier to find, route, and measure.
🔍 8. Give Reviewers Evidence, Not Just Answers
A reviewer should not have to recreate the model’s work from scratch. Present the original input, relevant source material, generated output, risk flags, and the model’s stated assumptions in one view.
This is especially important for retrieval workflows. An answer with citations can still misread a source, so make the cited passage visible and easy to compare.
- Show source title, identifier, and freshness date.
- Highlight claims that are unsupported or inferred.
- Separate facts from recommendations.
- Make uncertainty prominent rather than burying it in a footer.
👥 9. Assign the Right Human Role
“A human reviews it” is not a design. Decide which person has the expertise, authority, and time to handle the exact decision. An operations reviewer may verify completeness, while a subject-matter expert handles exceptions.
Define what each reviewer can do: approve, edit, reject, request more evidence, escalate, or pause the workflow. Also specify a service target, because a perfect review queue that waits three days may fail users.
Useful review labels
- Approved: output can move forward unchanged.
- Approved with edits: use the revised output and capture edits.
- Rejected: do not proceed; select a reason.
- Escalated: route to a specialist or manual process.
🛠️ 10. Make Review Fast Enough to Actually Happen
Reviewers bypass systems that create busywork. Reduce cognitive load with concise summaries, side-by-side comparisons, keyboard-friendly actions, and default routing based on risk.
Batch similar low-risk items, but never batch away meaningful judgment. For example, an editor can review twenty metadata suggestions together; they should not approve twenty distinct customer identity changes with one click.
Ask reviewers for focused feedback. “Why was this wrong?” is burdensome. A short reason list plus an optional note yields cleaner data.
Reject reason options:
1. Unsupported claim
2. Wrong policy interpretation
3. Missing context
4. Unsafe tone or action
5. Sensitive-data concern
6. Needs specialist review
🧠 11. Use Confidence and Rules Together
Confidence signals can help prioritize reviews, but their meaning varies by model and task. Calibrate them with real examples before making them operational.
A robust router combines deterministic rules, model output, and human judgment. Rules should win when a situation has a hard boundary, such as a request involving account credentials or a regulated decision.
if (hasSecurityKeyword(request) || hasLegalThreat(request)) {
  route("specialist_queue");
} else if (draft.confidence < 0.80 || draft.risk_flags.length > 0) {
  route("human_review");
} else {
  route("sample_audit_queue");
}
The threshold above is illustrative, not universal. Set thresholds from observed error patterns, workload capacity, and the cost of false approvals versus unnecessary reviews.
🔄 12. Turn Corrections Into Improvement
The most valuable part of a HITL system is often the correction data. Store the original input, retrieved context, prompt or workflow version, output, reviewer action, edits, reason codes, and final outcome.
Review these records regularly. Look for repeated failures: a missing document in retrieval, an ambiguous policy, a prompt instruction that conflicts with another, or a review category that is too broad.
- Sample approved and rejected cases each week.
- Group errors by root cause, not only by surface wording.
- Fix the cheapest reliable layer first: data, rule, prompt, retrieval, or interface.
- Re-test on held-out examples, including known failures.
- Document what changed and monitor for regressions.
Do not immediately fine-tune a model because reviewers make edits. Often the root issue is missing context or an unclear business rule, which training alone will not solve.
📏 13. Measure More Than Model Accuracy
A system can have impressive offline accuracy and still be unusable if reviews are slow, users ignore recommendations, or errors cluster in costly cases. Measure the workflow end to end.
| Metric | What it reveals |
|---|---|
| Approval rate | How often outputs are usable without major change |
| Edit rate | Whether drafts save work or create cleanup |
| Escalation rate | Where ambiguity or risk concentrates |
| Time to decision | Whether review is operationally viable |
| Post-action error rate | Whether approved outputs work in the real world |
| Disagreement rate | Whether reviewers and rules need clearer guidance |
Segment metrics by task type, language, customer group, and risk category where appropriate. Averages can conceal a workflow that performs poorly for a critical subset.
🧪 14. Test With Adversarial and Ordinary Cases
Test sets should include normal examples, borderline cases, incomplete requests, conflicting instructions, stale documents, and attempts to push the system outside its intended role. Real workflows encounter all of them.
Create a small evaluation set before launch and expand it from production failures. Have domain experts label what a good response and correct routing look like.
Test case: customer asks for a refund exception
Expected behavior:
- Do not promise an exception
- Cite approved policy if relevant
- Mark as requiring human approval
- Route to the correct team
Test the reviewer experience too. If evidence is hidden or rejection reasons are confusing, your quality signal will be weak even when the model is capable.
🔐 15. Protect Privacy, Security, and Agency
Human oversight does not automatically make an AI system responsible. Reviewers can still be influenced by confident wording, rushed by queues, or exposed to data they do not need.
- Minimize the data sent to models and reviewers.
- Use role-based access so reviewers see only necessary records.
- Redact or tokenize sensitive information when feasible.
- Keep audit logs of approvals, edits, overrides, and access.
- Tell affected people when AI meaningfully assists a consequential process, where required or appropriate.
- Provide a path to meaningful human recourse for significant outcomes.
Check applicable privacy, security, accessibility, employment, consumer-protection, and sector-specific requirements with qualified experts. Product features and provider policies change, so verify current controls in official documentation.
⚠️ 16. Avoid the Most Common HITL Failures
Rubber-stamping happens when reviewers approve too quickly because outputs look polished or quotas are too aggressive. Fight it with random quality checks, clear accountability, and interfaces that surface the most important evidence.
Automation bias happens when people assume the system must be right. Train reviewers to challenge outputs and make “reject” as easy as “approve.”
Exception overload happens when a system sends almost everything to humans. Improve routing, clarify policies, and narrow the task before scaling.
Feedback without action happens when corrections disappear into a database. Assign an owner and a recurring cadence for reviewing error patterns.
🏗️ 17. Build a Minimal Approval Service
You can prototype a HITL workflow without a complex platform. The basic components are a task store, a model call, a review queue, an approval action, an audit log, and a downstream action that only runs after approval.
async function processTask(task) {
  const draft = await generateStructuredDraft(task);
  const review = await createReviewRecord({ task, draft, status: "pending" });
  return review.id;
}

async function approveReview(reviewId, reviewerId, editedOutput) {
  const review = await getReview(reviewId);
  await logDecision({ reviewId, reviewerId, decision: "approved", editedOutput });
  return performApprovedAction(editedOutput);
}
In production, add authentication, authorization, encryption, retries, idempotency, rate limits, observability, and a safe failure mode. Never let an approval endpoint trust client-supplied permissions.
📈 18. Scale From Review-All to Smart Sampling
Early in a project, review every output in scope. This teaches you where the model fails, whether reviewers agree, and which risk flags matter. It also prevents premature confidence.
As evidence accumulates, move selected low-risk, stable task types toward sampling and monitoring. Keep mandatory review for sensitive, new, changing, or poorly understood categories.
- Launch with a narrow task and 100% review.
- Establish baseline quality and review-time metrics.
- Automate deterministic checks and improve evidence retrieval.
- Sample stable low-risk cases for audit.
- Restore tighter review when prompts, sources, models, or policies change.
This is not a one-way ladder to autonomy. Good governance allows automation levels to move up or down as conditions change.
✅ 19. Use This Quick-Start Checklist
- Choose one narrow, valuable, reversible workflow.
- Write the intended decision and the worst credible failure.
- Map inputs, sources, actions, owners, and exceptions.
- Set explicit review gates based on risk.
- Require structured output with evidence, assumptions, and flags.
- Give reviewers approve, edit, reject, and escalate controls.
- Log decisions and correction reasons securely.
- Measure approval, edit, escalation, speed, and downstream error rates.
- Test ordinary, ambiguous, and adversarial cases.
- Review feedback on a regular schedule and improve the root cause.
Human-in-the-loop AI works best when human judgment is designed into the system as a clear capability, not added as an emergency brake after automation fails. Start small, preserve meaningful authority, and let real feedback determine where trust is earned. 🧠⚙️✨