
Choosing an AI approach is no longer just a model-selection question. Teams can get surprisingly far with a well-designed prompt, but the same shortcut can become fragile when answers must use private documents, follow a repeatable format, trigger business actions, or operate over long-running tasks.
The hard part is that prompting, retrieval-augmented generation (RAG), fine-tuning, and AI agents solve different problems. They overlap enough to cause confusion, and using a more complex option too early can create unnecessary cost, latency, maintenance, and risk.
This matters now because AI features are moving from demos into customer support, internal search, document workflows, coding tools, creative production, and operations. A project needs an architecture that is testable, observable, and safe—not merely impressive in a chat window.
By the end of this guide, you will be able to diagnose your project’s real constraint, select the smallest approach that solves it, combine approaches sensibly, and build an evaluation path before committing engineering time.
🧭 1. Start With the Job, Not the AI Label
Describe the user’s job in plain language before naming a technique. “Build an agent” is not a requirement; “help account managers draft an accurate renewal summary from approved account records” is one.
Write down the input, desired output, source of truth, acceptable failure modes, and whether the system must take action. This exposes the actual technical need.
- Input: a customer question, a form, files, a database record, or a task queue.
- Output: free text, structured data, a classification, a recommendation, or an executed action.
- Truth source: model knowledge, supplied instructions, current documents, or connected systems.
- Risk: annoyance, wrong advice, financial loss, privacy exposure, or irreversible action.
A useful rule is simple: use the least complex architecture that reliably meets the requirement. Complexity should earn its place.
🧩 2. Learn the Four Building Blocks
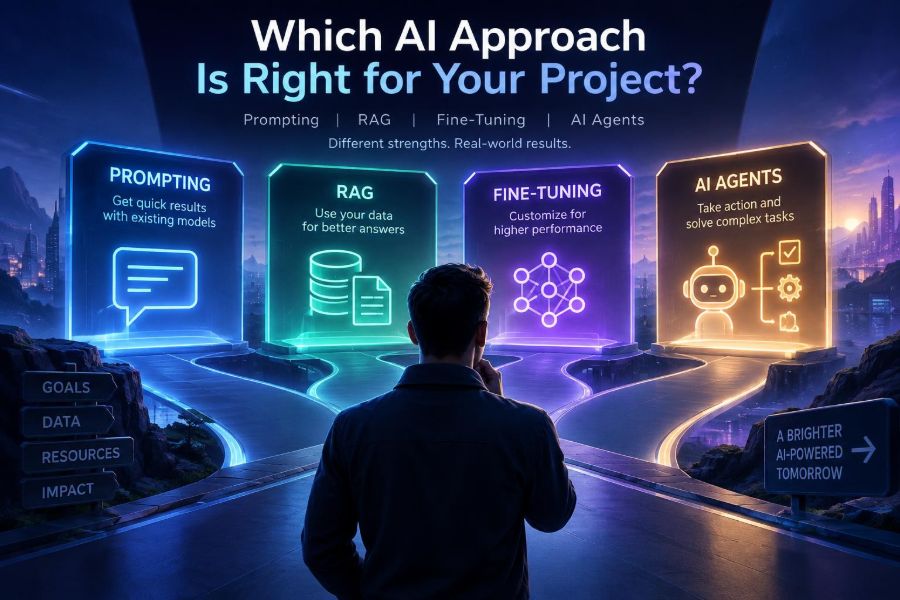
| Approach | Best at | Usually insufficient when |
|---|---|---|
| Prompting | Instructions, transformation, reasoning over supplied text, and small workflows | The model needs private, changing, or large factual context |
| RAG | Grounding answers in retrieved documents or records | The core need is a learned behavior, style, or reliable action sequence |
| Fine-tuning | Making repeated behavior, labels, formats, or domain patterns more consistent | Facts change often or need citations from current sources |
| AI agents | Planning and completing multi-step tasks with tools and state | One model call or a deterministic workflow is enough |
These are not mutually exclusive products. An agent may use prompting, RAG, and sometimes a fine-tuned model. Think of them as layers with different responsibilities.
🎯 3. Use Prompting for a Clear, Bounded Transformation
Prompting is your first option when the model can complete the task from general capabilities plus the text or data you send in the request. It is ideal for drafting, summarizing, extracting, rewriting, brainstorming, classification, and explaining.
A strong production prompt specifies a role, goal, context, constraints, output format, and fallback behavior. Do not assume the model knows what to do with ambiguity.
You are a support operations assistant.

Goal: Turn the customer message into a JSON triage record.
Use only the message below. Do not infer account facts.

Return fields: category, urgency, summary, needs_human_review.
Set needs_human_review to true if billing, safety, legal, or account access is involved.

Customer message:
"I was charged twice and cannot log in to update my payment method."
For many projects, the biggest improvement comes from adding representative examples and validating the output—not from changing the model.
🛠️ 4. Build a Prompt Baseline Before Adding Infrastructure
Create a baseline that runs on a small, realistic test set. Include easy examples, typical examples, edge cases, ambiguous inputs, and inputs that should be refused or escalated.
- Collect 20 to 100 examples from the real workflow, with sensitive data removed or protected.
- Define a pass condition for each example: factual accuracy, tone, required fields, or correct routing.
- Write one prompt with explicit instructions and examples where useful.
- Run the set repeatedly and record failures, latency, and cost.
- Classify each failure: missing knowledge, bad retrieval, inconsistent behavior, tool need, or unclear requirements.
This baseline prevents an expensive mistake: adopting RAG, fine-tuning, or agents when a better prompt and output validator would have solved the issue.
📦 5. Make Structured Output a Default for Software
Human-readable prose is often a poor interface between an AI model and an application. If software must route, save, calculate, or act on the result, ask for a constrained schema and validate it on the server.
const schema = {
  type: "object",
  required: ["priority", "owner", "reply"],
  properties: {
    priority: { enum: ["low", "medium", "high"] },
    owner: { enum: ["sales", "support", "security"] },
    reply: { type: "string" }
  }
};

const result = await model.generate({
  instructions: "Classify the request and draft a reply.",
  responseFormat: schema,
  input: ticketText
});
validateAgainstSchema(result);
Exact API shapes differ across providers, so check the official documentation for supported structured-output and tool-calling features. Regardless of provider, schema validation remains your responsibility.
📚 6. Choose RAG When Knowledge Is Private, Current, or Too Large
RAG retrieves relevant material at request time and places it in the model’s context. It is a strong fit for policy assistants, knowledge-base search, product documentation, research copilots, and systems that must answer from approved internal sources.
Use RAG when an answer should be based on facts that change, cannot be assumed to exist in the model’s training data, or must be attributable to selected documents. RAG changes the evidence available to the model; it does not magically make the model a perfect reasoner.
A good diagnostic question is: “If we updated this fact tomorrow, must the AI know it immediately?” If yes, retrieve it rather than training it into model behavior.
🗂️ 7. Build RAG as a Search System First
RAG quality is dominated by content and retrieval quality. Treat it as information retrieval with an AI answer layer, not as a single embedding step.
- Inventory source documents and assign an owner for each collection.
- Extract clean text, remove navigation clutter, and preserve titles, dates, permissions, and source identifiers.
- Split documents into meaningful chunks, keeping headings and nearby context together.
- Store chunks with metadata such as product, region, audience, effective date, and access rules.
- Retrieve candidates using semantic search, keyword search, or a hybrid of both.
- Filter by permissions and metadata before the model sees the content.
- Rerank the strongest candidates, then send a small, relevant evidence set to the model.
Chunk boundaries matter. A policy exception separated from its rule can produce a misleading answer even when the retrieval score looks good.
🔎 8. Ask RAG Answers to Show Their Evidence
Grounded generation needs a clear contract: answer from supplied sources, distinguish evidence from uncertainty, and decline to invent unsupported details. Give the user a way to inspect the document titles or internal source references where appropriate.
You answer questions using only the supplied sources.
If the sources do not support an answer, say: "I could not find this in the approved sources."
Do not use outside knowledge. Do not invent policy details.

For every factual claim, include the source ID in brackets.

Question: Can contractors access the analytics workspace?

Sources:
[POL-17] Contractors may access the workspace only when sponsored by a department owner...
[SEC-04] Workspace access requires multifactor authentication...
Do not confuse citations with correctness. A response can cite a weak or irrelevant chunk. Evaluate whether the cited evidence actually entails the answer.
🧪 9. Test Retrieval Separately From Generation
When a RAG answer fails, teams often blame the model. First determine whether the right source was retrieved. If not, rewriting the answer prompt will not fix the underlying problem.
Create a retrieval evaluation set with questions, expected documents, and permission context. Track whether the expected source appears among the top retrieved results, then evaluate answer faithfulness and completeness separately.
- Retrieval failure: the relevant passage never reaches the model.
- Grounding failure: the passage is present, but the answer contradicts or ignores it.
- Coverage failure: the corpus lacks the answer or contains stale material.
- Access-control failure: content is retrieved for someone who should not see it.
Hybrid search, metadata filters, improved chunking, and document cleanup often beat prompt tweaks. Measure changes against the same test set rather than relying on memorable demos.
🧠 10. Fine-Tune for Repeated Behavior, Not Fresh Facts
Fine-tuning adjusts a model using examples so it more consistently performs a target behavior. It can help with narrow classification, extraction conventions, specialized language patterns, stable response style, or following a compact output protocol at scale.
It is usually the wrong answer for a handbook that changes weekly, customer-specific account data, or a requirement to quote the newest policy. Those are retrieval and systems-integration problems.
Consider fine-tuning only after a prompt baseline shows a persistent pattern of failures and you have enough high-quality examples to define the desired behavior. If experts disagree on the answer, training data will encode that disagreement rather than resolve it.
🧹 11. Prepare Fine-Tuning Data Like a Product Asset
Training examples teach more than labels. They teach tone, assumptions, edge-case handling, and what “good” looks like. Poor examples can make a model confidently repeat poor decisions.
{"messages":[
  {"role":"user","content":"Classify: Please remove my account."},
  {"role":"assistant","content":"{\"intent\":\"account_deletion\",\"human_review\":false}"}
]}
{"messages":[
  {"role":"user","content":"Classify: I need a copy of all data you hold about me."},
  {"role":"assistant","content":"{\"intent\":\"data_request\",\"human_review\":true}"}
]}- Use reviewed examples from the actual distribution of requests.
- Include difficult and negative cases, not just clean successes.
- Keep a held-out test set that never enters training.
- Remove duplicates, contradictions, private fields, and outdated policies.
- Version the dataset, prompt, model configuration, and evaluation report together.
Fine-tuning can reduce prompt length or improve consistency, but it adds a lifecycle: data governance, retraining decisions, regression testing, and monitoring for drift.
⚙️ 12. Use an Agent Only When Tools and Iteration Are Necessary
An AI agent is a system in which a model chooses or helps choose steps, calls tools, observes results, and continues toward a goal. Examples include investigating an incident across systems, preparing a travel plan under constraints, or resolving a support task that requires looking up records and creating a follow-up.
Do not call every chatbot an agent. If the workflow always follows the same sequence, ordinary application code is simpler and safer.
Use an agent when the next step genuinely depends on what a tool returns, the task has multiple possible paths, and the value of flexible orchestration outweighs the added uncertainty.
🧱 13. Prefer Deterministic Workflows for Known Paths
A reliable pattern is a deterministic workflow with model-powered steps. Code controls the sequence, while the model handles interpretation, extraction, drafting, or choosing among a limited set of options.
const request = await classifyIncomingMessage(message);

if (request.intent === "refund_status") {
  const order = await getOrder(request.orderId);
  return draftStatusReply(order);
}

if (request.intent === "address_change") {
  return requestHumanVerification();
}

return routeToHumanSupport();
This pattern is easier to test than an open-ended loop. It also makes permissions, retries, timeouts, and audit logs explicit. Introduce autonomous planning only for the portion of the workflow that cannot be expressed as reliable rules.
🔐 14. Put Guardrails Around Tools and Actions
Tool access turns an AI mistake into a system-side effect. An agent that can send email, issue refunds, change permissions, run queries, or deploy code needs stronger controls than one that drafts text.
- Give each tool the minimum scope needed for the current task.
- Use typed parameters and server-side validation; never execute model-generated strings as commands.
- Require human approval for high-impact, external, or irreversible actions.
- Set spending, iteration, and time limits for every run.
- Log tool calls, inputs, outputs, approvals, and final outcomes.
- Design idempotent actions so retries do not duplicate charges, messages, or updates.
Also treat retrieved documents, web pages, emails, and user files as untrusted input. They can contain instructions intended to manipulate the model. Tell the model that source content is data, not authority to change system rules.
🧭 15. Use This Decision Framework
Walk through these questions in order. Stop at the first approach that resolves the actual constraint.
- Can a model perform the task with clear instructions and the user-provided input? Start with prompting.
- Does it need current, private, or extensive factual material? Add RAG.
- Does it repeatedly fail to follow a stable, demonstrable behavior despite a strong prompt and examples? Evaluate fine-tuning.
- Must it choose among tools and adapt a multi-step plan based on observations? Consider an agent.
- Are steps known in advance? Use a deterministic workflow with AI components instead of an agent.
For example, a marketing copy assistant usually starts with prompting. An internal benefits-policy assistant needs RAG. A high-volume labeler with a fixed taxonomy may justify fine-tuning. An operations assistant that investigates, drafts, and submits a ticket may need a constrained agent.
📏 16. Evaluate the Whole System Before Scaling
AI quality is multidimensional. A fluent answer can be inaccurate; a correct answer can be too slow; a useful workflow can be unsafe. Define metrics that match the user’s job.
| System type | Useful evaluation signals |
|---|---|
| Prompting | Task accuracy, format validity, tone, refusal quality |
| RAG | Source recall, citation entailment, answer completeness, access-control correctness |
| Fine-tuning | Held-out accuracy, consistency, regression rate, performance by subgroup |
| Agents | Task completion, tool error rate, unsafe-action rate, cost and steps per task |
Run evaluations before launch and continuously after it. Save anonymized failures for review, but obtain appropriate permission and follow retention rules. Production traffic changes, documents change, and model behavior can change when providers update systems.
🛡️ 17. Address Privacy, Security, and Human Oversight Early
Decide what data may enter a model request, retrieval index, log, or evaluation dataset. Minimize sensitive information, apply role-based access controls, and separate tenants where your application serves multiple organizations.
Check the official terms, data-handling controls, retention settings, and regional options of every model and infrastructure provider you use; these details change frequently. Legal, medical, financial, employment, and safety-sensitive use cases may require domain review and meaningful human oversight.
Give users a clear escalation path. A system should be able to say “I do not know,” explain its evidence boundary, and hand off difficult cases rather than manufacturing certainty.
✅ 18. Quick-Start Checklist
- Write one user job and one measurable definition of success.
- Build a prompt-only baseline on realistic examples.
- Add structured output and server-side validation for software workflows.
- Add RAG only when answers require current, private, or large knowledge sources.
- Evaluate retrieval independently before blaming generated answers.
- Fine-tune only for stable behavior supported by clean, reviewed examples.
- Use deterministic orchestration when steps are known; reserve agents for adaptive tool use.
- Constrain permissions, validate every tool call, and require approval for consequential actions.
- Track quality, cost, latency, privacy, and failures continuously.
The best AI architecture is not the most autonomous one; it is the simplest system that gives users dependable value with evidence, controls, and a clear path to improve. Start small, measure honestly, and add capability only when the project proves it needs it. 🤖📈🔒