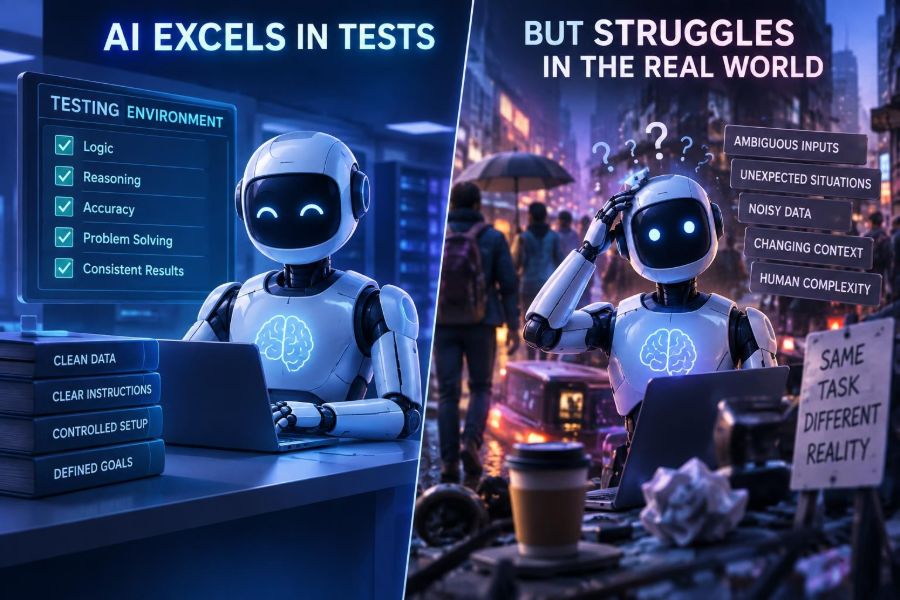

An AI demo answers a carefully chosen question, summarizes a clean document, or recognizes objects in a polished image set. Then it meets a real customer, a messy database, a broken integration, an unusual accent, or an adversarial prompt—and the result can change dramatically.
This gap matters now because AI is moving from experiments into workflows that affect revenue, safety, access, and trust. A system that is “mostly right” in a controlled evaluation can still create costly failures when its errors cluster around the people, conditions, or edge cases that matter most.
The problem is not that testing is useless. It is that many tests measure a narrower, cleaner world than production. Good teams treat evaluation as an ongoing engineering discipline, not a score earned once before launch.
After reading, you will be able to spot common evaluation traps, design more realistic tests, instrument an AI feature in production, and create a practical feedback loop that makes systems safer and more useful over time.
🧪 1. Testing Is a Snapshot; Reality Is a Moving Target
Offline testing usually uses a fixed dataset and a fixed definition of success. Production changes continuously: users adapt, language evolves, data sources drift, policies change, and attackers discover incentives.
A high score means the system handled the examples in that evaluation. It does not guarantee the system will handle tomorrow’s examples, different user populations, or a new upstream data format.
- Offline evaluation: testing before deployment on saved examples.
- Online evaluation: measuring behavior with real traffic after deployment.
- Distribution shift: the real input population differs from the one used for training or testing.
The goal is not to eliminate change. The goal is to detect it early and make the system degrade safely.
📦 2. Benchmarks Often Look Nothing Like User Inputs
Benchmarks are valuable because they are repeatable. But their examples may be short, well labeled, English-heavy, free of typos, and designed by people who already understand the task.
Real requests are frequently incomplete and mixed with irrelevant context. A user might paste a 40-page document, ask several conflicting questions, use domain jargon, and expect the system to infer constraints they never stated.
| Controlled test input | Production input | Evaluation implication |
|---|---|---|
| One clear question | Multiple vague requests | Test ambiguity handling and clarification |
| Clean source text | Scanned, stale, or duplicated documents | Test extraction quality and provenance |
| Expected language and format | Typos, slang, multilingual text | Sample actual user segments |
| Known task boundary | Unrelated or unsafe requests | Test refusal, routing, and escalation |
Build a production-like evaluation set from consented, de-identified examples. Include hard cases, not just cases that flatter the model.
🎯 3. Teams Optimize the Metric Instead of the Outcome
Every metric is a simplification. Accuracy can conceal high-impact mistakes. A chatbot can have an excellent answer-rating average while giving a small number of dangerously confident instructions.
Define the real outcome first. For an internal support assistant, that might be “the employee resolves the issue without opening a ticket,” not merely “the response resembles a reference answer.”
- Write the user’s desired end state.
- List unacceptable failure modes.
- Choose one leading quality metric and several safety guardrails.
- Review examples behind the numbers, especially failures.
- Revisit the definition when the product or user behavior changes.
Use a balanced scorecard: task completion, factual grounding, latency, cost, escalation rate, user effort, and harm indicators. A single leaderboard number is rarely enough.
🧹 4. Clean Test Data Hides Data Quality Problems
Machine learning systems inherit weaknesses from their inputs. If production records contain missing fields, inconsistent labels, duplicates, stale policies, or bad optical character recognition, an AI model may make a plausible answer from unreliable material.
For retrieval-augmented generation, the model may be working correctly while retrieval returns the wrong chunk. Users still experience the result as an AI failure.
def validate_record(record):
    required = ["id", "source", "updated_at", "text"]
    missing = [field for field in required if not record.get(field)]
    if missing:
        return {"valid": False, "reason": f"missing: {missing}"}
    if len(record["text"].strip()) < 40:
        return {"valid": False, "reason": "insufficient text"}
    return {"valid": True}
Validate data at ingestion, not only after users report strange results. Keep source, owner, date, permissions, and version metadata with every document.
🔍 5. Retrieval Failures Are Mistaken for Reasoning Failures
Many business AI systems answer from private documents, databases, or tools. Their quality depends on a pipeline: query rewriting, search, ranking, permission checks, context assembly, generation, and output formatting.
A final answer can fail because the system retrieved nothing, retrieved an outdated policy, cut off the relevant passage, or gave the model too much conflicting context. Testing only the final text hides the actual defect.
- Log the user query and normalized query.
- Log retrieved document IDs, versions, scores, and access decisions.
- Show citations or source excerpts where appropriate.
- Measure retrieval recall separately from answer quality.
- Create tests for stale, duplicate, and contradictory sources.
Make the system say “I could not find an authoritative source” when evidence is weak. An abstention is often more useful than an invented answer.
🧠 6. Models Learn Patterns, Not Your Intended Meaning
Generative models produce likely continuations based on patterns. They do not automatically share an organization’s definitions of “approved,” “urgent,” “current,” or “safe.” A seemingly minor term can carry different meaning across teams.
Write instructions that state operational rules explicitly. Avoid relying on a model to infer a policy from tone, examples, or implied business knowledge.
You are a support assistant for internal policy questions.
Use only the supplied approved sources.
If the sources do not answer the question, say so clearly.
Do not estimate deadlines, eligibility, or legal requirements.
Return: answer, source title, source date, and confidence: high/medium/low.
Prompts help behavior, but they do not replace data governance, authorization controls, or application-level validation.
🧩 7. Edge Cases Are Not Random—They Are Where Risk Lives
Average performance can look strong while the system fails repeatedly for a particular language, device, disability-related interaction, document type, or unusual account state. Those patterns are easy to miss when results are aggregated.
Create a coverage matrix before launch. Treat important segments and workflows as first-class requirements, not optional extras after the main demo works.
| Dimension | Examples to include | Failure to watch for |
|---|---|---|
| User language | Regional wording, code switching | Incorrect interpretation or refusal |
| Input form | Voice transcript, PDF, screenshot | Lost context or extraction errors |
| Task complexity | Single-step and multi-step requests | Skipped constraints or invalid tool use |
| Risk level | Routine and consequential decisions | Overconfident advice or no escalation |
Do not assume that more test examples automatically produce better coverage. A smaller, deliberately stratified set can reveal more than a large collection of easy cases.
🗣️ 8. Users Do Not Prompt Like Evaluators
Test authors tend to ask tidy questions because they know what the system needs. Users are trying to get work done, often under time pressure. They may issue commands, paste fragments, change direction halfway through, or assume the AI remembers something it cannot access.
Test conversational repair. A reliable assistant should recognize missing information, ask a focused follow-up question, and preserve useful context without pretending it knows what was omitted.
User: Fix the report from last time and send it.
Assistant: I can help revise it. Please upload the report or paste the section
that needs changes. Also tell me who should receive it; I cannot send messages
without confirming recipients and the final version.
Common mistake: grading only the ideal first prompt. Grade the entire interaction, including corrections, interruptions, retries, and abandonment.
🔄 9. Feedback Loops Change the System After Launch
An AI feature changes user behavior. If users discover that a confident tone gets requests approved faster, they may phrase inputs strategically. If an assistant is easy to manipulate, shared prompt patterns can spread quickly.
Recommendations also influence what people click, create, and submit. That means the system may gradually reshape its own future data, reinforcing narrow patterns or introducing new bias.
Monitor for behavioral shifts such as repeated rephrasing, copy-pasted prompt templates, sudden category spikes, unusually high acceptance rates, and suspiciously homogeneous outputs. These are product signals, not merely model signals.
🛡️ 10. Security Testing Is Different From Normal Testing
Normal evaluation asks whether the assistant is helpful. Security evaluation asks what happens when someone deliberately tries to make it disclose, bypass, or misuse something.
Prompt injection is a central example. Untrusted content—an email, webpage, document, or tool result—may contain text telling the model to ignore its instructions. The application must treat that content as data, not authority.
- Separate trusted instructions from untrusted retrieved content.
- Use least-privilege credentials for each tool.
- Require confirmation before consequential actions.
- Validate tool arguments with schemas and server-side rules.
- Red-team realistic abuse paths before and after launch.
def create_refund(amount, customer_id, approved_by_user):
    if not approved_by_user:
        raise PermissionError("User confirmation required")
    if amount <= 0 or amount > 500:
        raise ValueError("Amount outside permitted range")
    return refund_service.create(customer_id, amount)
Never rely on a natural-language instruction alone to authorize money movement, account changes, deletion, or sensitive disclosure.
🔧 11. Tool-Using Agents Add Failure Paths
An agent that can search, write files, call APIs, or trigger workflows has more power than a chat-only assistant. It also has more ways to fail: wrong tool selection, malformed parameters, repeated calls, partial completion, and unintended side effects.
Evaluate the full trajectory, not just the final message. A final answer may sound correct even if the agent queried the wrong customer record or silently failed to update a system.
- Start with read-only tools.
- Give every tool a narrow, typed interface.
- Set budgets for calls, time, and cost.
- Make writes reversible where possible.
- Insert approval steps for consequential actions.
- Record an audit trail of tool calls and outcomes.
A useful design pattern is plan, verify, execute: let the AI propose a plan, validate it with deterministic software, then execute only approved actions.
⚙️ 12. Infrastructure Alters Model Behavior
Production is not the notebook. Timeouts, rate limits, overloaded queues, truncated context, fallback models, caching, API changes, and unavailable tools all affect what the user sees.
A system may score well when every request receives a full context window and a fast response. Under load, it might shorten evidence, select a fallback path, or return an unhelpful generic answer.
try:
    answer = generate_with_sources(query, timeout_seconds=8)
except TimeoutError:
    answer = {
        "text": "I could not verify this in time. Please try again or use the source search.",
        "status": "safe_fallback"
    }
Load test realistic input sizes and concurrent demand. Measure quality by operating mode, because “normal” and “degraded” behavior need separate acceptance criteria.
📈 13. Aggregate Scores Conceal Unacceptable Error Rates
Averages are seductive. If 95 out of 100 answers are good, the remaining five may still be unacceptable in a medical, financial, employment, security, or legal-adjacent workflow.
Segment every key metric. Compare outcomes by task type, data source, user language, input length, confidence level, tool path, and severity. Then inspect the raw examples at the worst slices.
- Track severity-weighted errors, not only counts.
- Set explicit stop conditions for critical failures.
- Review low-confidence and high-impact outputs first.
- Measure abstentions: too few can signal overconfidence; too many can signal poor usefulness.
Ask: “Which failure would make us pause rollout?” If nobody can answer, the release criteria are incomplete.
👥 14. Human Review Can Fail Too
Human-in-the-loop is not a magic label. Reviewers can be rushed, over-trust confident prose, lack domain expertise, or receive too little context to catch an error. Automation bias can turn a reviewer into a rubber stamp.
Design review work as a real task. Show sources, uncertainty, changed fields, proposed actions, and the reason an item was flagged. Give reviewers a clear ability to reject, edit, escalate, and explain why.
Sample both accepted and rejected AI outputs. If you inspect only flagged cases, you may miss harmful mistakes that the system marked as safe.
🔒 15. Privacy and Permissions Are Production Requirements
Testing environments often use sanitized data and broad internal access. Production systems must handle personal, confidential, and regulated information according to the organization’s obligations and users’ expectations.
Before collecting logs or building evaluation datasets, decide what data is necessary, who can access it, how long it is retained, and how it will be removed when required. De-identification reduces risk but is not automatically irreversible.
- Minimize prompts, outputs, and metadata retained for evaluation.
- Redact secrets and sensitive identifiers before logging where feasible.
- Enforce document- and user-level access checks before retrieval.
- Separate evaluation access from broad production access.
- Consult security, privacy, and legal specialists for high-risk uses.
Check official documentation and contractual terms for every AI provider and connected tool, since data handling options and controls can change.
🧭 16. Build an Evaluation Set From Real Failure Modes
Start with the work users actually do. Interview support, operations, sales, security, and domain experts. Review tickets, search queries, abandoned sessions, corrected outputs, and incident reports, using appropriate privacy safeguards.
Turn these observations into a living test suite. Each case should state the input, available context, expected behavior, prohibited behavior, risk level, and a scoring method.
{
  "case": "Conflicting policy documents",
  "input": "Can I carry unused leave into next year?",
  "context": ["policy_2023", "policy_2024"],
  "expected": "Use the current policy and cite it",
  "prohibited": "Present the old policy as current",
  "risk": "medium"
}
Include “should refuse,” “should ask a question,” and “should hand off” cases. A mature evaluation suite tests judgment about boundaries, not just the ability to answer.
🚦 17. Release Gradually Instead of Declaring Victory
A phased rollout makes unknown risks observable at a manageable scale. Begin with internal users or a low-risk task, then expand only when evidence supports it.
- Define a baseline without AI.
- Run offline tests and security reviews.
- Release to a small, informed cohort.
- Monitor quality, incidents, and user effort daily.
- Compare against the baseline and investigate regressions.
- Expand, pause, or roll back using predefined rules.
Feature flags, canary releases, and fast rollback paths are practical safeguards. They also prevent a model or prompt update from becoming an irreversible production event.
📊 18. Instrument the System for Debugging, Not Surveillance
Useful observability connects a poor output to the pipeline that created it. Record enough structured information to reproduce a failure while minimizing exposure of user data.
A practical trace can include a request ID, model or workflow route, prompt template identifier, retrieved source versions, tool calls, latency, token or cost estimates, outcome label, and feedback signal. Protect logs as sensitive operational data.
trace = {
    "request_id": request_id,
    "route": "knowledge_assistant",
    "retrieved_source_ids": source_ids,
    "tool_calls": tool_events,
    "latency_ms": elapsed_ms,
    "outcome": "user_requested_handoff"
}
Do not log secrets simply because they are technically available. Establish redaction, access controls, retention limits, and an incident process before scaling observability.
🧾 19. Turn User Feedback Into Labeled Evidence
Thumbs-up and thumbs-down feedback is helpful but ambiguous. A negative rating might mean the answer was wrong, too slow, badly formatted, unsafe, unavailable, or simply not what the user hoped to hear.
Offer lightweight categories and optional comments. Route serious reports to people who can investigate them, then convert confirmed issues into regression tests.
- Wrong fact or unsupported claim
- Missing or outdated source
- Did not follow instruction
- Privacy or permission concern
- Unsafe recommendation
- Technical failure or slow response
Close the loop internally: identify root cause, fix data, prompt, code, policy, or UI, and verify the fix against the original case. Otherwise feedback becomes a dashboard rather than improvement.
🧰 20. Choose the Right Fix for the Failure
“Improve the model” is often too vague. The correct intervention depends on where the failure happened. A bad answer caused by an expired document needs a content fix, not necessarily a different model.
| Observed problem | Likely layer | Practical response |
|---|---|---|
| Unsupported claims | Generation and grounding | Require sources, add abstention rules, verify claims |
| Wrong private fact | Retrieval or permissions | Improve indexing, freshness, and access filtering |
| Bad action taken | Tool orchestration | Add validation, confirmation, and narrower permissions |
| Good answers become poor under load | Infrastructure | Test fallbacks and define safe degraded behavior |
| Repeated user confusion | User experience | Improve input guidance and clarification flow |
Fix the narrowest layer that addresses the root cause, then retest the whole workflow. Broad changes can introduce regressions elsewhere.
✅ 21. Quick-Start Checklist
- Define the user outcome and unacceptable failures before selecting metrics.
- Build a de-identified evaluation set from realistic workflows and incidents.
- Segment results by task, language, source, risk, and operating condition.
- Test ambiguity, refusals, handoffs, corrupted data, and conflicting sources.
- Measure retrieval, tool use, and final answers separately.
- Red-team prompt injection, permission boundaries, and costly actions.
- Launch in phases with feature flags, thresholds, and rollback plans.
- Log privacy-conscious traces that make failures reproducible.
- Turn validated user feedback into regression tests.
- Re-run evaluations after model, prompt, data, tool, policy, or infrastructure changes.
AI systems fail in the real world not because testing is pointless, but because trustworthy testing must continuously represent the messy, changing conditions of real use. Build for uncertainty, monitor what matters, and treat every failure as evidence for a better system. 🤖🔍🚀