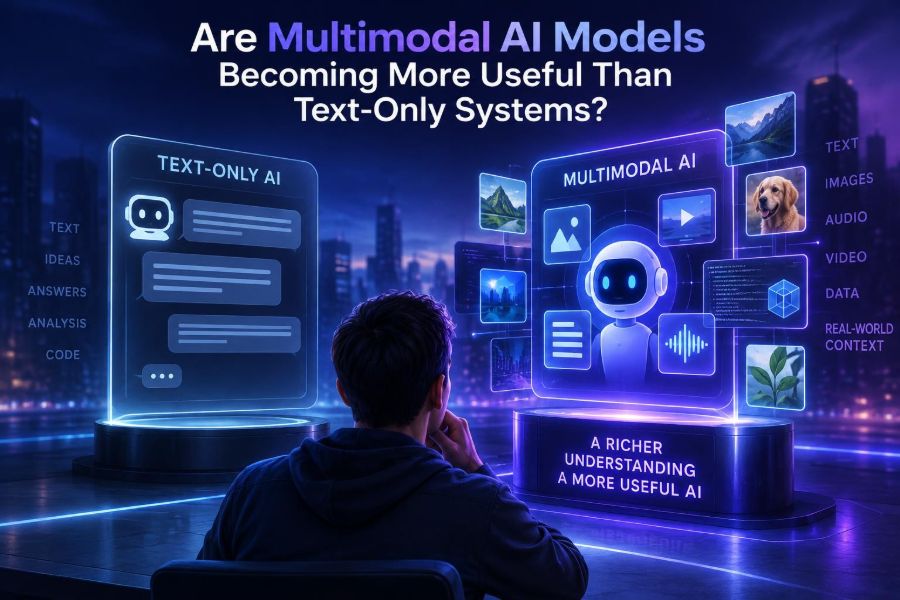

AI used to be mostly a conversation with a text box: type a question, receive an answer. That remains valuable, but much of the world’s useful information is not text. It lives in screenshots, diagrams, audio recordings, product photos, forms, videos, dashboards, and the physical environment around us.
Multimodal AI models can work across several of these formats. They may accept a mix of text, images, audio, video, or documents, then reason over the combined context and respond in text, speech, structured data, or generated media. This makes them increasingly practical for tasks that would be awkward, slow, or impossible with text alone.
That does not mean text-only systems are obsolete. They are often cheaper, faster, easier to evaluate, and excellent for writing, coding, search, and structured workflows. The important question is not which category “wins,” but which mode best represents the problem you need to solve.
After reading, you will be able to recognize strong multimodal use cases, choose an appropriate workflow, write better mixed-media prompts, prototype an application, and avoid common reliability and privacy mistakes.
🧭 1. Start With a Clear Definition of Multimodal AI
Multimodal AI processes or generates more than one kind of data, often called a modality. Common modalities include written language, images, sound, video, documents, tables, and sensor data.
A simple example is asking an assistant to inspect a photo of a damaged appliance and explain what visible parts might need attention. The useful answer depends on both the image and the written request. A text-only model cannot directly inspect the pixels unless another system first converts visual information into text.
- Input multimodality: the system can receive an image, recording, or document alongside instructions.
- Output multimodality: the system can create images, speech, video, or other media in addition to text.
- Cross-modal reasoning: the system relates information across formats, such as matching a chart trend to a spoken explanation.
📈 2. Why This Shift Matters Right Now
Modern work is full of visual and auditory context. A support team sees screenshots. A developer debugs interface recordings. A researcher reads charts and scanned papers. A creator reviews a transcript together with footage and voiceover.
Previously, each task needed separate tools: optical character recognition for text in an image, a vision classifier for objects, speech recognition for audio, and a language model to explain the results. Multimodal systems can reduce that handoff burden by interpreting context in a more unified interaction.
The practical benefit is not magic intelligence. It is often less translation between formats. Fewer conversions can mean fewer lost details, less copy-and-paste work, and a more natural way to ask for help.
⚖️ 3. Compare Multimodal and Text-Only Systems Honestly
Neither approach is universally better. The best choice depends on data type, latency needs, cost controls, accuracy requirements, and how easily you can verify results.
| Situation | Usually stronger choice | Why |
|---|---|---|
| Summarizing a long policy document | Text-only | The source is already machine-readable text and the output is textual. |
| Explaining an unfamiliar dashboard screenshot | Multimodal | Layout, labels, colors, and chart relationships matter. |
| Classifying millions of short support messages | Text-only or specialized classifier | It can be efficient, consistent, and simpler to monitor. |
| Extracting data from photographed receipts | Multimodal with validation | Visual structure and imperfect image quality are central. |
| Reviewing a product-demo recording | Multimodal | Timing, gestures, interface changes, and speech combine. |
| Generating database queries from a schema | Text-only | The task is structured language reasoning, not perception. |
A useful rule is: use a multimodal model when the original medium carries meaning that would be costly or risky to describe manually.
👀 4. Identify Problems Where Visual Context Changes the Answer
Ask one diagnostic question: “If I remove the image, audio, or video, would a skilled person lose important evidence?” If the answer is yes, multimodal input is likely useful.
Strong visual use cases include accessibility descriptions, UI quality assurance, visual inventory review, educational feedback on handwritten work, document extraction, design critique, and chart interpretation.
For example, “Why is my website conversion rate down?” is too broad for an image. But “Compare these two checkout screenshots and identify friction introduced in the newer design” gives the model relevant visual evidence and a bounded task.
Compare these two checkout screenshots.Goal: identify visible changes that may increase user friction.Return:1. A table of changed elements2. Likely usability impact, marked high, medium, or low confidence3. Three testable hypotheses for an A/B testDo not infer behavior that is not visible in the screenshots.🎙️ 5. Use Audio for More Than Transcription
Speech-to-text is useful, but audio includes other signals: pauses, overlap, emphasis, background sounds, speaker turns, and the timing of a conversation. Those signals may matter in meetings, interviews, call review, accessibility tools, and creative production.
Be precise about what you want analyzed. Asking whether someone sounds “untrustworthy” is subjective and can create harmful or biased conclusions. Asking for interruptions, unresolved questions, action items, and timestamps is more concrete and auditable.
Review this meeting recording and transcript.Find decisions, owners, deadlines, unresolved questions, and moments where speakers talk over each other.For every item, include a timestamp and distinguish what was explicitly stated from what is an inference.When correctness matters, keep the original recording available for human review. A fluent summary is not proof that the system heard every word correctly.
🎬 6. Treat Video as a Sequence, Not Just a Stack of Images
Video adds time. A still frame can show what is visible, while a sequence can show what changed, in what order, and how a person or interface responded.
This is helpful for training analysis, incident review, sports or movement feedback, manufacturing inspection, and software testing. But longer video also creates practical constraints: uploading, processing, context limits, and selecting the relevant segment.
- Trim the footage to the moment that matters.
- State the event you want investigated.
- Request timestamps for claims.
- Ask for uncertainty rather than a forced conclusion.
- Review a few cited moments manually before acting.
Do not expect an AI review to replace qualified safety, medical, legal, or security investigation. It can organize observations, but consequential conclusions need domain expertise and evidence.
📄 7. Understand Documents as Both Text and Layout
A PDF may contain selectable text, scanned pages, tables, stamps, signatures, columns, footnotes, charts, and handwritten annotations. Turning it into plain text can scramble reading order or discard visual relationships.
Multimodal document understanding can preserve more context, especially when forms and layouts matter. Still, it can confuse adjacent columns, miss faint text, or misread a checkbox. Treat extraction as a draft that needs validation.
- Use high-resolution, properly oriented scans.
- Ask the model to preserve page numbers and table locations.
- Validate high-impact fields against the source image.
- Use rules for predictable fields such as dates, IDs, and totals.
- Route ambiguous pages to human review.
🧩 8. Write Prompts That Bind Every Input Together
A frequent mistake is attaching an image with a vague instruction such as “What do you think?” The model may describe the most obvious feature rather than solve the real problem.
Good multimodal prompts name the input, desired task, output format, and boundaries. They also tell the model whether it should use the visual source as authoritative evidence or merely as inspiration.
You are helping a developer investigate this error screenshot.First transcribe the visible error message exactly where legible.Then identify the likely failing component using only visible evidence.Suggest up to three debugging steps, ordered from least invasive to most invasive.If a detail is unreadable, say so rather than guessing.For creative work, add constraints such as audience, aspect ratio, mood, brand rules, and prohibited elements. For analytical work, require a structured response and evidence references.
🗂️ 9. Ask for Structured Outputs You Can Verify
Free-form prose is convenient for people, but applications need predictable fields. Ask the model to return a defined schema, and validate it before storing or acting on it.
{ "document_type": "string", "fields": [{"name": "string", "value": "string", "confidence": "high|medium|low"}], "visual_issues": ["string"], "needs_human_review": true}Even if a provider supports a structured-output feature, validate types, allowed values, required fields, and business rules in your own code. A schema makes integration safer; it does not guarantee that extracted facts are correct.
🛠️ 10. Build a Small Multimodal Prototype
A useful first prototype should solve one narrow task. For example: accept an image of a receipt, extract merchant, date, currency, and total, then flag uncertain values for review.
The exact APIs and SDKs vary quickly, so consult your selected model provider’s current official documentation. The architecture below is intentionally provider-neutral.
function analyzeReceipt(imageBytes) { const prompt = "Extract merchant, date, currency, and total. Return JSON. Mark unreadable fields as null."; const result = multimodalModel.generate({ input: [ { type: "text", value: prompt }, { type: "image", value: imageBytes } ] }); const data = validateAgainstSchema(result); return data.confidence === "low" ? queueForReview(data) : save(data);}Start with a test set of real, permissioned examples. Include clean and messy inputs: glare, blur, rotation, unusual layouts, multiple currencies, and partial receipts.
🧪 11. Evaluate the Whole Workflow, Not a Memorable Demo
A single impressive result can hide a brittle system. Evaluate the task using a representative set of inputs and define what “good” means before you look at outputs.
For receipt extraction, measure field accuracy, rate of valid structured responses, time to human correction, and how often the system correctly flags uncertainty. For a screenshot assistant, measure whether recommendations are actionable and grounded in visible evidence.
- Accuracy: Is the claimed fact correct?
- Grounding: Does the claim match the provided media?
- Completeness: Did it capture required information?
- Calibration: Does low confidence correlate with actual errors?
- Operational value: Does it save time without adding review burden?
Keep a failure log. Repeated errors often reveal an input-quality issue, prompt ambiguity, missing business rule, or a task that needs a specialized system rather than a general model.
🔄 12. Use Hybrid Pipelines Instead of Forcing One Model to Do Everything
The most useful systems often combine modalities and tools. A multimodal model can interpret an uploaded document, a text model can draft an explanation, a retrieval system can find policy details, and deterministic code can enforce business rules.
This division makes a system easier to test and cheaper to operate. It also limits the impact of a perception mistake.
Upload document→ detect pages and image quality→ extract visual fields with a multimodal model→ validate IDs, dates, and totals with rules→ retrieve relevant policy text→ generate a user-facing explanation→ send exceptions to a human reviewerUse the simplest component that can reliably perform each stage. Not every box in a workflow needs a large general-purpose model.
💻 13. Add Multimodal Features to Developer Workflows
Developers can use visual input to shorten debugging loops. Instead of transcribing a console screenshot or describing an interface defect, attach the artifact and request a careful analysis.
Strong developer tasks include explaining a stack trace screenshot, comparing expected and actual UI states, extracting values from a chart, reviewing a diagram, and turning a whiteboard sketch into an implementation plan.
Inspect this UI screenshot and the attached component code.List visual mismatches against the stated design requirements.For each mismatch, identify the most likely CSS or layout cause.Do not claim to have run the code or inspected files that were not provided.Never accept generated fixes blindly. Run tests, inspect diffs, use linters, and verify accessibility. Visual reasoning is helpful, but it can miss responsive states, hidden elements, and runtime conditions.
🎨 14. Give Creators Better Briefs and Better Review Loops
For creators, multimodality can connect rough ideas to usable assets. A sketch, mood board, voice note, reference image, and written brief can become a more complete creative direction than text alone.
The best practice is to separate ideation from approval. Ask the model to propose options, then use an explicit checklist to review factual claims, brand compliance, visual consistency, accessibility, and rights.
Use the attached mood board only for palette, lighting, and composition cues.Create three concepts for a technology newsletter header.Audience: practical AI builders.Avoid copying identifiable characters, logos, or artist-specific styles.For each concept, provide a short art direction and accessible alt-text draft.Be cautious with reference material you do not have permission to use. “Inspired by” is not a substitute for respecting intellectual-property and platform rules.
🔐 15. Protect Privacy, Consent, and Sensitive Media
Images, recordings, and documents can expose more than their creator intended. A screenshot may include account numbers, private messages, location details, or customer data. Audio and video can contain biometric, health, workplace, or family information.
Before uploading media to any AI service, understand the provider’s current data handling, retention, training, access, and regional processing policies. These details can change, so check the official source and your organization’s requirements.
- Remove unnecessary personal and confidential information.
- Get appropriate consent before analyzing recordings or photos of people.
- Use approved enterprise controls for workplace data.
- Limit retention and restrict access to outputs.
- Do not use face, voice, or emotion inference for high-stakes decisions without legal, ethical, and expert review.
⚠️ 16. Know the Failure Modes Before They Surprise You
Multimodal models can hallucinate objects, read text incorrectly, misunderstand a chart, confuse spatial relationships, or overstate what is visible. They may also inherit bias from uneven training data and struggle with uncommon contexts, low-quality media, or specialized jargon.
A model’s confident tone is especially dangerous when it is interpreting evidence. Design prompts and interfaces that make uncertainty visible.
- Ask it to quote or point to evidence when possible.
- Require “not visible” or “uncertain” as valid answers.
- Use confidence as a review-routing signal, not a truth score.
- Do not automate irreversible actions from unverified perception.
- Test across lighting, languages, devices, layouts, and user groups.
🚦 17. Decide When Text-Only Is Still the Smarter Choice
Text-only workflows remain ideal when input is clean text, the task is language-centric, high volume matters, or you need straightforward retrieval and evaluation. They can also reduce sensitive-media exposure and simplify system design.
Do not attach an image simply because you can. If a product catalog already contains reliable structured metadata, passing photos through a large vision model may add cost and variability without adding insight.
A practical decision sequence is: identify the source of truth, ask whether non-text context changes the answer, estimate verification cost, then choose the smallest reliable workflow. That may be text-only, multimodal, specialized vision or speech software, or a hybrid.
🗺️ 18. Track the Trend Without Chasing Every Model
The direction is clear: interfaces are becoming more natural, with systems that can see, hear, speak, read, and generate across formats. The more important trend is operational: AI is moving closer to real work artifacts rather than living only in chat windows.
Still, capabilities differ widely among tools, and advertised examples do not define dependable production behavior. Evaluate models on your data, your permissions, your failure tolerance, and your integration needs.
Watch for improvements in real-time interaction, document reasoning, controllable media generation, tool use, and evaluation methods. But prioritize durable skills: clear task design, high-quality inputs, validation, privacy discipline, and human judgment.
✅ 19. Use This Quick-Start Checklist
- Choose one task where an image, audio clip, video, or layout genuinely contains key evidence.
- Collect a small, permissioned set of representative examples.
- Define the expected output and what a correct answer looks like.
- Write a prompt that names the inputs, goal, limits, and output structure.
- Ask the model to state uncertainty and avoid unsupported claims.
- Validate structured fields and enforce business rules in code.
- Build a human-review path for ambiguous or high-impact results.
- Test failures, not just polished examples.
- Review privacy, consent, retention, and provider policies before deployment.
- Keep text-only or specialized components where they are simpler and more reliable.
Multimodal AI is becoming more useful not because text has stopped mattering, but because useful work rarely arrives in text alone. Choose the modality that preserves the evidence, design for verification, and let people remain accountable for important decisions. 🤖👁️⚡