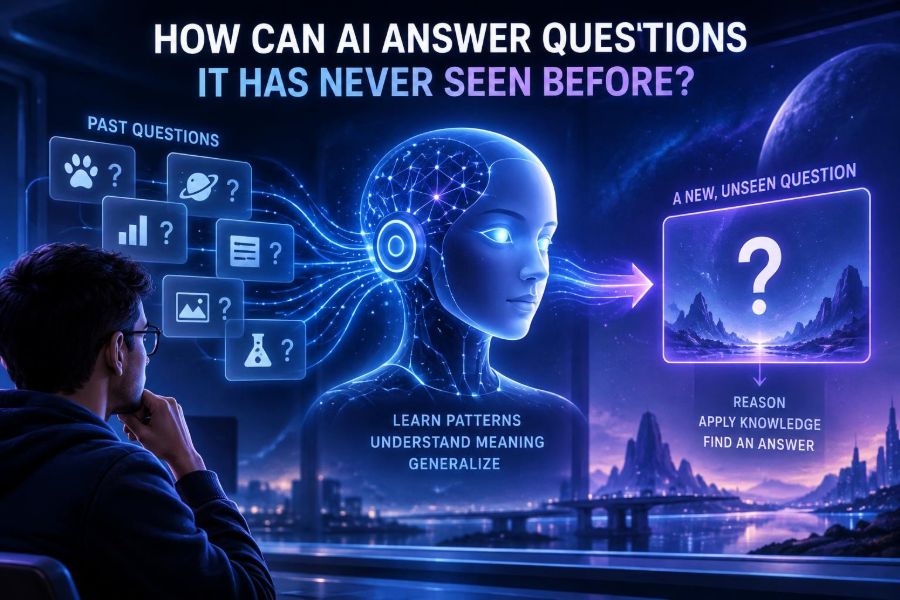

It can feel uncanny: you ask an AI assistant a question phrased in a completely new way, about a niche combination of ideas, and it produces a useful answer. It was not necessarily given that exact question and answer pair. So what is it actually doing?
This matters now because generative AI is moving from novelty to everyday infrastructure. People use it to explain concepts, draft code, analyze documents, brainstorm designs, and support decisions. Getting value from it requires more than knowing a few prompts; it requires a working mental model of its strengths and boundaries.
The key idea is not that a model has a secret database containing every answer. It has learned statistical patterns in language, code, images, and other data, then uses those patterns to generate a likely continuation of your request.
By the end, you will be able to explain why AI can handle unfamiliar questions, write prompts that help it reason more reliably, choose when to add retrieval or tools, and build a small grounded question-answering workflow.
🧠 1. The short answer: AI generalizes patterns
Modern language models answer unseen questions through generalization. During training, they encounter enormous numbers of examples of language: explanations, conversations, code, documents, arguments, tables, and more.
They do not merely retain complete sentences. They learn relationships among concepts and patterns in how people express those relationships. When you ask a new question, the model combines relevant learned patterns with the context you provide.
For example, it may never have seen the exact question, “Explain database indexing with a library metaphor for a teenager.” Yet it may have learned about databases, indexes, libraries, metaphors, and age-appropriate explanations separately.
- Training builds broad capabilities from many examples.
- Prompting tells the model which capability and format you need now.
- Context supplies task-specific facts the model should use.
- Generation creates a response one small piece at a time.
🔤 2. It starts by turning language into tokens
Before a model can work with your request, it converts text into tokens: small units such as whole words, word fragments, punctuation, or symbols. The exact split varies by model and language.
“How can I secure an API?” is not processed as a human-like sentence with an inherent meaning attached. It becomes a sequence of token identifiers. Those identifiers are transformed into numerical representations the neural network can process.
Tokens explain a few practical behaviors. Long documents consume available context, unusual spellings can be handled inconsistently, and tightly formatted code or data can need extra care.
Prompt: Explain OAuth in 5 bullets for a frontend developer.

Possible token-level generation idea:
"OAuth" → " is" → " a" → " delegated" → " authorization" → ...
The model is not selecting an entire finished paragraph from a shelf. It repeatedly predicts what token should come next, while considering the tokens that came before.
🗺️ 3. Meaning becomes geometry in a high-dimensional space
Inside the model, tokens are represented as lists of numbers often called embeddings. You can think of an embedding as a coordinate in a very large map where related meanings tend to occupy useful nearby regions.
This is only a metaphor, but it is productive. “Paris” may have relationships to “France” similar to relationships between “Tokyo” and “Japan.” A model can learn patterns involving categories, syntax, tone, analogy, and many task structures.
Embeddings do not create perfect human understanding. They are learned representations shaped by training data and the objective of predicting text. Still, they let a model respond sensibly to paraphrases and new combinations.
- “Summarize this report” and “Give me the main takeaways” can activate similar task patterns.
- “Write a polite refusal” and “Decline this professionally” can lead to similar stylistic behavior.
- “Find a security risk in this code” can connect code patterns with security concepts.
🔎 4. Attention helps the model focus on relevant context
Transformer-based models use a mechanism called attention. In simple terms, while generating each new token, the model can weigh different parts of the prompt and earlier response according to their relevance.
Ask for a summary of a pasted policy, and attention can connect a later exception to a rule introduced many paragraphs earlier. Ask it to transform a JSON object, and it can attend to keys, values, and formatting constraints.
Attention is powerful, but not magical. A model can overlook a detail, treat an instruction ambiguously, or become less reliable when a prompt is extremely long, cluttered, or contradictory.
Practical implication
Put the most important constraints where they are easy to identify. Use headings, delimiters, and explicit output formats rather than burying requirements in a dense block of prose.
Task: Answer using only the reference notes below.

Reference notes:
---
[paste approved material here]
---

Question: What are the three eligibility requirements?

Output:
- Three bullets
- Quote the relevant wording briefly
- If the notes do not say, write: "Not stated in the notes."
🎓 5. Training teaches patterns, not guaranteed facts
During pretraining, a model learns by predicting missing or next tokens across vast datasets. It gradually adjusts many internal numerical parameters to improve those predictions.
Later training may improve instruction following, safety behavior, tool use, coding, or conversational quality. Exact methods vary by provider and model, and public descriptions may be incomplete, so consult official documentation when details matter.
A crucial distinction: training can create broad knowledge and skills, but it does not guarantee a current, traceable, or correct answer to every factual question. Training data can be incomplete, biased, outdated, inconsistent, or wrong.
| Capability source | What it helps with | Main risk |
|---|---|---|
| Pretraining | Language, broad concepts, common patterns | Stale or uncertain facts |
| Prompt context | Your rules, examples, and supplied material | Ambiguous or overloaded instructions |
| Retrieved documents | Current, private, and verifiable information | Irrelevant or poor-quality sources |
| Tools | Calculations, databases, APIs, workflows | Bad inputs, permissions, or tool errors |
🧩 6. New questions often recombine familiar pieces
Many apparently novel questions are compositions of known elements. A model can apply a learned process to a new domain: compare options, extract requirements, produce an outline, explain a mechanism, or translate a style.
Consider: “Create a meal-planning app data model for a family with allergies and rotating schedules.” The exact request may be new, but its components draw on familiar patterns from data modeling, meal planning, constraints, calendars, and user requirements.
This is why precise context helps so much. You are not asking the model to guess which version of a broad task you mean; you are supplying the pieces needed to assemble a relevant response.
🎲 7. Generation is prediction, not a hidden search for truth
At each step, a language model assigns probabilities to possible next tokens. A decoding process selects one, then repeats. Settings may influence whether output is more predictable or more varied.
That mechanism can produce eloquent prose even when the underlying claim is false. Fluency is evidence that the model can generate fluent language; it is not evidence that a statement has been verified.
For creative drafting, some variation is useful. For legal, medical, financial, security, compliance, or operational decisions, prioritize source-grounding, human review, and deterministic checks where possible.
- Use lower-variation settings when consistency matters.
- Request assumptions and uncertainty explicitly.
- Ask for calculations to be shown, then independently verify them.
- Require citations or source excerpts when your workflow supports them.
💬 8. Prompts work because they set the temporary task
A prompt is not merely a question. It is a compact task specification. It can establish a role, audience, input, constraints, examples, evaluation criteria, and desired output structure.
The strongest prompts reduce interpretive gaps. Instead of “Make this better,” state what better means: clearer for beginners, shorter than 120 words, technically accurate, and free of jargon.
A reliable prompt recipe
- State the goal.
- Identify the audience and context.
- Provide source material or inputs.
- Set constraints and exclusions.
- Specify an output format.
- Define what to do when information is missing.
You are helping a product manager prepare a technical brief.

Goal: Turn the notes into an implementation-ready summary.
Audience: Backend and frontend engineers.

Requirements:
- Preserve only facts found in the notes.
- Identify assumptions separately.
- List open questions.
- Use concise language.

Notes:
---
[paste notes]
---

Return sections named: Summary, Requirements, Assumptions, Open Questions.
🧪 9. Few-shot examples show the pattern you want
Few-shot prompting means including one or more examples of input and desired output in the prompt. It is especially useful for classification, formatting, extraction, tone, and edge cases.
Examples work best when they resemble the real task and demonstrate a consistent rule. They should not accidentally teach the model to copy irrelevant details or overfit to one unusual case.
Classify each support message as BILLING, BUG, FEATURE, or OTHER.

Message: "I was charged twice for my subscription."
Label: BILLING

Message: "The export button does nothing in Safari."
Label: BUG

Message: "Please add calendar sync."
Label: FEATURE

Message: "Can I change the account email?"
Label:
For production workflows, include examples for ambiguity. If one message can be both a bug report and a feature request, define the tie-break rule rather than hoping the model infers your policy.
📚 10. Retrieval gives AI information it was not trained to know
When answers must reflect current or private material, use retrieval-augmented generation, commonly called RAG. The system searches an approved knowledge base, selects relevant passages, and provides them to the model along with the question.
The model then writes an answer grounded in those passages. This is fundamentally different from hoping its training knowledge happens to contain the needed detail.
A practical RAG pipeline
- Collect trusted documents and define who may access them.
- Clean text while preserving titles, dates, authors, and permissions.
- Split documents into meaningful chunks.
- Create embeddings for chunks and store them with metadata.
- Embed the user question and retrieve related chunks.
- Optionally rerank the best candidates.
- Ask the model to answer only from retrieved context.
- Return supporting excerpts and log failures for improvement.
Question → embed question → retrieve approved chunks
         → rerank chunks → build grounded prompt
         → model answer + source references
RAG is useful for internal policies, product manuals, research collections, support documentation, and frequently changing facts. It does not make an answer automatically correct: bad retrieval produces badly grounded answers.
🗂️ 11. Chunking and metadata decide whether retrieval succeeds
Search quality often depends more on document preparation than on a clever prompt. A giant document chunk may contain every relevant fact but be too broad; tiny chunks may lose the surrounding meaning needed to interpret a sentence.
Split on natural boundaries such as headings, sections, or records. Preserve overlap where it prevents a key definition from being separated from its qualification.
- Attach metadata: document title, section, owner, date, product area, and access controls.
- Filter before retrieval when users should see only a subset of documents.
- Test exact terms, paraphrases, acronyms, and multi-part questions.
- Keep original source locations so reviewers can inspect the evidence.
Do not treat semantic search as a replacement for keyword search. Hybrid retrieval, which combines semantic similarity with lexical matching, can be stronger when exact names, part numbers, error codes, or legal clauses matter.
🛠️ 12. Tools let models act beyond text prediction
A model can be connected to tools such as calculators, search systems, databases, code runners, ticketing systems, or internal APIs. The model interprets a request, chooses an allowed action, supplies structured arguments, then uses the result to answer.
This can make a system more capable and current. It also raises the stakes: an incorrect action can affect data, money, operations, or users.
{
  "tool": "get_order_status",
  "arguments": {
    "order_id": "ORD-48291"
  }
}
Design tool use as a controlled workflow, not a blanket permission. Validate arguments, enforce authentication and authorization outside the model, restrict actions by default, and require confirmation before irreversible changes.
👨💻 13. Build a small grounded Q&A prototype
You can sketch a simple application with three components: a document index, a retrieval function, and a model call. The pseudocode below focuses on the architecture rather than any particular provider library.
def answer_question(question, user):
    query_vector = embed(question)

    candidates = vector_store.search(
        vector=query_vector,
        filters={"allowed_groups": user.groups},
        limit=8
    )

    context = format_passages(candidates)
    prompt = f"""
Answer only from the reference passages.
If the answer is absent, say you cannot find it in the references.
Cite passage IDs after each claim.

Reference passages:
{context}

Question: {question}
"""
    return model.generate(prompt)
Next, add evaluation before adding features. Create a small test set of real questions with expected answers or expected source passages. Include questions the system should refuse because the answer is not in the collection.
Useful evaluation checks
- Did retrieval include the passage that contains the answer?
- Did the answer stay faithful to that passage?
- Did it correctly admit when evidence was missing?
- Did authorization filters prevent unauthorized retrieval?
- Did citations point to relevant, readable material?
⚖️ 14. Reasoning-like behavior has limits
Models can perform impressive multi-step tasks: draft plans, compare trade-offs, write code, and explain intermediate logic. But their output is not a reliable window into a human-like internal thought process, and a plausible explanation can still be mistaken.
For high-stakes workflows, break complex work into verifiable stages. Ask for structured outputs, validate them with software rules, retrieve evidence, use specialized tools, and involve an expert where judgment is required.
Before giving a recommendation:
1. List the facts used.
2. Label uncertain assumptions.
3. Identify missing information.
4. Offer options with trade-offs.
5. Do not make a final decision on the user's behalf.
This approach is more dependable than asking an assistant to “think harder.” Better inputs, clear decomposition, independent checks, and appropriate tools usually matter more.
🚧 15. Common mistakes and how to fix them
| Mistake | Why it fails | Better approach |
|---|---|---|
| Asking vague questions | The model must guess the goal and audience. | State outcome, reader, constraints, and format. |
| Trusting confident prose | Confidence is a writing style, not proof. | Verify consequential claims against primary sources. |
| Pasting huge unstructured files | Important details can be diluted or missed. | Chunk, label, retrieve, and ask targeted questions. |
| Using RAG without testing retrieval | The right answer may never reach the model. | Measure retrieval separately from answer quality. |
| Giving tools excessive permissions | Prompt mistakes can become real actions. | Use least privilege, validation, and confirmation. |
| Ignoring edge cases | Happy-path demos hide operational failures. | Test ambiguity, missing data, conflicts, and adversarial inputs. |
🔐 16. Protect privacy, security, and people
Before sending information to an AI service, determine what data is permitted, where it is processed, how long it is retained, and who can access it. Policies, contracts, and product settings differ, so check official documentation and your organization’s requirements.
Do not paste secrets, credentials, private customer records, proprietary code, or sensitive personal data into a tool unless you have an approved, secure workflow. Redact inputs when possible and minimize the data sent.
Also guard against prompt injection. Untrusted text may contain instructions aimed at manipulating an AI system. Treat retrieved web pages, emails, attachments, and user content as data, not as trusted commands.
- Separate system rules from untrusted content.
- Restrict what tools can access and do.
- Validate model outputs before executing actions.
- Log important decisions without logging unnecessary sensitive data.
- Provide a clear route to human review and correction.
✅ 17. Quick-start checklist
- Define whether you need creativity, general explanation, current facts, or a precise action.
- Write the goal, audience, constraints, and output format before prompting.
- Provide trusted context for facts that must be accurate.
- Use examples when classification, formatting, or tone is important.
- Use retrieval for private, changing, or source-backed knowledge.
- Evaluate retrieval and generation separately with real questions.
- Verify high-impact claims, calculations, and decisions independently.
- Limit sensitive data and tool permissions from the start.
- Record failures, refine prompts and sources, then test again.
AI can answer unfamiliar questions not because it has seen every question before, but because it learns reusable patterns and can combine them with the right context, evidence, and tools. Build around that strength, verify where it is weak, and you can turn a surprising capability into a dependable one. 🤖🔍🚀