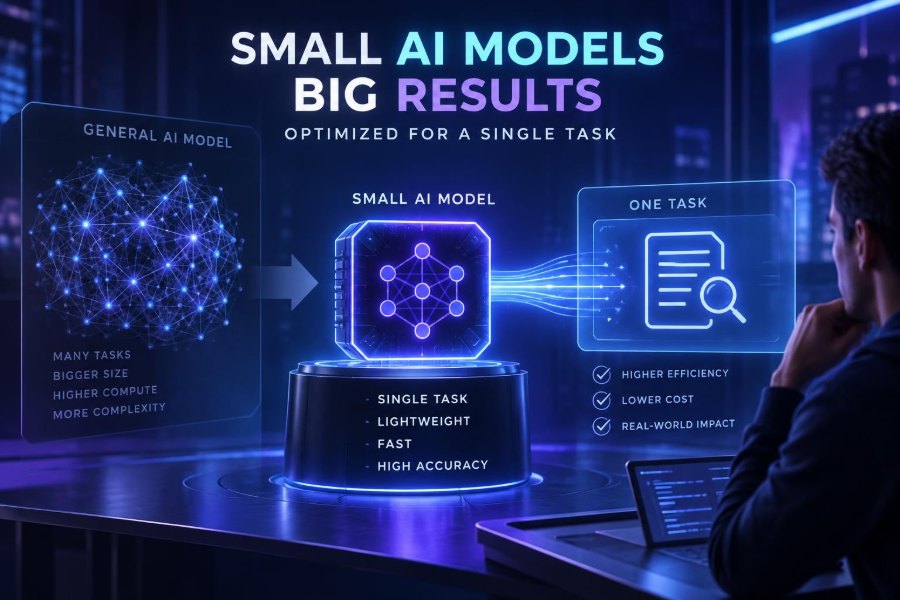

AI does not always need to be enormous to be useful. While general-purpose models can write, code, summarize, and converse across thousands of topics, many real products need to do one thing reliably: classify a support ticket, extract a field from an invoice, detect a defect, route a document, or answer questions from a fixed knowledge base.
That is where small, task-optimized AI models become interesting. They can be faster, cheaper to run, easier to keep private, and more predictable than a broad model asked to improvise across every possible request.
The important distinction is not simply “small versus large.” It is whether the model, data, workflow, and evaluation are tightly matched to a clearly defined job. A small model with a well-designed pipeline can outperform a much larger one on the narrow problem it was built to solve.
After reading, you will be able to identify tasks that fit small models, choose among prompting, retrieval, fine-tuning, and classical machine learning, build a practical evaluation set, and deploy a focused AI feature without overbuilding it.
🎯 1. What “Small” and “Single Task” Actually Mean
A small AI model usually has fewer parameters, needs less memory, and requires less computing power than a frontier-scale general model. There is no universal cutoff: what counts as small depends on your hardware, latency target, model family, and application.
A single-task model is optimized for a bounded outcome with a defined input and output. It may be an ML classifier, a compact language model, an embedding model plus rules, or even a model distilled from a larger teacher model.
- Input: a customer message.
- Output: billing, technical support, cancellation, or other.
- Success criterion: correct routing at an acceptable confidence level.
“Answer every customer question accurately” is not a single task. “Assign each incoming message to one of 12 queues” is much closer to one.
⚖️ 2. Why Narrow Optimization Changes the Equation
General models spend capacity learning broad language, world knowledge, reasoning patterns, and many output formats. That flexibility is valuable, but it also means their behavior can be more variable and their serving cost can be higher.
In a narrow workflow, you can remove ambiguity. The model sees a limited vocabulary, a known document layout, a stable set of labels, and an output schema. You can constrain the problem before the model ever makes a prediction.
| Approach | Best at | Trade-off |
|---|---|---|
| Large general model | Open-ended requests and changing tasks | Higher latency, cost, and output variability |
| Small language model | Structured text tasks and local inference | Less broad knowledge and weaker long-context handling |
| Fine-tuned compact model | Repeated, stable domain behavior | Needs curated training data and monitoring |
| Classical ML model | Tabular data and fixed classification | Usually cannot handle nuanced generative work |
| Rules plus embeddings | Known policies and semantic matching | Needs careful threshold and rule maintenance |
The winning system is often not “the smartest model.” It is the smallest reliable system that meets the product requirement.
🧩 3. Start by Shrinking the Problem, Not the Model
Before selecting a model, turn a vague ambition into an operational contract. The more precise the contract, the more likely a compact solution will work.
- Write the exact input source and format.
- Define the allowed output values or schema.
- List cases that should be rejected or escalated.
- Set a quality target, such as precision for a high-risk label.
- Set operational limits for latency, cost, memory, and privacy.
For example, “summarize meeting notes” is broad. A narrower contract is: “Convert a transcript into three action items, each with an owner, a due date when explicitly stated, and a source quote.”
Task: extract action items from internal meeting transcripts

Allowed output fields:
- action
- owner
- due_date
- evidence

Rules:
- Do not infer an owner or date.
- Return an empty list when no explicit action exists.
- Preserve exact wording in evidence.
This definition is already an evaluation plan in miniature.
📦 4. The Best Jobs for Focused Small Models
Small models shine when the input distribution repeats and the correct output is constrained. They are especially effective when a large portion of the work is pattern recognition rather than open-ended invention.
- Classification: sentiment, intent, topic, risk level, moderation category.
- Extraction: names, IDs, dates, totals, product attributes, medical codes with proper governance.
- Ranking: sorting search results, leads, alerts, or candidate matches.
- Detection: anomalies, fraud signals, manufacturing defects, spam, duplicates.
- Transformation: normalizing addresses, redacting sensitive data, converting text to a structured record.
- Constrained generation: short replies, labels, templates, or code completions within a narrow internal API.
A useful signal is repetition. If humans solve the same decision hundreds of times per day using a short policy, the task is a candidate for specialization.
🔍 5. Know When a Small Model Is the Wrong Tool
Specialization is not magic. A small model can fail when requests are highly novel, the task needs deep multi-step reasoning, the source material changes constantly, or the downside of one error is severe.
Do not force a narrow system to act as a general assistant. Instead, use routing: send easy, well-scoped cases to the small model and send uncertain or unusual cases to a stronger model or a human reviewer.
if confidence >= 0.92 and input_is_in_scope:
    result = small_model.predict(input)
elif request_needs_current_policy_lookup:
    result = retrieval_workflow(input)
else:
    result = human_or_larger_model_review(input)
This pattern is often more dependable than making one model handle every case.
🧠 6. Choose the Simplest Viable Method
Many teams jump straight to fine-tuning a language model. Start lower on the complexity ladder. A simpler approach can be easier to inspect, cheaper to operate, and just as accurate for the actual task.
| If your task looks like this | Try this first |
|---|---|
| Known keywords and deterministic policies | Rules and validation logic |
| Short text assigned to fixed labels | Embeddings or classical text classification |
| Similarity search across internal documents | Embedding retrieval with citations |
| Structured extraction from varied text | Prompted model with schema checks |
| Stable domain language and many examples | Fine-tuned compact language model |
| Images, audio, or sensor input | Purpose-built vision, speech, or anomaly model |
Use a larger model during prototyping if it helps you understand the problem. Then measure whether a smaller pipeline can reproduce the required behavior.
🧪 7. Build an Evaluation Set Before You Optimize
Without representative test data, “this feels good” becomes the benchmark. That is risky because demos naturally favor clean, memorable examples.
Create a held-out evaluation set that reflects production. Include normal cases, difficult cases, short or malformed inputs, ambiguous requests, and examples from important user groups or regions where applicable.
- Collect historical examples with appropriate permission and data handling.
- Remove or protect sensitive information.
- Define the correct output and acceptable alternatives.
- Label edge cases, exclusions, and escalation cases.
- Keep the test set separate from training and prompt iteration data.
For extraction, measure exact field accuracy and invalid-format rate. For classification, inspect precision and recall per class, not only total accuracy. A model that misses rare urgent cases can look excellent in aggregate metrics.
📏 8. Measure the Metrics That Match Real Risk
Every task has different failure costs. A false positive in a recommendation widget may be tolerable; a false negative in safety triage may not be.
- Precision: when the system says yes, how often is it correct?
- Recall: of all true cases, how many did it find?
- F1 score: a balance of precision and recall.
- Calibration: whether confidence scores correspond to real likelihoods.
- Latency: time from request to usable answer.
- Cost per successful task: include retries, review, and infrastructure.
- Abstention rate: how often the system appropriately declines to decide.
Also measure the end-to-end workflow. A fast model is not helpful if downstream validation, retries, or human correction erase the time saved.
🏷️ 9. Data Quality Is Usually the Main Advantage
For a focused task, a modest amount of high-quality, representative data can matter more than switching among many model architectures. The model learns the definition embedded in your labels.
Write a labeling guide with examples and counterexamples. If two reviewers cannot consistently agree on what “urgent” means, a model will not discover a stable definition by itself.
Useful labeling rules
- Specify whether labels describe the user’s words, the likely intent, or the required business action.
- Define one primary label when multiple labels seem plausible.
- Include an “other,” “unknown,” or “needs review” path where appropriate.
- Track annotator disagreement; it reveals unclear policy.
- Version your label definitions as policies evolve.
Common mistake: training on polished examples while deploying on typos, pasted logs, abbreviations, and incomplete forms.
🗜️ 10. Four Ways to Make Models Smaller and Faster
Optimization can mean choosing a compact base model, but it can also mean reducing the work around it. The right tactic depends on your quality target and hardware.
- Distillation: train a smaller student to imitate useful behavior from a stronger teacher, then validate against real labels.
- Quantization: represent model weights with lower numerical precision to reduce memory and often improve speed.
- Pruning: remove less useful parameters or structures, followed by evaluation and sometimes retraining.
- Prompt and context reduction: send only relevant instructions and evidence rather than an entire database or chat history.
Quantization can be practical for local or edge deployment, but quality and compatibility vary by model and runtime. Check the documentation for your specific model-serving stack and test the quantized artifact on your own evaluation set.
🧰 11. Use Retrieval When Knowledge Changes More Than Behavior
Fine-tuning is good for teaching a consistent behavior, style, or domain pattern. It is not usually the best primary mechanism for keeping changing facts current.
For policies, manuals, product catalogs, and internal documentation, retrieve relevant passages at request time. Then ask a model to answer only from those passages, ideally returning the source snippets or identifiers to your interface.
System instruction:
Answer using only the supplied policy excerpts.
If the excerpts do not contain the answer, return: INSUFFICIENT_EVIDENCE.
Return JSON with answer, source_ids, and confidence.

Policy excerpts:
[POL-17] Refunds are available within the stated eligibility period.
[POL-22] Account owners can update billing details in settings.

User question:
Can I change the card used for billing?
Retrieval does not eliminate hallucinations. It creates evidence boundaries that your prompt, validator, and user interface must enforce.
🧱 12. Constrain Outputs So Automation Can Trust Them
Free-form text is convenient for humans but fragile for software. When a model feeds an API, database, or workflow, require a structured output and validate it before taking action.
{
  "category": "billing",
  "priority": "normal",
  "needs_human_review": false,
  "reason": "Customer asks to update payment method"
}
Then enforce allowed values in code. Do not silently accept a creative variation such as “medium priority” when only “low,” “normal,” and “high” are valid.
allowed_categories = {"billing", "technical", "cancellation", "other"}
allowed_priorities = {"low", "normal", "high"}

if output["category"] not in allowed_categories:
    route_to_review("invalid category")
elif output["priority"] not in allowed_priorities:
    route_to_review("invalid priority")
else:
    send_to_queue(output)
Validation turns a language model from an unconstrained text generator into one component of a controlled system.
🔁 13. Create a Cascade Instead of Picking One Model Forever
A model cascade uses different levels of capability based on difficulty. It preserves speed and cost for routine requests while reserving more expensive processing for uncertainty.
- Apply deterministic checks first.
- Run the small model for in-scope inputs.
- Validate schema, confidence, and evidence.
- Escalate failed checks to retrieval, a larger model, or a person.
- Store outcomes for later error analysis.
Confidence needs calibration. A raw score of 0.90 does not automatically mean “90% likely correct.” Compare predicted confidence with actual correctness on held-out data, then choose thresholds based on risk.
💻 14. A Minimal Prototype You Can Build This Week
Choose a narrow internal workflow, such as routing feedback into product, billing, technical, and abuse queues. Begin with a small labeled spreadsheet rather than a full-scale platform.
- Gather several hundred representative examples if possible.
- Define labels and a reviewer guide.
- Make a train, validation, and held-out test split.
- Build a rules baseline.
- Test embedding similarity, a compact classifier, or a prompted small model.
- Compare quality, speed, cost, and failure types.
- Add confidence thresholds and a review queue.
def classify_feedback(text):
    cleaned = normalize(text)
    if contains_abuse_signal(cleaned):
        return {"label": "abuse", "source": "rule", "review": False}

    prediction = compact_classifier(cleaned)
    if prediction.confidence < 0.85:
        return {"label": "other", "source": "model", "review": True}

    return {"label": prediction.label, "source": "model", "review": False}
Keep the baseline. It prevents you from celebrating a sophisticated model that does not outperform a few clear rules.
🧭 15. Design the Human Review Loop Deliberately
Human review is not evidence that automation failed. It is the safety valve that lets you automate high-confidence cases while learning from uncertain ones.
Give reviewers the original input, model result, confidence, relevant evidence, and a simple correction interface. Record why the model was wrong when possible: missing policy, confusing language, bad label, out-of-scope request, or system defect.
- Review low-confidence predictions.
- Sample high-confidence predictions to catch overconfidence.
- Prioritize high-impact categories for auditing.
- Feed confirmed corrections into the next evaluation cycle.
A review queue also helps detect distribution shift: new product names, seasonal terms, changing customer behavior, and policy changes.
🔐 16. Privacy, Security, and Responsible Use
Small local models can reduce data exposure, but “small” does not automatically mean private or safe. Training data, logs, embeddings, prompts, caches, and reviewer tools can all hold sensitive information.
- Minimize the data sent to the model and redact identifiers where feasible.
- Set retention rules for prompts, outputs, and error logs.
- Use access controls for datasets and review dashboards.
- Test for uneven errors across relevant populations and language varieties.
- Do not let automated outputs make high-impact decisions without suitable oversight, policy review, and appeal processes.
- Protect against prompt injection when untrusted content reaches tools or retrieval systems.
For regulated domains, work with legal, security, and domain experts. Requirements vary by location and use case, so verify current obligations through official guidance.
📉 17. Common Mistakes That Make Small Models Look Weak
Many apparent model failures are workflow failures. Avoid these traps before concluding that only a huge model can solve the job.
- Unclear labels: the system is asked to learn a policy humans have not defined.
- One average metric: rare but costly failures disappear in aggregate accuracy.
- Too much context: irrelevant text distracts the model and slows serving.
- No abstention: forcing an answer turns uncertainty into confident-looking error.
- Training-test leakage: near-duplicate examples create unrealistically good results.
- No monitoring: quality silently degrades after product, language, or policy changes.
- Skipping validation: malformed output reaches a downstream system.
The remedy is usually better task design, data, and controls—not merely more parameters.
📊 18. Monitor the System After It Ships
Deployment begins a new experiment. Track performance over time and compare live traffic with the examples used during development.
Monitor input length, language patterns, label frequency, confidence distribution, validation failures, escalation rate, latency, and reviewer corrections. Sudden shifts are signals to investigate, not necessarily reasons to retrain immediately.
Practical monitoring questions
- Are more requests falling into “other” than before?
- Has confidence risen while reviewer agreement has fallen?
- Are certain categories receiving more overrides?
- Did a new form, campaign, or policy alter input wording?
- Can the same task now be solved with less context or a simpler rule?
Version your prompts, datasets, models, thresholds, and schemas. Reproducibility makes a production incident diagnosable.
🚀 19. Quick-Start Checklist
- Pick one repetitive decision with a bounded output.
- Write a task contract, including exclusions and escalation paths.
- Build a representative held-out evaluation set.
- Start with rules, embeddings, or a compact classifier before fine-tuning.
- Measure per-category quality, latency, cost, and abstention.
- Use structured outputs and strict validation.
- Route uncertain cases to retrieval, a stronger model, or people.
- Protect data and audit meaningful errors.
- Monitor live drift and preserve version history.
- Expand scope only after the first narrow task is dependable.
The power of a small AI model is not that it can do everything; it is that, with a carefully bounded task and disciplined system design, it can do the right thing quickly, affordably, and reliably. 🤖⚡🛠️